Algodocs

Author name: Shubhankar Biswas

PDF

Extract Tables From PDF and Scanned Documents

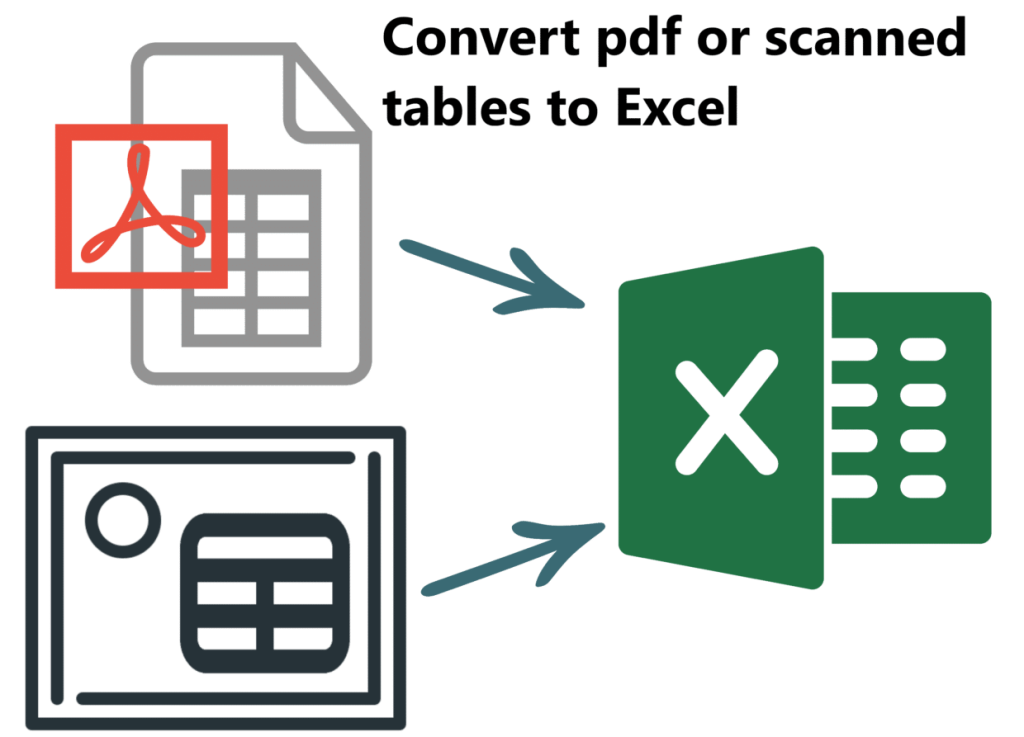
Back to Blog Table of contents On this page Extract Tables From PDF and Scanned Documents Home › Blog › PDF › Extract Tables From PDF and Scanned Documents Categories PDF Tags ocr api pdf table extraction table extraction from pdf By Shubhankar Biswas Published October 13, 2025, 11:34 Updated July 20, 2026, 07:49 Extracting tables from PDF documents is always a tedious task, especially when the documents are scanned PDFs. Even when the documents are computer-generated PDFs, it can still be a complex and annoying task, since copying a tabular text from a PDF and pasting it to an Excel spreadsheet is not always as simple as it may look. Moreover, manual data entry with human interaction involves errors in addition to wasting time. How to convert PDF or scanned tables to Excel spreadsheets? There are free online tools that you can use to convert PDF tables to Excel spreadsheets if the PDF document is a text document (not scanned). Even for system-generated PDF documents, those tools just convert a table to Excel as is, without letting you filter a table and convert it into the format you need. Especially when tables span over multiple pages of a PDF, you definitely need to trim out all unnecessary text that occurs between pages, like footer and header information. Moreover, sometimes you might need to filter out either some rows or even columns of a table itself. Imagine table extraction from scanned documents! What if those scanned documents are of low quality? Alternatively, even worse, what if those documents are images taken by a mobile device… Yes, then the task of extracting a table from such documents gets even harder… Algodocs comes to the rescue! Extract tables from PDF and scanned documents with Algodocs Algodocs allows you to extract tables from PDF or scanned documents of any complexity thanks to its flexible extracting rules. Additionally, you can convert the table into the format you need with no coding at all. With Algodocs, you can extract invoice line items, purchase order product lists, bank statement transactions, and any other financial or custom documents that contain tables. Algodocs offers a free subscription plan forever with 50 pages per month. You may check our pricing for paid subscriptions based on your document processing requirements. Algodocs has a user-friendly interface and an easy-to-use extracting rules editor. You can set up extracting rules in minutes for extracting tables from your documents. The following are the steps to follow when extracting tables from documents in Algodocs: Create an extractor by uploading a sample document In the extracting rules editor, add a rule by selecting ‘Table’ as the data type Place column separators on the table Click on the ‘Extract’ button to extract the table and apply various filters to refine and convert the extracted table into the format you need Finally, export extracted tables to Excel or JSON You may watch the screencast video tutorials below on table extraction from documents. You can check out our Video Tutorials section for more videos. In the following screencast video, we demonstrate how you can extract tables, which are in fixed or variable positions, from PDF or scanned documents. In the following screencast video, we demonstrate how you can extract tables that span over multiple pages in a PDF. In the following screencast video, we demonstrate how you can use the ‘Merge Rows’ filter to extract tables that contain rows with multiple lines. Moreover, you can benefit from integrations in Algodocs such as Google Drive, Dropbox, or Zapier, and automate your document data extraction workflow with Algodocs in minutes. Please contact us if you need any assistance. You Might Also Like Convert PDF to JSON – Convert PDF Documents to Structured JSON Objects Table of Contents Introduction Organizations in various industries widely use PDF documents, since no doubt PDF is a common document format for… Shubhankar Biswas October 13, 2025 What is a PDF Parser? A PDF Parser is a program or a library that enables end-users and organizations to parse data from native PDF documents. Often, organizations need to… Shubhankar Biswas October 13, 2025 PDF Data Extraction: The Best Tool and Techniques PDFs are ubiquitous in every organization, serving as the go-to format for sharing and exchanging business data. However, extracting, editing, or… Shubhankar Biswas October 13, 2025 Start extracting your data today No credit card required. Process up to 50 pages per month on the Forever Free plan. Book a Demo Get Started for Free
Artificial Intelligence, Data Extraction

AI Data Extraction Checklist: Transform Business with Algodocs

Back to Blog Table of contents On this page AI Data Extraction Checklist: Transform Business with Algodocs Home › Blog › Artificial Intelligence › AI Data Extraction Checklist: Transform Business with Algodocs Categories Artificial Intelligence Data Extraction Tags bank ocr deep learning digital transformation Finance ocr invoice invoice process KYC loan forms packing list ocr pdf to text sea waybill ocr web-based ai platform for data extraction By Shubhankar Biswas Published October 13, 2025, 09:25 Updated July 23, 2026, 07:33 What is AI Data Extraction? Let’s discuss data – a lot of data. Modern-day businesses are losing themselves in the sea of information. Whether it is an invoice, a contract, a weekly report, or a form, paper documents are still part of everyday life. Extracting data from such documents is a tedious, repetitive, and painful process if done manually. This is where AI data extraction comes to the rescue. It is a game-changer for anyone who has to work with several papers. Incorporating AI means data entry activities are done efficiently and there’s an increase in the accuracy and productivity of your business. Algodocs is a perfect example of an AI data extraction tool. Why? Let’s find out. Understanding Your Data: The Foundation for Successful AI Data Extraction Before you set loose the AI on your documents, I thought it’s best to discuss a little about your data. It is essential to know what type of data you are going to extract and what the process is going to be like. Identify Your Data Sources First things first: where do you store your data? The first action plan is to identify this source. Is it hidden in files and papers or dispersed in different online sites as in virtual archives? You’ll find your data in various forms: Manual records or documents that include invoices, contracts, and reports, among others. Documents in PDF files, Word documents, Excel, images, and many others. Databases that store many formats of data about any department in an organization. Assessing Data Quality Data quality is super essential for accuracy in the extraction process. Ensure that you go through your assembled data to determine whether it meets the standard of completeness, consistency, and accuracy. Check that all required data items are included. Check whether the formats, units of measurement, and terms used for data are consistent. Validating steps where errors, inconsistencies, or outliers will affect the outcome must be adopted diligently. Dedicating time to data preparation will enable laying down the key fundamentals of an AI data extraction project. Optimizing the extraction results of Algodocs, the company provides you with tools for evaluating data quality and detecting potential problems. Choosing the Right AI Data Extraction Tool Picking the right tool to extract AI data is critical to the success of any AI project. As we have seen, there are numerous strategies out there; that is why it is crucial to define your requirements precisely and compare tools based on the crucial factors. Critical Considerations for Tool Selection Accuracy: The whole idea of training an AI in the first place is to increase accuracy, isn’t it? Search for the tool with favorable accuracy characteristics, especially in the case of processing intricate and diversely formatted documents. Don’t forget about tables, crazy handwriting, or low-quality pictures. Speed: It’s important, especially in dealing with large numbers of documents that are prevalent in the modern organization. However, time translates to costs, more so when handling big data at hand or any other business. Having a fast and efficient tool can save hours, if not days off of your time. Flexibility is very important, especially for those industries that anticipate expansion. Scalability: The tool should be designed for growth which includes a higher amount of input data and scalability of business over time. Document Types: Think about the countless supported document types with your tool (PDFs, images, Word, Excel, and more). Data Formats: Verify that the tool can export information according to your preferred choice format (CSV, XML, JSON, etc.). Integrations: This is very important as technology should be compatible with the current systems and applications. In other words, a single tool could essentially serve the purpose. But if a tool can integrate with other existing systems, then that’s ideal. It integrates with frequently used business applications such as CRMs, ERPs, and data warehouses. Pricing: Analyze cost distribution for various pricing structures considering your estimated budget. Customer Support: Customer support should be reliable and available for providing technical support and answering questions at all times. Types of AI Data Extraction Tools Cloud-Based Tools AI data extraction in cloud-based is also beneficial since it is scalable, easily accessible, and mostly cheaper. These tools are stored at service providers’ central servers, and users only need an Internet connection to use them. Examples: Google Cloud Document AI, Amazon Textract, ABBYY Cloud OCR, and Algodocs. On-Premise Tools On-premise solutions allow necessary control over infrastructure, but they can be more expensive. These tools are deployed and run on the organization’s own IT systems and infrastructure. It is worth mentioning that Algodocs is a web-based tool; however, it can also be used On-premise. Examples: Kofax, OpenText, and Algodocs. Open-Source Tools Using and adapting open-source AI data extraction tools is more flexible and customizable, but implementing these tools requires technical skills. Examples: Tesseract OCR, OpenCV Mobile Apps Mobile applications usually reside on document capture and basic data mining capabilities. This is perfect for small data snippets or impromptu snapshots of information gathering. However, such tools may not work well when a large quantity of structured content, such as tables, is involved. Not to forget that handwriting style and layout complexities can cause the accuracy of such tools to drop. Examples: Google Lens or Microsoft Office Lens can scan your document and convert the text into a digital format. Making an Informed Decision Considering the following aspects and your organization’s requirements, you can choose the right AI data extraction tool for your organization. Feature Cloud-Based On-Premise Open-Source Mobile Apps Accuracy High High Varies Varies Speed High High Varies

insurance data extraction
Data Extraction, Insurance Data Extraction

Insurance Data Extraction: Automating Policy and Claim Processing with AI

Back to Blog Table of contents On this page Insurance Data Extraction: Automating Policy and Claim Processing with AI Home › Blog › Data Extraction › Insurance Data Extraction: Automating Policy and Claim Processing with AI Categories Data Extraction Insurance Data Extraction Tags ai platform for data extraction algodocs character recognition deep learning IDP Insurances Data Extraction intelligent document processing By Shubhankar Biswas Published October 12, 2025, 18:20 Updated July 23, 2026, 05:31 The modern insurance sector operates on massive volumes of information and insurance data extraction is a crucial part of insurance industry business process. Every single day, insurance carriers, third-party administrators, brokers, and agencies process thousands of files. These files range from policy applications and loss notices to medical bills, repair estimates, legal notices, and property appraisal reports. Within this ocean of paperwork lies the essential information required to underwrite risks, calculate premiums, settle claims, detect fraud, and maintain regulatory compliance. However, a significant challenge facing the insurance industry today is that up to eighty percent of this critical information arrives in unstructured or semi-structured formats. Scanned PDF files, digital images, physical paper forms, email attachments, and handwritten adjuster notes cannot be directly read or processed by traditional enterprise databases. Historically, companies relied heavily on manual data entry to transfer details from incoming documents into core operational platforms like claims management systems or policy administration suites. Manual processing creates severe bottlenecks. It inflates operational expenses, slows down service delivery, introduces human error, and frustrates policyholders who expect immediate digital service. To overcome these challenges, progressive insurance providers are transitioning toward automated insurance data extraction. Driven by advances in AI OCR, Machine Learning, and Intelligent Document Processing, modern extraction tools allow organizations to transform messy, unformatted files into structured, machine-readable digital data in seconds. This comprehensive guide explores the fundamentals of automated insurance data extraction, examining the types of documents processed, the hidden costs of manual workflows, the business benefits of artificial intelligence, and the leading software solutions shaping the market. What is Insurance Data Extraction? Insurance data extraction is the automated technology process of reading, identifying, capturing, and converting information from paper or digital insurance records into structured digital data formats. Instead of requiring human workers to manually read documents and type values into software screens, an automated insurance data extraction workflow ingests files, interprets their contents, extracts specific data fields, and exports clean data directly into core databases or enterprise applications. The insurance data extraction workflow relies on an integrated stack of advanced technologies: Document Ingestion: The system collects inbound files from multiple channels, including email inboxes, mobile application uploads, scanned physical mail, cloud storage, or secure web portals. Optical Character Recognition (OCR) and AI OCR: Legacy OCR converts scanned document images into text strings. Next generation AI OCR goes further by recognizing complex handwriting, low-resolution scans, and non-standard typography. Intelligent Document Processing (IDP): Combining artificial intelligence with natural language processing, Intelligent Document Processing understands the context and semantic meaning of words. It recognizes that a dollar figure located next to the word deductible represents a specific financial field rather than a premium payment. Machine Learning and Field Validation: Machine learning algorithms continuously improve extraction accuracy over time. Automated validation rules cross check extracted policy numbers, dates, and mathematical totals against internal enterprise databases to verify accuracy. Data Export: Clean, structured data is formatted into structured payloads such as JSON, XML, or CSV, and delivered directly to core policy or claims platforms via APIs. Through AI insurance data extraction, carriers can automate repetitive administrative steps, reduce turnaround times, and establish seamless insurance workflow automation across every department. Types of Documents Used in Insurance Industry for Insurance Data Extraction Insurance carriers handle a vast assortment of forms, reports, and contracts. Each document type possesses unique layouts, terminology, and data extraction requirements. Automated insurance document processing systems are designed to process diverse document types efficiently. 1. Policy Documents and Applications Policy applications and insurance binders represent the foundational agreements between policyholders and carriers. Extracting accurate data during policy origination is crucial for setting terms and issuing coverage. Key documents include: ACORD 125 Applications: The standard commercial insurance application form containing applicant business details, policy effective dates, location details, and requested coverage limits. Policy Schedules and Declarations Pages: Summary pages detailing coverage types, policy numbers, named insureds, endorsement listings, and premium amounts. Endorsement Forms: Amendments to existing policy contracts that modify coverage terms, add new insured assets, or change liability limits. Accurate policy data extraction ensures that customer profiles, coverage clauses, and premium figures match internal records without requiring manual entry. 2. Insurance Claims and Loss Notices When policyholders suffer a loss, rapid claims intake is essential for customer satisfaction. Automated insurance claims data extraction parses critical details from early claims documentation: First Notice of Loss (FNOL) Reports: Initial notifications submitted by policyholders or agents detailing how, when, and where an incident occurred. ACORD Loss Notices: Standardized notices such as the ACORD 2 Automobile Loss Notice or ACORD 3 Property Loss Notice, capturing policy details, driver information, and loss descriptions. Incident and Police Reports: Official law enforcement collision records containing narrative descriptions, driver statements, weather conditions, and citations. Automating insurance claims data extraction accelerates claim registration, enabling immediate assignment to claims adjusters or automated decisioning engines. 3. Medical Records and Healthcare Billing Forms Health, workers compensation, and personal injury protection claims involve complex clinical and billing records. These documents combine typed text, medical terminology, complex codes, and handwritten notes: CMS-1500 and UB-04 Forms: Standard medical billing claim forms used by physicians, medical practices, and institutional healthcare providers. Explanation of Benefits (EOB): Statements sent by health plans explaining covered services, approved amounts, deductible applications, and patient responsibility. Clinical Discharge Summaries and Doctor Notes: Narrative medical charts containing diagnoses, treatment histories, and surgical notes. Automated extraction engines capture critical diagnostic codes such as ICD-10, procedure codes such as CPT, billing line items, and provider identification numbers to streamline health claims auditing. 4. Underwriting Documents and Financial Statements Underwriters must review complex

Data Extraction, Image Data Extraction, Legal Document Extraction

Data Extraction for Legal Industry : How Intelligent Document Processing (IDP) Can Transform Legal Industry Document Workflow

Back to Blog Table of contents On this page Data Extraction for Legal Industry : How Intelligent Document Processing (IDP) Can Transform Legal Industry Document Workflow Home › Blog › Data Extraction › Data Extraction for Legal Industry : How Intelligent Document Processing (IDP) Can Transform Legal Industry Document Workflow Categories Data Extraction Image Data Extraction Legal Document Extraction Tags AI algodocs data extraction IDP intelligent document processing Legal Industry machine learning By Shubhankar Biswas Published October 12, 2025, 16:36 Updated July 22, 2026, 10:08 The global law and legal services industry is expected to reach $1,591.56 billion by the end of 2032, according to a report. The legal industry primarily relies on information, with activities such as contracts, court filings, discovery documents, and legal research forming the foundation of every case and legal process. These tasks involve a significant amount of documentation and data. However, managing this mountain of data has always been a challenge for the legal industry. Traditional methods of manual review and data entry are time-consuming, expensive, and prone to human error. Fortunately, technologies such as Artificial Intelligence (AI) and Intelligent Document Processing (IDP) have revolutionized how law firms and legal departments handle data extraction from multiple documents and files, significantly improving their work efficiency. In this blog, we will discuss how IDP (Intelligent Document Processing) can enhance document processing efficiency for the legal industry and why Algodocs AI is an ideal document processing solution that can elevate data extraction and document management for legal service business owners. Data Extraction for Legal Industry : A Major Challenge for Law Firms and Legal Service Providers Data is the lifeblood of the legal profession and law firms. Whether it involves extracting key clauses from contracts, identifying vital information in discovery documents, or analyzing legal precedents, the ability to quickly and accurately extract data is critical. This is where IDP (Intelligent Document Processing) for the legal industry comes into play. IDP automates the process of identifying and extracting relevant information from various legal documents, transforming unstructured data into a structured, usable format. This process is vital for several reasons: Efficiency: Manual data extraction is notoriously slow and labor-intensive. IDP and AI automate this process, freeing legal professionals to focus on higher-value tasks like strategy and client interaction. Accuracy: Human error is inevitable when manually extracting data. IDP and AI solutions, such as Algodocs, significantly reduce errors, ensuring data integrity and reliability. Cost Savings: Manual data extraction is not cost-effective, especially when dealing with bulk documents, which are abundant in the legal industry. By automating data extraction, law firms and legal departments can reduce overhead costs and improve their bottom line. Improved Decision-Making: Extracted data can be analyzed to provide valuable insights, enabling lawyers to make more informed decisions and develop stronger legal strategies. The Limitations of Traditional Data Extraction Methods Before the advent of technologies like IDP, AI, or OCR, legal professionals relied heavily on manual methods for data extraction. These methods, while sometimes necessary, come with significant challenges: Time-Consuming: Sifting through hundreds or thousands of pages of legal documents to locate and extract specific information is tedious and time-intensive. Error-Prone: Manual data entry is susceptible to human error, which can have severe consequences in legal matters. Inconsistent: Manually extracted data can vary in format and accuracy depending on the individual performing the task, leading to inconsistencies and difficulties in analysis. Costly: Labor costs associated with manual data extraction can be significant, particularly for large-scale legal projects. These limitations highlight the need for a more efficient, accurate, and cost-effective solution for data extraction in the legal industry. This is where IDP steps in. How IDP Works IDP leverages the power of artificial intelligence (AI) technologies such as machine learning (ML), natural language processing (NLP), computer vision, and OCR to automate data extraction from legal documents. Here’s how it works: Document Ingestion: IDP solutions can ingest various document formats, including PDFs, scanned images, Word documents, handwritten notes, and emails. Pre-Processing: Documents undergo pre-processing steps like optical character recognition (OCR) to convert scanned images into machine-readable text and remove noise. Data Extraction: NLP and ML algorithms identify and extract relevant information based on pre-defined rules or learned patterns, such as clauses, dates, names, addresses, and financial figures. Data Validation: Extracted data is validated using techniques like cross-referencing and pattern matching to ensure accuracy. Output: The validated data is exported into a structured format, such as a spreadsheet or database, for easy analysis and use. The Benefits of IDP for Legal Data Extraction IDP offers numerous benefits for legal professionals seeking to streamline data extraction: Increased Efficiency: Automates the data extraction process, significantly reducing time and effort. Improved Accuracy: Minimizes human intervention, reducing errors and ensuring greater precision. Enhanced Consistency: Provides consistent data extraction across all documents, regardless of complexity. Reduced Costs: Cuts labor costs by automating repetitive tasks. Better Risk Management: Identifies potential risks and liabilities within documents. Improved Compliance: Ensures adherence to legal and regulatory requirements. Enhanced Client Service: Enables legal professionals to deliver faster, more accurate services. Use Cases of IDP in the Legal Industry Contract Analysis: Automatically extracts key details like parties, dates, payment terms, and clauses. Due Diligence: Speeds up the review process for mergers and acquisitions by analyzing contracts and financial statements. Discovery: Analyzes vast amounts of discovery data to identify relevant information and patterns. Legal Research: Automatically extracts relevant information from case law, statutes, and legal journals. Compliance Monitoring: Ensures documents adhere to regulations and internal policies. Choosing the Right IDP Solution To maximize its benefits, selecting the right IDP solution is crucial. Consider factors such as accuracy, scalability, integration, security, user-friendliness, and vendor support when making your choice. Algodocs: A Leading IDP Solution for Legal Industry Algodocs is a powerful IDP solution tailored to address the challenges of data extraction in the legal field. It automates document processing, ensures high accuracy, offers customizable data extraction, and integrates seamlessly with existing systems. By implementing Algodocs, law firms and legal departments can enhance efficiency, accuracy, and cost-effectiveness, enabling better outcomes for clients. Conclusion Intelligent Document Processing is transforming the legal industry by automating critical processes. By improving efficiency, accuracy, and cost-effectiveness, IDP empowers law firms and legal departments to

Healthcare

Healthcare Data Extraction: Improving Healthcare Document Workflow with AI and IDP In 2025: A Case Study

Back to Blog Table of contents On this page Healthcare Data Extraction: Improving Healthcare Document Workflow with AI and IDP In 2025: A Case Study Home › Blog › Healthcare › Healthcare Data Extraction: Improving Healthcare Document Workflow with AI and IDP In 2025: A Case Study Categories Healthcare Tags algodocs data extraction deep learning healthcare intelligent document processing machine learning ocr api By Shubhankar Biswas Published October 12, 2025, 16:30 Updated July 20, 2026, 10:11 Healthcare data extraction has always been a challenge for hospitals, healthcare providers, and insurance companies. Extracting data from multiple documents was a complex task. However, the advent of AI and Intelligent Document Processing (IDP) technologies has significantly impacted how the healthcare industry processes data from various healthcare documents. The healthcare industry is a vast sea of data. Every patient interaction, medical procedure, and insurance claim relies on information. This data, locked within various document formats, holds immense potential to improve patient care, streamline healthcare operations, and drive innovation. However, extracting this valuable information from diverse healthcare documents has traditionally been laborious, error-prone, costly, and inefficient. This is where technologies like IDP, AI, Machine Learning (ML), Large Language Models (LLM), and Optical Character Recognition (OCR) come into play. With these innovative technologies, we have improved data extraction for the healthcare industry. According to a recent report, the healthcare industry is a USD 5,862.1 billion industry and is expected to reach USD 9,245.8 billion by 2033. Another report by Deloitte suggests that AI technologies can save USD 360 billion in costs in the USA by next year. The healthcare industry generated up to 2.3 zettabytes of data worldwide in 2020. In this blog, we will discuss how AI is changing data extraction for the healthcare industry across the globe and the technologies and tools behind this technological advancement. The Diverse Landscape of Healthcare Documents The healthcare industry is inundated with various documents, each containing critical information crucial for patient care, administration, and research. Understanding these documents is the first step in effectively leveraging data extraction. Let’s delve into the key document types: Medical Bills Medical bills are more than just invoices; they are detailed records of services rendered to a patient. They contain crucial information, including: Patient Demographics: First Name, Last Name, address, date of birth, insurance, and other crucial details. Provider Information: Name, address, National Provider Identifier (NPI), etc. Service Details: Procedure codes (CPT/HCPCS), diagnosis codes (ICD-10), dates of service, quantities, and descriptions. Charges and Payments: Itemized charges, adjustments, insurance payments, patient responsibility, payment methods, tax details, etc. Efficiently extracting data from medical bills is vital for revenue cycle management, claims processing, cost analysis, and identifying trends in healthcare spending. Accurate data extraction ensures timely reimbursements, reduces claim denials, and provides insights into cost-effective care delivery. Handwritten Bills Despite the growing adoption of Electronic Health Records (EHRs), handwritten bills persist in many healthcare settings, particularly in smaller practices or during field visits. Many developing Asian countries, as well as developed countries, still rely on handwritten bills. These bills often contain information such as: Patient Information: Basic details like first name, last name, sometimes age or contact information, dates, etc. Treatment Details: Brief descriptions of services provided, often in abbreviated form. Charges: Handwritten amounts for each service or an overall total. Extracting data from handwritten bills presents a unique challenge due to variations in handwriting styles, abbreviations, and the potential for smudges or illegible entries. Advanced OCR coupled with Natural Language Processing (NLP) is essential for accurate data extraction from these documents. Patient Forms Patient forms are the cornerstone of patient intake and data collection. They gather essential information that forms the basis of a patient’s medical record. Sometimes these forms are filled with handwritten data, which presents a challenge for data extraction. Though the majority of patient forms are computer-generated, in many cases, they are handwritten. Common types of patient forms include: Registration Forms: Collect basic demographics, insurance information, and emergency contacts. Medical History Forms: Document past illnesses, surgeries, allergies, medications, and family history. Consent Forms: Obtain patient authorization for treatment, procedures, or release of information. HIPAA Forms: Ensure compliance with the Health Insurance Portability and Accountability Act regarding patient privacy. These forms often contain valuable information such as first name, last name, address, body weight, blood group details, current health issues, and previous diagnoses. They often contain a mix of structured (checkboxes, multiple-choice) and unstructured (free-text) data. Effective data extraction from these forms relies on advanced form recognition and NLP techniques to capture both types of information accurately. Health Insurance Documents Health insurance documents, including Explanation of Benefits (EOBs) and insurance cards, are crucial for understanding a patient’s coverage, verifying eligibility, and processing claims. They contain: Insurance Cards: Provide member ID, group number, plan type, contact details, and other information. Explanation of Benefits (EOBs): Detail how a claim was processed, including allowed amounts, co-pays, deductibles, and reasons for any denials. Data extraction from insurance documents enables accurate billing, reduces claim rejections, and helps patients understand their financial responsibilities. It also provides valuable data for insurance companies to analyze utilization patterns and manage risk. Other Vital Documents Beyond these core document types; the healthcare ecosystem encompasses a multitude of other documents: Lab Reports: Contain results of diagnostic tests, including blood work, imaging, and pathology reports. Prescription Forms: Detail medication name, dosage, frequency, and refill information. Referral Forms: Facilitate specialist consultations and continuity of care. Discharge Summaries: Provide a comprehensive overview of a patient’s hospital stay, including diagnosis, treatment, and follow-up instructions. Clinical Notes: Document physician observations, assessments, and treatment plans. Each document plays a unique role in patient care and administration. This diverse range provides a holistic view of a patient’s journey, enabling better care coordination, research, and population health management. How AI, ML, and IDP Leverage Healthcare Data Extraction The traditional approach to extracting data from these diverse healthcare documents has been manual data entry, a process fraught with challenges. However, the emergence of AI, ML, and IDP has revolutionized data extraction, offering a more efficient, accurate, and scalable solution. Try Algodocs AI data extraction platform to extract data from variou types of documents. Sign up

Data Extraction, PDF

PDF Image Extraction: A Comprehensive Guide To Extracting Image Data From Scanned Pdf Files In 2025

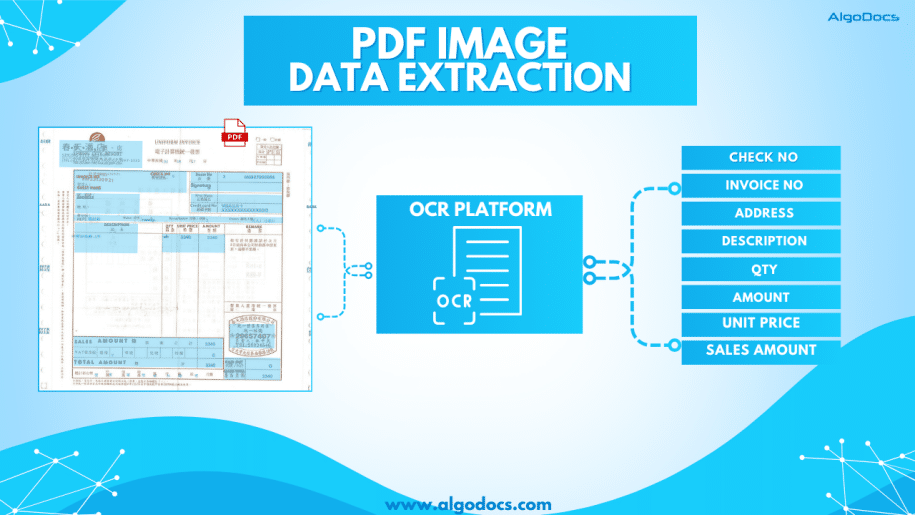
Back to Blog Table of contents On this page PDF Image Extraction: A Comprehensive Guide To Extracting Image Data From Scanned Pdf Files In 2025 Home › Blog › Data Extraction › PDF Image Extraction: A Comprehensive Guide To Extracting Image Data From Scanned Pdf Files In 2025 Categories Data Extraction PDF Tags ai platform for data extraction algodocs image data extraction pdf image extraction By Shubhankar Biswas Published September 1, 2025, 09:19 Updated July 23, 2026, 05:45 PDF image extraction is a challenging process. Without proper tools and technology, this process can be tedious and prone to errors, which can eventually lead to a loss of money and time for an organization. PDFs have always been one of the most convenient and reliable ways to store, carry, and share information with others. However, lots of data in PDFs is locked as scanned images. When you have multiple images or scanned documents to deal with, it becomes easy for a person to bind all these multiple image documents into one with the PDF format.The PDF document format is widely used for business communication and personal document sharing as well.Unlike other document formats such as. doc, CSV, or TXT formats, PDFs are considered much safer because they can be locked with a password, or data can’t be edited or altered unless you allow it. However, one of the most common challenges faced when dealing with PDFs is extracting data from scanned PDF images. Scanned PDFs are essentially images of text, making it difficult to directly copy or edit the content. This is where the concept of PDF image extraction comes into play. In this blog, we’ll explore how to extract data from scanned PDF images, the tools and techniques involved, and why this process is crucial for efficient data management. What is PDF Image Extraction? PDF image extraction refers to the process of extracting text, images, or other data from scanned PDF documents. Unlike standard PDFs, which contain selectable and editable text, scanned PDFs are essentially pictures of pages. This means that the text within these documents is not machine-readable unless processed using Optical Character Recognition (OCR) technology.The ability to perform PDF image extraction is essential for businesses that deal with large volumes of scanned documents, such as invoices, contracts, or historical records. By converting these images into editable and searchable text, organizations can streamline their workflows, improve data accuracy, and enhance accessibility. Why is Extracting Data from Scanned PDFs Important? Improved Data Accessibility: Scanned PDFs are often unsearchable, making it difficult to locate specific information. Extracting data from these documents makes the content searchable and easier to navigate. Enhanced Productivity: Manually typing out text from scanned documents is time-consuming and prone to errors. Automated extraction tools save time and reduce the risk of mistakes. Data Integration: Extracted data can be integrated into databases, spreadsheets, or other software systems, enabling better data analysis and decision-making. Compliance and Record-Keeping: Many industries require digital records for compliance purposes. Extracting data from scanned PDFs ensures that information is stored in a usable and retrievable format. How Does PDF Image Extraction Work? Image PreprocessingBefore extracting text, the scanned image may need to be pre-processed to improve OCR accuracy. This can include tasks like: Deskewing: Correcting the alignment of the image. Noise Reduction: Removing background noise or artifacts. Binarization: Converting the image to black and white for better contrast. Optical Character Recognition (OCR)OCR is the core technology behind PDF image extraction. It analyzes the scanned image and identifies characters, words, and sentences. Modern OCR tools are highly accurate and can recognize text in multiple languages and fonts. Text Extraction and FormattingOnce the OCR process is complete, the extracted text is formatted to match the original document’s layout. This includes preserving headings, paragraphs, tables, and other structural elements. Data Validation and CorrectionWhile OCR technology has advanced significantly, it’s not perfect. Extracted data may require manual validation and correction to ensure accuracy. Tools for PDF Image Extraction Algodocs: A powerful data extraction tool that combines the power of AI and OCR technology. It lets you extract data from scanned PDF images. ABBYY FineReader: Known for its good accuracy and support for multiple languages. Tesseract OCR: An open-source OCR engine that can be integrated into custom workflows. Online OCR Tools: Websites like Smallpdf and ILovePDF offer quick and easy solutions for occasional users. Python Libraries: For developers, libraries like PyTesseract and PDFPlumber provide flexibility for custom solutions. You can automate bulk PDF image extraction with Algodocs’ advanced AI app. Our app can extract data from blurry and distorted scanned PDF images with 10X speed without making any errors. Access For Free Best Practices for PDF Image ExtractionTo achieve the best results when extracting data from scanned PDF images, consider the following tips: Use High-Quality Scans: The quality of the scanned image directly impacts OCR accuracy. Ensure that the document is scanned at a high resolution (300 DPI or higher). Choose the Right Tool: Select an OCR tool that meets your specific needs, whether it’s a one-time extraction or a large-scale automation project. Validate Extracted Data: Always review the extracted text for errors, especially when dealing with handwritten or poorly scanned documents. Leverage Automation: For businesses handling large volumes of scanned PDFs, consider automating the extraction process using scripts or software. Protect Sensitive Data: Ensure that any tools or services used for PDF image extraction comply with data privacy regulations. Applications of PDF Image Extraction The ability to extract data from scanned PDF images has a wide range of applications across industries. Here are a few industries where PDF image extraction is widely used: Healthcare: Digitizing patient records and medical forms for easier access and analysis. Legal: Converting scanned contracts, case files, and legal documents into editable formats. Finance: Extracting data from invoices, receipts, and financial statements for accounting purposes. Education: Digitizing textbooks, research papers, and handwritten notes. Archives and Libraries: Preserving historical documents and making them searchable for researchers. Challenges in PDF Image ExtractionWhile PDF image extraction offers numerous benefits, it’s not without its challenges: Handwritten

supply chain data extraction
Logistics Data Extraction

Supply Chain Data Extraction: How IDP and AI can Transform Data Extraction and Enhance Work Efficiency

Back to Blog Table of contents On this page Supply Chain Data Extraction: How IDP and AI can Transform Data Extraction and Enhance Work Efficiency Home › Blog › Logistics Data Extraction › Supply Chain Data Extraction: How IDP and AI can Transform Data Extraction and Enhance Work Efficiency Categories Logistics Data Extraction Tags ai platform for data extraction algodocs IDP intelligent document processing Logistics Supply Chain By Shubhankar Biswas Published September 1, 2025, 09:12 Updated July 23, 2026, 06:41 The global supply chain industry is expected to reach $30.91 billion by the end of 2030, according to a report. As it continues to grow rapidly worldwide, so do the challenges of supply chain data extraction, due to the rise in business activities and the diversity of document formats and styles. In today’s dynamic global market, supply chain management is crucial for any business’s success. Companies face a constant stream of paperwork, such as invoices, purchase orders, shipping documents, and compliance reports. Manually handling this overwhelming volume of documents is not only time-consuming and tedious but also susceptible to human error. These inefficiencies increase operational costs and hinder overall productivity. This is where Intelligent Document Processing (IDP) emerges as a game-changer for the supply chain industry. By harnessing the power of Artificial Intelligence (AI), Optical Character Recognition (OCR), and Machine Learning (ML), IDP enhances the efficiency, speed, and accuracy of supply chain document data extraction. It automates document workflows with AI and ML, leading to significant improvements in data extraction accuracy, work efficiency, and ultimately, decision-making capabilities for organizations. Understanding Intelligent Document Processing (IDP) and AI for Logistics and Supply Chain Intelligent Document Processing (IDP) is an AI- and ML-driven data extraction and document workflow process that automates data extraction from various types of documents without errors. It can efficiently automate the extraction, classification, and validation of data from a wide range of documents such as bills of lading, purchase orders, invoices, shipping labels, warehouse receipts, and reports. Unlike traditional OCR, which simply converts printed text into machine-readable text, IDP leverages AI and ML to interpret, analyze, and extract meaningful data with utmost accuracy. Key Components of IDP AI and Machine Learning: These technologies empower IDP systems to learn from data patterns and continuously improve data extraction accuracy over time. This adaptive learning capability is crucial for handling diverse document formats and layouts. Optical Character Recognition (OCR): OCR serves as the foundation by converting scanned documents and images into machine-readable text, making the information accessible for further processing. Natural Language Processing (NLP): NLP enables IDP solutions to understand and categorize data within unstructured documents, such as contracts or emails, extracting key information from complex textual content. Robotic Process Automation (RPA): RPA complements IDP by automating repetitive tasks, such as data entry and validation, further streamlining workflows and reducing manual intervention. Cloud Integration: Cloud integration ensures seamless document access and processing across multiple locations and devices, fostering collaboration and accessibility. The Vital Role of IDP in Supply Chain Data Extraction Supply chain management is a critical network involving multiple stakeholders, from manufacturers and suppliers to logistics providers and retailers. Efficient document processing is essential for a seamless workflow, yet manual data extraction lacks efficiency, speed, accuracy, and cost-effectiveness when handling large volumes of supply chain documents. IDP plays a pivotal role in automating document-heavy tasks, ensuring data accuracy, and accelerating operations. Key Benefits of IDP in Supply Chain Data Extraction and Document Workflow Management Enhanced Data Accuracy: Data is the backbone of every business, and accuracy is crucial. In the supply chain sector, where data is gathered from multiple sources, extracting, sorting, and analyzing this data with precision is paramount. Manual data extraction is prone to errors, but IDP eliminates this issue with AI- and ML-driven technology, ensuring improved data integrity and reliability. Increased Operational Efficiency: Manual data extraction is inefficient and lacks scalability. IDP streamlines document processing by automating data extraction and validation, accelerating workflows, and freeing up valuable human resources for strategic tasks, significantly enhancing operational efficiency. Cost Reduction: Automation minimizes labour costs associated with manual data entry and document handling. IDP performs these tasks with little to no human intervention, optimizing costs for organizations. Improved Compliance and Data Security: Data security and compliance are critical for businesses. Many countries have enacted strict data security laws to protect user and business data. IDP ensures compliance with regulatory requirements by automating document verification and storage, minimizing the risk of compliance breaches, and protecting data from unauthorized access. Seamless Integration: IDP solutions integrate with existing ERP and supply chain management systems, creating a unified and efficient digital ecosystem, which is not feasible with manual data extraction methods. IDP Use Cases in Supply Chain Data Extraction IDP technology significantly optimizes supply chain operations by automating various document-intensive processes, including: Invoice Processing: Manual invoice data extraction is time-consuming and prone to errors. IDP automates invoice data extraction, validation, and entry into ERP systems, reducing processing time and improving accuracy. Purchase Order Management: IDP extracts critical data from purchase orders, ensuring alignment with supplier invoices and delivery receipts, preventing discrepancies, enhancing procurement efficiency, and minimizing order fulfilment issues. Bill of Lading and Shipping Documents: IDP automates data extraction from Bill of Lading, which contain crucial shipment details, reducing processing delays and improving logistics efficiency, leading to faster deliveries and better customer satisfaction. Compliance and Regulatory Documents: IDP automates document verification and storage, ensuring adherence to industry regulations and minimizing the risk of penalties and legal issues. Supplier and Vendor Management: IDP streamlines vendor onboarding by automating document verification, contract management, and performance tracking, fostering stronger vendor relationships. Packing List Processing: IDP extracts essential data such as item descriptions, quantities, weights, and dimensions from packing lists, ensuring accurate and efficient processing. Proof of Delivery (POD): IDP enhances POD data extraction by digitizing documents, extracting key details such as delivery dates, recipient signatures, addresses, and item descriptions, ensuring accurate record-keeping and improved supply chain efficiency. Implementing IDP in Supply Chain Document Workflow and Data Extraction To fully leverage the benefits of IDP for supply chain document data extraction, companies should follow a structured implementation process: Identify Document Processing Needs: Assess current

PDF

How To Convert PDF to Text Using AI: A Comprehensive Guide For 2025

Back to Blog Table of contents On this page How To Convert PDF to Text Using AI: A Comprehensive Guide For 2025 Home › Blog › PDF › How To Convert PDF to Text Using AI: A Comprehensive Guide For 2025 Categories PDF Tags ai platform for data extraction algodocs data extraction from images deep learning pdf to text By Shubhankar Biswas Published September 1, 2025, 08:25 Updated July 21, 2026, 07:03 Challenges of Converting How To Convert PDF to Text Using AI: A Comprehensive Guide For 2025PDF to Text Using AI PDF files remain the backbone of sharing textual data across various departments in businesses today. From contracts and invoices to research papers and reports, they are the preferred format for information storage and exchange. However, extracting valuable text from these documents can be a tedious and time-consuming task. This is where AI-powered solutions revolutionize PDF to text conversion. A PDF can exist in different formats, such as scanned documents, scanned images, or native PDFs that are easily searchable. Extracting data from scanned images or documents requires advanced AI technology to ensure accuracy and efficiency. In today’s business landscape, AI-based OCR technology is transforming how we interact with PDFs by offering seamless text extraction, enhanced accuracy, and increased efficiency. This guide explores the complexities and challenges of converting PDF to text using AI, along with its benefits, applications, and future advancements. Challenges of Converting PDF to Text Using AI PDF files come in different types: Native PDFs: These files allow easy editing and copying of text. Scanned PDFs: These contain embedded images of text, making manual extraction difficult.The challenge arises when dealing with scanned PDFs or image-based documents, where data cannot be directly copied or edited. Extracting information manually from thousands of PDFs is time-consuming, prone to errors, and inefficient. Traditional OCR tools offer basic character recognition but struggle with complex layouts, varied fonts, and handwritten text, often leading to inaccurate results. This highlights the need for an advanced AI-powered solution to convert PDF to text using AI efficiently. AI-Based OCR: Transforming PDF to Text Conversion Intelligent Document Processing (IDP) combines Artificial Intelligence (AI), Natural Language Processing (NLP), and Machine Learning (ML) to enhance traditional OCR capabilities. Instead of merely recognizing characters, AI-powered solutions understand document structures, identifying elements like headings, paragraphs, tables, and images while preserving formatting and ensuring high accuracy. AI-powered OCR tools convert PDFs to text with unmatched precision, making document processing easier and more efficient. How AI-Based OCR Works to Convert PDF to Text The efficiency of AI-based OCR lies in its sophisticated algorithms. Here’s how it works: Document Preprocessing: The PDF undergoes enhancement to remove noise, correct skew, and improve readability. Layout Analysis: AI analyzes the document structure, recognizing sections, columns, and tables. Enhanced OCR with AI: Unlike traditional OCR, AI-driven engines recognize a wide range of fonts, styles, and even handwritten text with high precision. Natural Language Processing (NLP): AI interprets the extracted text, corrects errors, and ensures contextual accuracy. Text Extraction & Formatting: The extracted text is presented in readable formats like plain text, HTML, or structured data (e.g., JSON) while preserving its original formatting. Benefits of Using AI to Convert PDF to Text With our Algodocs Generative AI Feature You Can Convert PDF To Text With Few Prompts. Try Our Free App Today AI-powered solutions provide numerous advantages, including: High Accuracy: Minimizes errors and reduces the need for manual corrections. Efficiency: Automates extraction, saving time and resources. Enhanced Data Accessibility: Converts PDFs into text for easy analysis and decision-making. Scalability: Processes large volumes of PDFs quickly and efficiently. Cost Savings: Reduces labor costs and boosts productivity. Seamless Integration: Extracted text can be integrated into various applications and systems. Applications of AI-Based PDF to Text Conversion AI-powered OCR tools are used across industries: Legal: Extracts text from contracts and case files. Finance: Processes invoices and financial reports. Healthcare: Extracts data from medical records and patient forms. Education: Converts research papers and textbooks into accessible formats. Government: Processes official documents and forms. Research: Extracts insights from scientific publications. Data Entry Automation: Automates data extraction from forms and documents. Content Management: Makes PDF content searchable and accessible. Key Challenges and Considerations in Converting PDF to Text Using AI While AI-based OCR significantly improves PDF to text conversion, some challenges remain: Complex Layouts: Multi-column formats and tables can still pose difficulties. Low-Quality Scans: Poorly scanned documents and handwritten text may require additional processing. Security & Privacy: Choose AI tools that prioritize data security. Cost: Pricing varies based on features and processing volume. Choosing the Right AI Tool to Convert PDF to Text When selecting an AI solution, consider: Accuracy: High precision in text extraction. Speed: Quick and efficient processing. Scalability: Ability to handle large document volumes. Features: Support for table extraction, formatting preservation, and multiple languages. Security: Strong data protection measures. Cost: Budget-friendly pricing models. Integration: Compatibility with existing workflows and systems. Algodocs AI: Simplifying PDF to Text Conversion One of the most powerful AI-based OCR tools is Algodocs AI. It combines AI and traditional OCR to extract data from various document types, including PDFs, scanned images, and complex layouts. Algodocs AI ensures high accuracy and efficiency, allowing users to extract text, tables, and structured data with ease. It simplifies PDF to text conversion, making it effortless to unlock valuable information within your documents. Algodocs AI makes it easier than ever to convert PDFs to text using AI, streamlining business workflows. The Future of AI in PDF to Text Conversion The field of AI-based OCR is constantly evolving. Future advancements will further enhance accuracy, efficiency, and functionality. With the integration of Robotic Process Automation (RPA) and cloud computing, AI solutions will enable seamless automation and data analysis across industries. Conclusion Converting PDFs to text using AI is a game-changing innovation, streamlining workflows, reducing errors, and improving data accessibility. With applications across multiple industries, AI-powered solutions like Algodocs AI are leading the way in automated document processing. As businesses become increasingly data-driven, leveraging AI to convert PDF to text will remain a crucial tool for unlocking and utilizing

Best Intelligent Document Processing Software
intelligent document processing

Best Intelligent Document Processing Software in 2025: Features, Benefits & Comparison

Back to Blog Table of contents On this page Best Intelligent Document Processing Software in 2025: Features, Benefits & Comparison Home › Blog › intelligent document processing › Best Intelligent Document Processing Software in 2025: Features, Benefits & Comparison Categories intelligent document processing By Shubhankar Biswas Published September 1, 2025, 07:45 Updated July 23, 2026, 06:23 Imagine having over 10,000 documents on your desk and needing to extract data from all of them within a limited timeframe. How would you manage? Manually processing such a large volume of documents could take weeks or even months, increasing the likelihood of errors along the way and finding best intelligent document processing software can be a real challenge. Fortunately, with AI-powered Intelligent Document Processing (IDP) software, you can extract data from multiple documents with high accuracy and efficiency while automating the entire process—allowing you to focus on more critical tasks. With IDP, you can seamlessly extract data from invoices, contracts, medical records, legal documents, and more, significantly improving speed, accuracy, and efficiency. This not only enhances business performance but also helps organizations achieve their goals more effectively. By leveraging Artificial Intelligence (AI), Machine Learning (ML), and Optical Character Recognition (OCR), IDP automates document classification, data extraction, and processing—making your workflow smoother and more efficient. However, with so many Intelligent Document Processing solutions available in the market, selecting the right tool for your business can be overwhelming. That’s why we’ve created this guide—to help you understand the key factors to consider when choosing an IDP solution and why Algodocs stands out as the best Intelligent Document Processing platform for data extraction for your business. What is Intelligent Document Processing? Intelligent Document Processing (IDP) is an advanced document processing technology that combines Artificial Intelligence (AI) and Machine Learning (ML) with traditional Optical Character Recognition (OCR) to automate the extraction, classification, and organization of data from both structured and unstructured documents. Unlike traditional OCR, which only identifies printed text, IDP solutions leverage Machine Learning and Natural Language Processing (NLP) to understand context, enhance accuracy, and seamlessly integrate with existing enterprise systems. One of the key advantages of Intelligent Document Processing is its ability to extract data even from blurry, skewed, or unstructured documents—capabilities that traditional OCR lacks, as it primarily relies on structured formats. Additionally, IDP software can integrate with third-party applications through APIs or prebuilt integrations, enabling real-time data transfer between external systems and IDP platforms. This not only enhances efficiency but also saves organizations valuable time and operational costs. How Intelligent Document Processing Software Works intelligent Document Processing (IDP) primarily leverages Artificial Intelligence (AI), Machine Learning (ML), and Large Language Models (LLM) combined with Optical Character Recognition (OCR) to extract and process data from PDFs, scanned images, invoices, bills, purchase orders, and other documents. It captures unstructured data from these sources and transforms it into a structured format that is easily readable and interpretable by computers. Additionally, IDP software automates the entire document processing workflow by integrating with third-party applications, significantly reducing the time required for data extraction and processing. The true power of Intelligent Document Processing lies in its AI and ML capabilities, which are trained on vast datasets to recognize complex text formats and document layouts. This enables efficient data extraction from various types of documents, including blurry or low-quality images. The LLM (Large Language Model) within IDP software is continuously trained to enhance extraction accuracy across different document types and file formats, ensuring greater precision and reliability. Key Benefits of IDP Software Intelligent Document Processing (IDP) software empowers businesses to maximize productivity and efficiency by eliminating the repetitive, manual tasks associated with data extraction. Below are the key benefits that make IDP software a valuable investment for organizations: Automation: IDP tools streamline data extraction and preprocessing, eliminating the need for manual work. By automating these processes, businesses save time, resources, and costs while allowing employees to focus on more critical tasks. Accuracy: Manual data extraction is prone to human errors, which can lead to costly mistakes. IDP platforms leverage AI and ML technologies to minimize errors, ensuring high accuracy in data extraction and processing. Scalability: IDP software allows businesses to process large volumes of documents without requiring additional manpower. Organizations can scale their document processing operations up or down based on demand, reducing unnecessary expenses. Seamless Integration: IDP software integrates effortlessly with existing business applications, facilitating smooth data exchange across platforms. With APIs and prebuilt integrations, IDP platforms can connect with ERP, CRM, HR, and other enterprise systems. Data Security: Protecting sensitive business and financial data is crucial. IDP software ensures compliance with security regulations by maintaining encrypted and organized records accessible only to authorized personnel. Best Intelligent Document Processing Software Algodocs: The Leading IDP Solution: Algodocs is the best AI-based Intelligent Document Processing software that enables businesses to automate data extraction from invoices, bills, financial documents, HR forms, purchase orders, and other document types with high accuracy and speed. It leverages AI-driven OCR and ML-based data extraction techniques to streamline workflows and improve operational efficiency. With its new Generative AI feature, users can extract data from invoices, bills, bank statements, and ID cards effortlessly. Key Features of Algodocs: AI-Powered Data Extraction: Extracts tables, fields, selection marks, and key information from structured and unstructured documents. Customizable Workflows: Users can define specific extraction rules to match their business needs. Support for Multiple Formats: Works with PDFs, scanned images, invoices, receipts, contracts, and more. Cloud-Based & Secure: Ensures data security with end-to-end encryption and cloud accessibility. Integration with Other Applications: Seamlessly integrates with ERP, accounting tools, CRMs, and other business software. With its user-friendly interface, high accuracy, and automation capabilities, Algodocs is an ideal solution for businesses looking to enhance their document processing efficiency. Nanonets Nanonets is an IDP platform that allows users to build and train custom models for document processing. It supports automation workflows, integrates with various APIs, and ensures seamless data extraction for industries like finance, healthcare, and logistics. Docsumo Docsumo specializes in processing financial and business documents, such as invoices, bank statements, and tax forms. It offers pre-trained models that enhance data extraction accuracy while

Data Extraction, Optical Character Recognition

What Is Zonal OCR? An Easy Guide to Understanding Zonal OCR and How It Works.

Back to Blog Table of contents On this page What Is Zonal OCR? An Easy Guide to Understanding Zonal OCR and How It Works. Home › Blog › Data Extraction › What Is Zonal OCR? An Easy Guide to Understanding Zonal OCR and How It Works. Categories Data Extraction Optical Character Recognition Tags character recognition ocr api By Shubhankar Biswas Published September 1, 2025, 07:27 Updated July 20, 2026, 11:11   Processing data from bulk documents can be an annoying and time-consuming task if you have to extract this data manually. But with the help of modern technology such as optical character recognition, you can extract data from these documents easily. There is another part of OCR technology known as zonal OCR, which lets you extract specific data from specific sections of a PDF or scanned image. That is known as zonal OCR. So, what is Zonal OCR, and how does it work? We will discuss more in detail below. Understanding the Basics: OCR VS Zonal OCR? Before we explain what zonal OCR is, we first need to understand what OCR technology is and how it works.OCR stands for Optical Character Recognition. It was developed in the late 70s and started to gain traction in the late 80s. One of the main reasons it gained popularity in the 80s was because it started to be used by banks to extract data from various types of documents, which helped them save time and improve data extraction quality. Later, OCR was adopted in business, marketing, and other industries all around the world.The main function of traditional OCR technology is to convert different types of documents such as scanned paper documents, PDFs, or images into editable and searchable data. An OCR tool “reads” text on an image and turns it into digital letters that are editable on a computer. For example, if you scan a printed invoice and use OCR software, the software can pull out the name, address, and price from that scanned image and turn it into usable text. But classic OCR tools extract all the presented data in a document, and you can’t control what to extract and what not to—that’s where zonal OCR comes into play. What Is Zonal OCR? Now that we know what OCR is, let’s answer the main question—what is zonal OCR?Zonal OCR is a more focused and intelligent version of regular OCR. Instead of scanning an entire document and pulling out all the text, zonal OCR extracts data from specific areas or “zones” of a document. That’s why it is called zonal OCR or is known as template OCR as well. These zones are predefined sections where certain types of information always appear.Think of it like this: if every invoice you receive has the “Invoice Number” in the top right corner, Zonal OCR can be trained to look at just that area and pull the number out automatically. It ignores everything else and goes straight to the point. That makes it incredibly efficient and reliable for high-volume document processing. One of the major highlights of zonal OCR is that it is more accurate compared to traditional OCR. So, How Does Zonal OCR Work? Let’s break down how Zonal OCR works in a step-by-step process: Template Definition: First, you define zones on a document template. These zones are rectangular areas where key data lives—like names, dates, invoice numbers, etc. Document Scanning: When a new document comes in, it is scanned or uploaded to the system. Zone Detection: The Zonal OCR engine locates the defined zones on the document. Data Extraction: The engine reads the text from those zones and extracts it into a structured format like CSV, JSON, or directly into a database. Post-Processing: Extracted data can be validated, verified, or even pushed into downstream workflows like CRMs, ERPs, or RPA systems. Features of Zonal OCR What makes zonal OCR so powerful is its accuracy. Traditional OCR might pick up irrelevant text or make errors when faced with complex layouts. But zonal OCR knows exactly where to look because we have already defined the zone from where data needs to be picked and extracted. That means fewer errors, faster processing, and smoother workflows. Real-World Example: Zonal OCR For Medical Billing Imagine a hospital that receives thousands of medical bills every month. These documents have patient names, billing codes, diagnosis details, health insurance info, and payment terms.Using zonal OCR, the hospital can define zones on its standard bill layout:• Top left for patient name• Top right for bill number• Centre zone for treatment codes and costs• Bottom section for insurance informationEach incoming bill gets processed automatically. The software reads just those parts and enters the data into the hospital’s billing system. No manual typing. No human errors. Just fast, accurate data extraction. Where Zonal OCR Is Used Zonal OCR is widely used in different industries that handle large volumes of documents with structured layouts. Here are some common use cases:• Healthcare: Extracting patient data, diagnosis reports, medical codes, and insurance details from forms and bills.• Finance: Pulling out transaction info, invoice numbers, and payment dates from bank statements or receipts.• Logistics: Reading shipping labels, barcodes, and delivery addresses.• Legal: Extracting case numbers, parties involved, or dates from legal filings.• Retail: Processing receipts and purchase orders for inventory management. Why Businesses Need Zonal OCR Now that you understand what zonal OCR is, let’s explore why it’s such a vital tool for modern businesses.Saves TimeManual data entry is slow and expensive. Zonal OCR does in seconds what might take a person several minutes or hours.Reduces ErrorsHumans make mistakes, especially when tired or rushed. Zonal OCR provides consistent and accurate results.Scales EasilyWhether you process 10 or 10,000 documents a day, zonal OCR can handle it. It grows with your needs.Easy IntegrationMost zonal OCR systems can plug right into your existing software—like CRMs, ERP tools, or cloud databases.Improves ComplianceAccurate document processing means better audit trails, stronger recordkeeping, and improved compliance with industry regulations. Zonal OCR vs Full-Page OCR You might be wondering, “Why not just use

Scroll to Top