Algodocs

algodocs

Intelligent Document Processing Trend 2027
intelligent document processing

Intelligent Document Processing Trends 2027: How IDP Is Shifting

Back to Blog Table of contents On this page Intelligent Document Processing Trends 2027: How IDP Is Shifting Home › Blog › Intelligent Document Processing › Intelligent Document Processing Trends 2027: How IDP Is Shifting Categories Intelligent Document Processing Tags IDP AI Algodocs By Shubhankar Biswas Published September 24, 2026, 10:15 Intelligent Document Processing (IDP) has become more than a tool for scanning paper and pulling text out of PDFs, images, and handwritten notes. By 2027, IDP is turning into a knowledge driven, agentic, and multimodal enterprise capability. It reads documents, retrieves context, answers questions in plain language, and triggers the next step in a business process automatically. This shift is playing out across every major industry. According to MarketsandMarkets‘ Intelligent Document Processing market forecast, the global IDP market is projected to grow from USD 1.1 billion in 2022 to USD 5.2 billion by 2027, a compound annual growth rate (CAGR) of 37.5%. Longer term forecasts vary widely depending on how each research firm defines the category. Straits Research projects the market could reach USD 37.28 billion by 2033, while IMARC Group estimates USD 46.23 billion by the same year. The exact endpoint differs by analyst, but the direction is consistent: double digit growth driven by AI adoption, automation demand, and the need to process unstructured data at scale. Behind these numbers is a simple truth. Organizations want document intelligence that is accurate, governed, conversational, and integrated into end-to-end business automation, not a point tool bolted onto a legacy workflow. This article breaks down the ten trends reshaping Intelligent Document Processing heading into 2027, what the data actually says, and where the industry still has open problems to solve. TL;DR Summary IDP is moving beyond basic extraction. By 2027 it will function as a knowledge driven and multimodal system that understands documents, retrieves context, answers questions, and triggers business actions. Agentic AI takes IDP from extraction to action. Instead of only extracting fields, AI agents can validate data, flag discrepancies, request missing information, and route exceptions through multi step workflows. Retrieval Augmented Generation (RAG) is becoming the core knowledge layer for IDP, grounding AI answers in enterprise documents and improving traceability. Multimodal AI is improving document understanding by processing text, tables, handwriting, signatures, images, and complex layouts together rather than as plain text. Hyperautomation connects IDP with RPA, process mining, ERP, and CRM systems to automate document driven processes end to end. Low code and no code platforms are making IDP accessible to business users who are not trained programmers or data scientists. Domain specific small language models (SLMs) offer a cost efficient, private alternative to large general purpose models for document processing. Governance and responsible AI are becoming essential as IDP systems take on more autonomous decision making. Conversational IDP lets users ask questions in natural language and receive answers grounded in enterprise documents. GraphRAG improves reasoning across complex documents by connecting entities, clauses, dates, and regulations in a knowledge graph. Privacy preserving and sustainable IDP, including edge processing and efficient models, is gaining importance as data residency rules tighten. The core shift by 2027 is from digitizing documents to building governed, intelligent workflows that balance automation, accuracy, security, and human oversight. Trend 1: Agentic AI Moves IDP From Manual Review to Automated Action The most significant shift in IDP is the rise of agentic AI. Traditional IDP extracts data, agentic IDP reasons, plans, and executes multi-step workflows. It can read an invoice, compare it against ERP records, flag a mismatch, request the missing purchase order number, and forward the exception to the right team, all without a human clicking through each step. Gartner forecasts that agentic AI will be embedded in 33% of enterprise software applications by 2028, up from less than 1% in 2024. According to UiPath’s State of the Agentic Automation Professional report, a majority of automation professionals say they are already using or experimenting with agentic automation in production or pilot environments. Gartner also cautions that more than 40% of agentic AI projects could be canceled by the end of 2027 due to unclear value, rising costs, and weak risk controls. Many vendors are relabelling existing RPA or chatbot products as agentic without real autonomous capability, a practice Gartner calls agent washing. For document heavy industries such as banking, insurance, healthcare, legal, logistics, and government, the opportunity is real, but success depends on confidence scoring, human in the loop escalation, audit trails, and continuous supervision rather than autonomy for its own sake. Trend 2: RAG Becomes the Knowledge Layer for Document Intelligence Retrieval Augmented Generation (RAG) is becoming the backbone of modern IDP. RAG combines information retrieval with generative large language models. Instead of relying only on what a model learned during training, RAG retrieves relevant content from enterprise knowledge bases, vector databases, or document repositories and uses that content to ground the model’s response. In IDP, RAG shifts the focus from extraction to comprehension. A user can ask, “What is the termination clause in this contract?” or “Which invoices are overdue by more than sixty days?” The system retrieves the most relevant document sections and generates a cited, context aware answer instead of a raw data dump. RAG delivers several concrete benefits for document workflows: Reduced hallucinations, because answers are grounded in the source documents rather than model memory alone. Traceability, since citations back to the original passage support audit and compliance review. Conversational access, letting users query documents in natural language instead of searching folder by folder. Better exception handling, as agents can retrieve relevant policies, past cases, and business rules before acting. Scalable knowledge access, connecting IDP to contracts, claims, emails, and reports without retraining the underlying model. By 2027, three RAG variants are likely to dominate IDP deployments. Agentic RAG lets AI agents decide when to retrieve information and how to act on it. GraphRAG combines knowledge graphs with vector search to support multi hop reasoning across related documents. Multimodal RAG retrieves and reasons over text, tables, images, stamps, signatures,
Best Free AI Models for Document Processing in 2026
Artificial Intelligence

Best Free AI Models for Document Processing in 2026: Ranked

Back to Blog Table of contents On this page Best Free AI Models for Document Processing in 2026: Ranked Home › Blog › Artificial Intelligence › Best Free AI Models for Document Processing in 2026: Ranked Categories AI Tags Data Extraction OCR Algodocs By Shubhankar Biswas Published September 21, 2026, 10:15 The AI revolution has changed lots of things for us today, and data extraction is one of them. Previously, processing data from PDFs, images, and handwritten notes was difficult due to technological challenges. You needed to learn enterprise-level technologies to extract data from even a simple PDF document. But with the arrival of AI, things have changed drastically. AI models have seen significant improvements in their document processing accuracy and OCR capabilities. Recent research has also explored how modern vision-language models can improve document understanding and information extraction from complex documents. Research on AI-based document processing highlights the rapid development of these capabilities and the growing role of AI in understanding and extracting information from documents. Many platforms now publish AI and OCR leaderboards featuring their own accuracy benchmarks to track which models are leading the document processing and OCR race. What previously used to be a long and complex task can now be done by simply uploading a file and writing a few lines of a prompt. This might be easy for some people. But when it comes to processing a large amount of complex layout documents, where does AI stand? That is something we need to understand. In this blog, we will discuss the best free AI models for document processing that anyone can use in 2026. We will also look at the pros and cons of commercially available AI models for document processing and how to use these AI models for document processing. But first, we need to understand what AI document processing is. TL;DR AI has made document processing much easier than it used to be. Today, you can upload PDFs, images, handwritten notes, and other documents to AI models and extract data using a simple prompt. We tested several commercially available AI models using a handwritten invoice to see how well they could extract data from documents. The main findings are: ChatGPT: Easy to use and offers good data extraction accuracy. Gemini: Provides good extraction accuracy but may struggle with complex layouts. Claude: Can extract data accurately and keep it in a structured format, but may still miss some information. Grok: Can process PDFs, images, and handwritten notes but can struggle with complex layouts. DeepSeek: Offers good accuracy for PDFs, images, and handwritten notes and is free to use. Meta AI: Easy to use and free, but its extraction accuracy is less consistent. Mistral: Performs well with complex document layouts and has its own OCR capabilities. For personal use, free AI models can be useful when you only need to process one or two documents. However, processing a large volume of documents requires better control, customization, and accuracy. What is AI Document Processing? AI document processing means using AI/ML-based tools to process unstructured data from PDFs, images, handwritten notes, and other document types and convert it into structured data. These AI models use machine learning and deep learning algorithms to understand the context of a document, capture the required information, and extract the data. Users can use commercially available AI platforms such as ChatGPT, Gemini, or Claude to upload a document, write a prompt, and extract data from it. But there are other document processing tools such as Algodocs, Nanonets, and Docsumo that also offer AI capabilities similar to commercial AI models for document processing. However, these AI data extraction tools go beyond basic data processing and can be used for complex data extraction and analysis tasks. Best Free AI Models for Document Processing in 2026 The current market is inundated with AI platforms that you can use to process data from various types of documents. You have commercial AI/ML tools, and then there are open-source data processing tools as well. Some tools run on browsers or desktops, while some can be run locally on your own servers. We have tried 6 commercially available AI models to extract data from documents. We used the free version of each tool with simple prompt instructions such as “extract data from this document” to see how accurately these tools can process data from a document. For this experiment, we used a handwritten invoice to see how well each AI model could process and extract the data. So, here are the best free AI models you can use for document processing in 2026. ChatGPT by OpenAI We all know what ChatGPT is and what it can do. But ChatGPT is also a great AI model for document processing. It is easy to use, and its accuracy is great. To extract data from a document with ChatGPT, all you need to do is upload the file and write your prompt. Once you hit enter, ChatGPT will start extracting the data. You can then copy the extracted data into a file such as a .doc or .excel file and save it. Pros. The biggest pro of ChatGPT is that it is easy to use and the data extraction accuracy is very good. You can tell it which field you want to extract, and it will capture and extract the required information. Cons. You need a monthly Pro plan subscription to use better models. Price: $20 USD Per month. Free Plan: Yes Available Gemini Google’s flagship AI model is a great AI tool for data extraction. One of the reasons to try Gemini for document processing is because Google has developed its own OCR model, which uses AI to extract data from documents. Gemini uses Google’s OCR engine for data extraction alongside AI. You can extract data from a document simply by uploading the file and writing your prompt. Once you hit enter, it will start extracting the data. You can copy the data into a file such as a

Data Parser : Everything You Need To Know
Data Extraction

Data Parser Explained: How It Works & Why Your Business Needs One

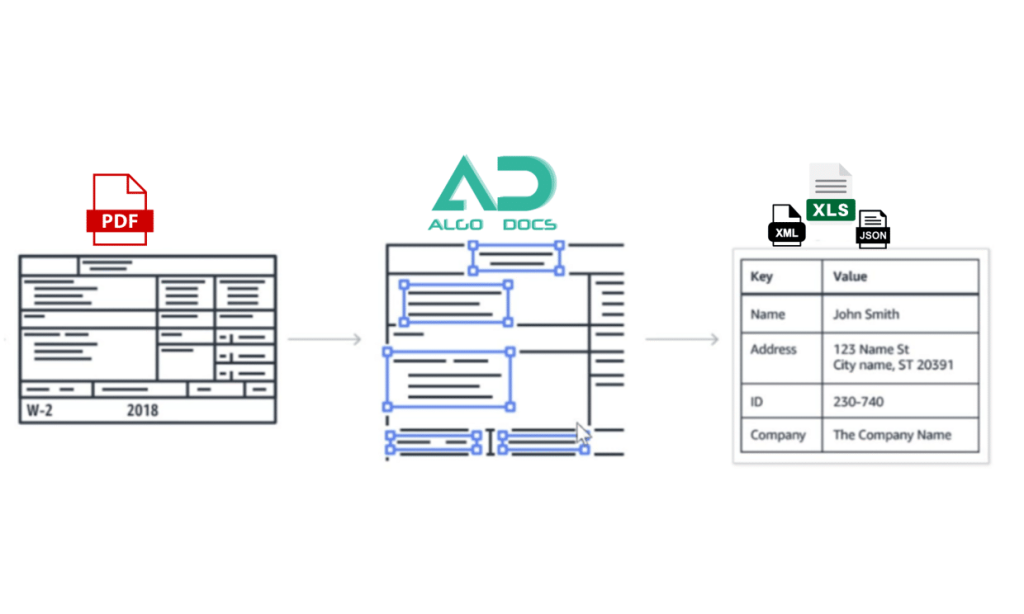
Back to Blog Table of contents On this page Data Parser Explained: How It Works & Why Your Business Needs One Home › Blog › Data Extraction › Data Parser Explained: How It Works & Why Your Business Needs One Categories Data Extraction Tags AI Data Extraction OCR Algodocs By Shubhankar Biswas Published September 17, 2026, 09:35 Most companies don’t have a data problem. They have a document problem. Invoices, purchase orders, bills of lading, and warehouse receipts still arrive as PDFs, scanned images, and occasionally handwritten paper. None of that is directly usable by an ERP, a WMS, or a BI dashboard. Someone has to read each document and retype the numbers, and every time a human retypes a number, there’s a real chance it comes out wrong. Published benchmarks put manual data entry error rates at roughly 1% to 5% of fields under normal conditions, and seminal by Professor Raymond Panko on human cognitive error in spreadsheets and documents has demonstrated that cell and field error probabilities routinely climb to 18–40% under time pressure, lack of validation, or with messy source material. A data parser is the software that removes that step. It reads a raw document, identifies the fields that matter, and outputs clean, structured data your systems can use immediately, with no retyping required. This guide explains what a data parser actually does, how it’s different from OCR and data extraction, the main parsing methods in use today, and how the technology plays out in a specific high-friction workflow: warehouse receipt data extraction. Real benchmarks and sources are cited throughout so you can verify the numbers yourself. TL;DR Summary Core Function: A data parser converts unstructured or semi-structured content (PDFs, scans, emails, web pages) into structured formats like JSON, CSV, or XML. Separation of Concerns: Parsing is distinct from OCR (which makes text machine-readable) and extraction (which pulls specific values). Most modern platforms combine all three. Human Error Risk: Manual data entry error rates typically run 1–5% of fields and can spike to 18–40% on complex documents, according to Panko’s human error research. Accuracy Leap: Modern AI-based parsers report 99–99.9% accuracy on structured fields in production, compared with roughly 80–85% real-world accuracy for legacy rule-based OCR. Cost & Time Savings: Automating extraction cuts per-document processing cost from an estimated $5–$25 down to roughly $2.88–$4 (a 60–80% reduction) and cuts processing time by 60–70%. Market Expansion: The intelligent document processing (IDP) market is growing fast: estimates benchmark the sector at ~$2.30 billion in 2024 according to Grand View Research and Precedence Research, climbing to over $10–$13 billion per Fortune Business Insights, with forecasts projecting a 25–34% CAGR through the early 2030s. High-ROI Use Case: Warehouse receipt data extraction removes manual re-keying from inventory reconciliation and prevents downstream shipping and ledger discrepancies. What Is a Data Parser? A data parser is a software or data parsing tool that extracts raw, unstructured data from websites, documents, multimedia, databases, and other sources. There is a difference between data extraction and data parsing. People often get confused between a data parser and a data extraction tool, but both are completely different. A data parser is specifically designed to extract data from various sources, particularly webpages, databases, and other sources such as website code, PDFs, images, videos, libraries, and other data sources. However, it does not convert this unstructured data into a structured data format. For example, a data parser can be used to extract data from an ecommerce website. Users can define the fields and rows, such as product prices, product descriptions, metadata, and other details, from the website and save the extracted data for later use in their work tasks. How Does a Data Parser Work? Most data parsers (rule-based, machine-learning-based, or hybrid) follow a similar four-stage pipeline: Step 1: Input and Document Classification The parser ingests a file: a PDF, scanned image, email, or web page. It typically classifies the document type first (invoice, bill of lading, warehouse receipt) because different document types need different extraction logic. Modern systems use trained classifiers for this step rather than relying on the user to tag every file manually. Step 2: Preprocessing Raw input is rarely clean. Scanned documents may be skewed, low-resolution, or faded; HTML pages are cluttered with navigation and ads. For scanned or photographed documents, optical character recognition (OCR) converts the image into machine-readable text at this stage. Preprocessing quality has an outsized effect on final accuracy: a blurry or skewed scan degrades every step that follows. Step 3: Parsing and Field Extraction This is where the actual interpretation happens, using one of three approaches: rule-based, machine-learning-based, or hybrid. The output of this step is a set of identified fields (supplier name, invoice number, line-item quantities) mapped to their values. Step 4: Structuring and Output The extracted fields are formatted into a structured output (JSON, CSV, XML, or a direct database write) and delivered to the target system, whether that’s an ERP, WMS, CRM, or analytics platform. A process that would take a person several minutes per document typically completes in seconds. Data Parsing vs. Data Extraction vs. OCR These three terms get used interchangeably, but they describe different jobs in the same pipeline. Term What It Does Analogy OCR Converts an image of text into machine-readable characters Turning a photograph of a page into typed text Data Extraction Locates and pulls out specific values from that text (a date, a total, a name) Underlining the important numbers on the page Data Parsing Interprets the structure of extracted content and organizes it into usable fields Filing those underlined numbers into the correct labeled boxes on a form In short: OCR makes text readable, extraction finds the data, and parsing gives that data structure. A complete intelligent document processing (IDP) system uses all three together, and most commercial platforms now bundle them into a single workflow. Types of Data Parsing Not every document needs the same parsing approach. The right method depends on how consistent your documents are. Rule-Based

intelligent document processing

IDP Use Case: Transforming Restoration Practices

Earthquakes, hurricanes, mudslides, electrical fires, and burst pipes are some of the natural incidences that are usually unforeseen. Buildings that are often at the receiving end during catastrophic calamities require immense repair work. Any comprehensive structure will, in this respect, indeed call for disaster recovery management, especially if it is a house or a company. It has scaled tremendously to be vital software in the construction industry, but it is notably critical in the catastrophe repair industry, where most companies are small. Table of Contents: But as structures progress, many organizations like yours struggle to cope with change. Often, the driving force of success is in the technology that forms the basis of these organizations. Let us think of the building and restoration industry and see what we come up with. These companies have to estimate all possible costs for a building construction project, including additional costs such as salary for office employees, wear and tear of equipment, office rent and other overhead expenses, and cost of all the materials used and wages to workers. Enhancing Data Management in Restoration Processes Intelligent Document Processing (IDP) tools can capture information from any format that has not been pre-formatted, including images and handwritten writings. This can be of great importance, especially in restoration processes where data could be in large quantities, in the form of field notes and sketches, among other things. The Importance of Accurate Costs and Expenses Some of the factors one needs to understand well to accurately estimate the cost of the project include the building material costs, the requirements, the procedures, and the codes that are to be followed, as well as the need to understand the market trends in terms of pricing. Such information may be found by analyzing a bid package and working through the contingencies and profit inherent in a bid or a given project. Two Significant Challenges: Documentation obstacles: One of the challenges associated with restoration events is collecting all the relevant and non-concocted paperwork. Some of the effects of this cumbersome procedure include the failure to complete some forms or the delay in completing them. Accounts Receivable Delays are attributed primarily to fourteen struggles stemming from a high turnover rate in accounting: payment cycles take longer. This not only impacts cash flow but also definitely causes a lot of headaches for the business’s dealings with its customers. The Impact of Intelligent Document Processing (IDP) Software on Restoration Businesses: Implementing Intelligent Document Processing (IDP) Several Challenges. Here are some of the key ones: Case Study Use case for restoration: The repair company wishes to provide the customer with an overview of line-item estimates for the job. Cost estimates should not be utilized as a list of negotiable items. Supplemental costs may apply if more damage or repair that has not been found or is hidden below present finishes is required. This also enables the client to correct himself or herself if they chose compositions that are not within the estimate or if they need extra work. This is because, in the course of the project implementation, changes will be made to adjust for the revised estimate and present it to the client. Any changes made to these documents will be recorded in a change order and presented to the customer for revision. System: It is a form of advanced digital document processing with natural language processing, multimedia processes, and feature extraction. Primary actor: Accountant/bookkeeper/Customer Scenario: To meet the customer’s request to extract the estimated line-item information from the final amount, the following processes should be considered: They ask for the extracted data to be formatted differently than the original document’s formatting. They clearly explain what should be ignored and what needs to be extracted. There are a total of 11 headers in the PDF; each row value contains three different pieces of information: one is the labor, the second is the material, and the third is the equipment information. They need to extract the labor and material information. For example, the following are the instructions for the needed to be extracted data and how it should look like output: Tabular output with headers and the order they should be in JSON form: ·”ITEM#”, mapped from the label in Yellow (as in the picture above) ·”ROOM”, mapped from the label in dark green (as in the picture above) ·”UNIT”, mapped from the label in Red (as in the picture above) ·”QTY”, mapped from the label in light blue (as in the picture above) ·”UNIT PRICE”, mapped from the label in light green (as in the picture above) ·”TOTAL” mapped from the label in pink/magenta (as in the picture above) However, we still need to extract and differentiate data for Labor and Material information. While mapping the extracted data to the new headers, as requested by the customer. As complicated as it looks and sounds, Algodocs can do exactly this request easily.  How to Use Algodocs to Extract We only need a sample file uploaded to Algodocs to create the extractor. There are many ways to upload a sample document. The user can automate importing files to Algodocs uploading from their device, business email, Gmail, or other cloud storage. Once the documents are uploaded, the system will extract data from your documents using Algodocs’ advanced AI engine without relying on templates or even labeling and training your files.  The results are the actual contents extracted from the sample document according to the rules you specify. We have Rule-based extraction and artificial intelligence mining, which can be integrated to synthesize both extraction methods. This can help you further improve your extracted data by putting it into the correct form and structure.  The system makes it easy to control extracted data from your documents and handle business exceptions. It allows you to export the extracted data directly to an Excel Spreadsheet or, with the integration of Zapier, automate exporting extracted data directly to your email, Google Sheets, or other cloud storage. Example of Output in Excel Key Takeaways This should explain how Algodocs has boosted the restoration business and its experience with the solution to prove that technology can transform any business. Let your team be an example of how adopting effective and progressive concepts can

bill of lading

How Algodocs enhances bill of lading processing

Back to Blog Table of contents On this page How Algodocs enhances bill of lading processing Home › Blog › bill of lading › How Algodocs enhances bill of lading processing Categories bill of lading Tags ai platform for data extraction algodocs Bill of Lading data extraction from images ocr api web-based ai platform for data extraction By Shubhankar Biswas Published October 13, 2025, 12:24 Updated July 23, 2026, 07:35 A bill of lading, shortened as BL or BoL, is a legal document given by a carrier (a company that provides transportation) to the shipper. It outlines the particulars of the goods being transported, including the kind, quantity, and destination of the goods. In addition, a bill of lading functions as a shipping receipt when the carrier finalizes the delivery of the goods after a given destination. This document must accompany the shipped products, no matter the form of transportation, and must be signed by an authorized representative from the carrier, shipper, and receiver. What Is the Purpose of a Bill of Lading? A bill of lading has three primary purposes. First, it is a document of title to the goods described in the bill of lading. Second, it is a receipt for the shipped products. Finally, it represents the agreed terms and conditions for the transportation and eventual release of the shipped goods. What Is in A Bill of Lading? Typically, a bill of lading will include the names and addresses of the shipper (consignor) and the receiver (consignee), shipment date, quantity, exact weight, value, and freight classification. Also included is a complete description of the items, including whether they are classified as hazardous, the type of packaging used, any specific instructions for the carrier, and any special-order tracking numbers. Why Is a Bill of Lading Important? A bill of lading is a legally binding document. The carrier and the shipper are given all the essential details to help them process a shipment correctly. Hence, it can be used in litigation if the situation requires it. The parties to it will be highly knowledgeable about the document as required by the law to ensure that there is no compromise in the safety and security of your goods. A bill of lading is undisputed proof of shipment. Furthermore, it allows for segregating duties, a vital part of a firm’s internal control structure, to prevent theft. Different Types of Bills of Lading Some of the most common include: Inland bill of lading Ocean bill of lading Through bill of lading Negotiable bill of lading Uniform bill of lading Challenges With Manual Processing Some of the known challenges are: Logistics companies are confronted with vast volumes of data through files in document form, such as invoices, airline bills, price lists, HR forms and payrolls, customs forms, and so on. Manual data management is time-consuming and error-prone. Human data entry errors can lead to costly consequences. Implementing Intelligent Document Processing (IDP) Much of the information needed to execute logistics and supply chain operations is manually extracted from data sources such as the Bill of Lading. Automating the processing of instructions for the Bill of Lading proves to be crucial in increasing back-office productivity and, consequently, improving customer service performance. If traditionally conducting these activities by manually copying and pasting data carries the risk of errors and is an obstacle to maximizing operational efficiency, the value of automation must be highlighted. Benefits Of Intelligent Document Processing (IDP) Accuracy: AI-driven IDP has the advantage of minimizing human factors and error occurrence, which in return produces more quality. Continuous Learning: AI models can learn from humans, thus enabling them to get better results even without human assistance. Cost Savings: Laboratory test costs decrease when data is not appropriately edited, prevented by IDP. Data Extraction: IDP excels in extracting names, dates, addresses, and amounts from BoLs. Quality Assurance: Human interaction ensures precision modeling. Guaranteed Quality: The IDP introduced AI computing and on-demand data collection to achieve valid results. CASE STUDY Imagine XYZ company, which is a logistics firm. It receives the shipment. The manager determines the type and amount of goods that need to be ordered. They then fill out a purchase order (PO), and XYZ’s owner reviews and initials each PO before it is emailed to the vendor. The vendor gathers the orders and signs a bill of lading along with a representative from the overnight carrier. The forwarder then supplies products to the ship and provides the invoice to the manager, who compares the bill of lading details with what was mentioned on the PO. If the information matches, the PO and the bill of lading are sent to the owner, who reviews the documents and writes a check payable to the vendor. Fields That Can Be Extracted: OT PRO Number Consignee City Consignee State Consignee Zip Total Weight Handling Unit Description The list goes on and on. Example of extract data output: Enhancing Accuracy with Automated Data Extraction Algodocs can extract data automatically from the Bills of Lading. This step dramatically improves efficiency and offers new prospects for success in logistics. Applying Algodocs to the Bill of Lading allows the necessary data to be automatically extracted from the PDFs and images of the handwritten document received from the carrier and a new document structure from the Bill of Lading to be created quickly, eliminating the need for repetitive and error-prone manual work. Improving Efficiency with Algodocs AI Algorithms Bill of Lading instructions are often accompanied by various documents in different formats, as each company chooses the format best suited to its needs when sending instructions to the carrier. Algodocs represents a breakthrough in managing Bill of Lading data extraction because Algodocs AI algorithms process text recognition; this process not only speeds up processing but also minimizes the possibility of errors. KEY TAKEAWAYS Algodocs is a potent system that combines OCR, NLP, and ML technologies to provide a tool capable of extracting data from heterogeneous documents. It is particularly useful in creating a Bill of Lading. With Algodocs, you can automatically extract any field

Algodocs, Data Extraction, Image Data Extraction

How to Extract Handwritten Data from PDFs with Algodocs?

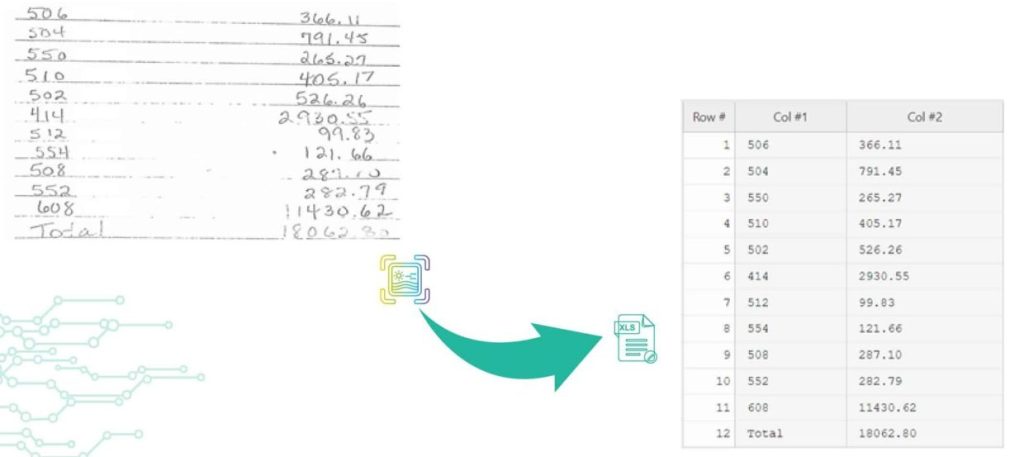
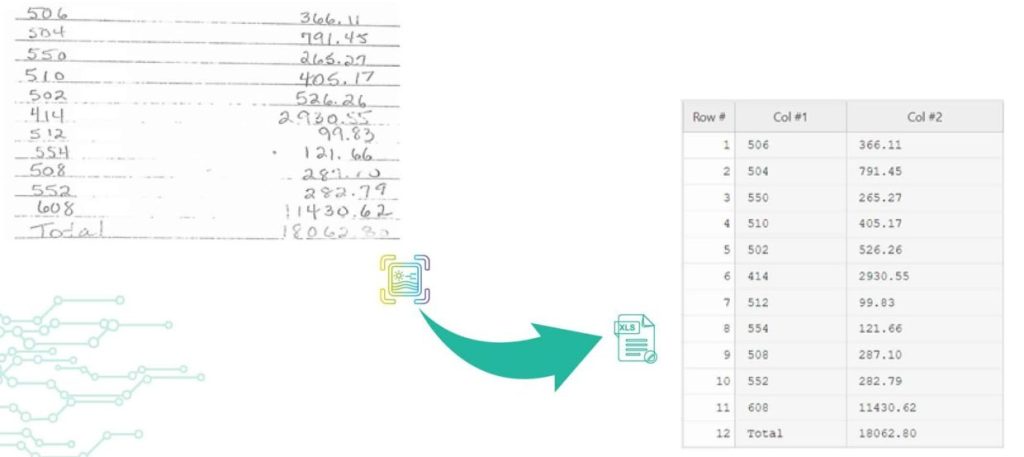
Back to Blog Table of contents On this page How to Extract Handwritten Data from PDFs with Algodocs? Home › Blog › Algodocs › How to Extract Handwritten Data from PDFs with Algodocs? Categories Algodocs Data Extraction Image Data Extraction Tags ai platform for data extraction algodocs character recognition data extraction from images handwritten pdf How to Extract Handwritten Data from PDFs web-based ai platform for data extraction By Shubhankar Biswas Published October 13, 2025, 12:19 Updated July 23, 2026, 07:36 Want to learn how to extract handwritten data from PDFs easily for your business documents? Algodocs is a powerful AI platform developed based on the latest technologies to streamline your processes and free your team from annoying and error-prone manual data entry by offering fast, secure, and accurate document data extraction. It helps you get rid of your workforce from repetitive, time-consuming, and error-prone manual data entry tasks such as extracting handwritten data. With its AI capabilities, Algodocs gives one of, if not the best, user experiences and interfaces. Areas and applications of Algodocs include extracting handwriting, tables, key-value pairs, marks, and signatures from PDFs and image files. Algodocs offers a forever free subscription, with 50 pages processed every month. What is OCR? Optical Character Recognition (OCR) engines are primarily focused on machine-printed text and may produce low accuracy for handwritten text. Intelligent Character Recognition (ICR) is an advanced recognition system that is used to recognize handwritten text. This allows the automatic conversion of text in an image into letter codes that are usable within computer and text-processing applications. Although many processes involve computer-based operations and are implemented in a digital environment, paper is still widely used across most core business processes such as mortgage origination, order fulfillment, contracts, and other documents that usually require handwritten input and signatures. Nowadays, the digitalization of paper documents plays an important role, and deciding on the right data capture software is critical since handwriting recognition, unlike printed text recognition is a more complex task that usually involves advanced deep learning algorithms. How Does Algodocs Do It? Handwritten data extraction from PDFs is implemented by converting handwritten text into machine-printed text with high accuracy. With the Intelligent Character Recognition (ICR) of Algodocs, you can automate your document processing workflow and get rid of manual data entry. Scan your paper documents with handwritten text and let Algodocs automatically extract data and convert it to Excel or JSON. Let’s consider the following portion of a scanned document, which contains a table of five columns filled with handwritten numbers. If you upload this image to your account at Algodocs, you will see the following output, which has 100% accuracy. Algodocs uses advanced ICR engines trained with Artificial Intelligence algorithms and Deep Learning. Extracting data from various document formats could be a challenging task, especially when it comes to the necessity to extract specific data sets from files containing different types of documents that span across multiple pages. In these quick materials, we will list key features that are available in Algodocs, and which will help you to extract data from your documents using the Algodocs advanced AI engine without relying on templates or even labeling and training your files. What Are the Supported File Formats for Data Extraction? You may upload to Algodocs different types of files of different Image formats for data recognition and data extraction: Portable Document Format (PDF) Joint Photographic Experts Group (JPEG) Portable Graphics Format (PNG) Tagged Image File Format (TIFF) What Are the Supported Languages for Data Recognition? Algodocs supports data extraction from documents with Arabic, Armenian, Belorussian, Bulgarian, Catalan, Chinese, Croatian, Czech, Danish, Dutch, English, Estonian, Filipino, Finnish, French, German, Greek, Hebrew, Hindi, Icelandic, Indonesian, Italian, Japanese, Korean, Lao, Latvian, Lithuanian, Macedonian, Nepali, Norwegian, Persian, Polish, Portuguese, Russian, Serbian, Slovak, Slovenian, Spanish, Swedish, Telugu, Thai, Turkish, Ukrainian, Vietnamese, and many other up to 200 languages. How to Extract Handwritten Data from PDFs Using Algodocs Step 1: Log in to your Algodocs account and go to the home page which is the Dashboard. Step 2: Click on the Extractors tab, where you can see the Create button on the top right side, click on it. Step 3: Choose the Custom Extractor, for getting structured data from your documents as you need it. Step 4: A pop-up window will appear, upload your sample file to extract data from. Click on the Choose file, to locate the document from your device storage folder, then assign a name to the extractor. Once done, click on the Create Extractor button. It will populate under Extractors as below; in this article, our example is called “Sample1.” Step 5: Click on the blue button labeled “Manage”, to create the data to be extracted. Step 6: Click on Add to choose what type of extraction method you want, here, you may use rule-based and AI extraction. In this example, we will choose the AI extraction method, “Form Data Extraction.” After clicking on “Form data extraction”, the page that you want to extract data from will appear on a new page. On the Top Right corner click on” Continue”. Step 7:  The raw data from your document is displayed. Now use available filters to select certain data, and update, or format the extracted data as you like. Once done, write the Field/Table name on the Left side inside the blank text box, and click the SAVE button on the right side. Step 8:  Now go to the extracted date and choose the extractor name, from the first drop-down menu. The extractor will populate the extracted date information. To view the extracted data, click on the Rows, and the data will populate as below.  Then choose to download the data as Excel, JSON, or XML Final Thoughts As we can see Algodocs performs well in handwritten text extraction from scanned documents. Feel free to start a free subscription right now and test your handwritten scanned documents. You can use Algodocs for free forever, and you will have 50 pages per month. If you need to process a higher number of pages, then please see our affordable pricing plans. Please contact

handwritten notes extraction

How to Convert Handwritten PDF to Text in 2026

Back to Blog Table of contents On this page How to Convert Handwritten PDF to Text in 2026 Home › Blog › handwritten notes extraction › How to Convert Handwritten PDF to Text in 2026 Categories handwritten notes extraction Tags ai powered tools algodocs convert handwritten to text data extraction digital transformation free online tools handwriting recognition handwritten pdf machine learning ocr technology pdf to text converter text recognition accuracy By Shubhankar Biswas Published October 13, 2025, 12:13 Updated July 23, 2026, 07:38 Digitization enables ease in handling documents to save, share, and access material. However, converting handwritten PDFs to text is still a big challenge. Old methods of digitization are not precise enough in the conversion of handwriting to editable and machine-printed text because they lead to errors and confusion. In the current era of advanced technology, many tools and techniques are very helpful to handle this challenge. The tools to convert handwritten PDFs to text use OCR technology and transform them into editable text within seconds. Such tools make it easier to organize and share your words in that document. To know how to convert scanned files with handwritten text, we will discuss free options that will simplify your conversion of handwritten PDFs. These tools also make digitization and data extraction more manageable. Challenges in Handwriting data extraction There are many challenges in handwriting data extraction due to several reasons. The process of handwriting data extraction includes digitization. It converts handwritten documents into that digital format. This step is easy and straightforward. The real and noteworthy challenges in handwriting data extraction arise when we have to turn these scanned images into editable text. Here we will see some valid challenges in the extraction of data from handwritten scanned images; 1. Irregularities in handwriting styles The primary challenge is the irregularities in handwriting styles. People generally write in many different ways. They use different angles, forms, and sizes of letters. These irregularities make text recognition a complicated process. In this case, machine learning algorithms are very useful to improve accuracy, but sometimes, they also struggle with chaotic or unreadable handwriting. 2.  Transcription The second most important challenge is transcription. It can also be problematic, especially when you are dealing with older documents where liquid ink is faded or scanned image paper has worsened. In these situations, the conversion of scanned PDF images into editable text can produce errors. These errors lead to inappropriate data extraction. 3.  Context The third important challenge is context. It plays a crucial role in precise data extraction. Sometimes, handwriting recognition systems misinterpret numbers or letters. They interpret wrongly, especially when there is high uncertainty or misplaced information. Addressing this challenge needs cutting-edge technology and advanced Machine Learning Algorithms. Such technologies ensure correct transcription and reliable Data extraction. What are the main methods or tools for Automated Handwriting data extraction? For automated handwriting data extraction, there are numerous primary techniques or tools available. However, a few noteworthy and useful ones are as follows: 1.    Optical Character Recognition The most common method for converting handwritten PDFs into editable text is Optical Character Recognition. It works by examining the scanned images of documents and identifying the shapes and patterns of individual characters. Optical Character Recognition tools can help in extracting text from native PDFs. However, its performance decreases when used for extracting handwritten. 2.    Intelligent Character Recognition The second most common method is Intelligent Character Recognition. It is considered for Handwriting recognition text. This Automated Handwriting data extraction method uses machine learning algorithms to understand several styles of handwriting. Intelligent Character Recognition is particularly convenient when you need to convert handwritten PDFs to text. The main reason behind this is that it can; Handle different handwriting styles Produce editable text with greater accuracy Intelligent Character Recognition is far more flexible than in print fonts. 3.    Free Online Tools Many free online tools can help you convert handwritten PDFs to text. These online tools often use both OCR and ICR technologies for the conversion of PDF to text. Some prominent and helpful tools are; Google Drive with Google Docs Microsoft OneNote OnlineOCR.net i2OCR Algodocs Users can upload their handwritten PDFs to these online services. These tools process the documents to extract text. The best part of these tools is that you can download the resulting editable text or copy it for further use. These free online tools offer a suitable way to convert handwritten PDFs to text. Algodocs, on the other hand, is an excellent choice if you’re searching for a more specialized tool that enables you to extract not just handwritten data but also any kind of data, including tables and structured data. Algodocs offers a forever free subscription, with 50 pages processed every month. Handwriting to Text: Easily Convert Handwriting to Text using Algodocs The best way to convert handwritten pdf to text is by using Algodocs. It is a convenient and amazing tool for converting handwriting to text online for free. It streamlines the process of digitization by providing an easy platform for usage. You can convert scanned handwritten documents and convert into editable text. Algodocs is equipped with advanced text recognition and machine learning algorithms. It guarantees high accuracy even with several handwriting styles. How to extract handwritten data using Algodocs Step 1: Log in to your Algodocs account and go to the home page, which is the Dashboard. Step 2: Click on the Extractors tab, where you can see the Create button on the top right side, and click on it. Step 3: Choose the custom extractor for getting structured data from your documents as you need it. Step 4: A pop-up window will come out, and this is where you upload your sample file to extract data from. Click on the Choose file to locate the document from your device storage folder, then assign a name to the extractor. Once done, click on the Create Extractor button. It will populate under Extractors as below; in this article, our example is called “Sample 1.” Step 5: Click on the blue button labeled “Manage”, to create the data to

Data Extraction, PDF

PDF Data Extraction: The Best Tool and Techniques

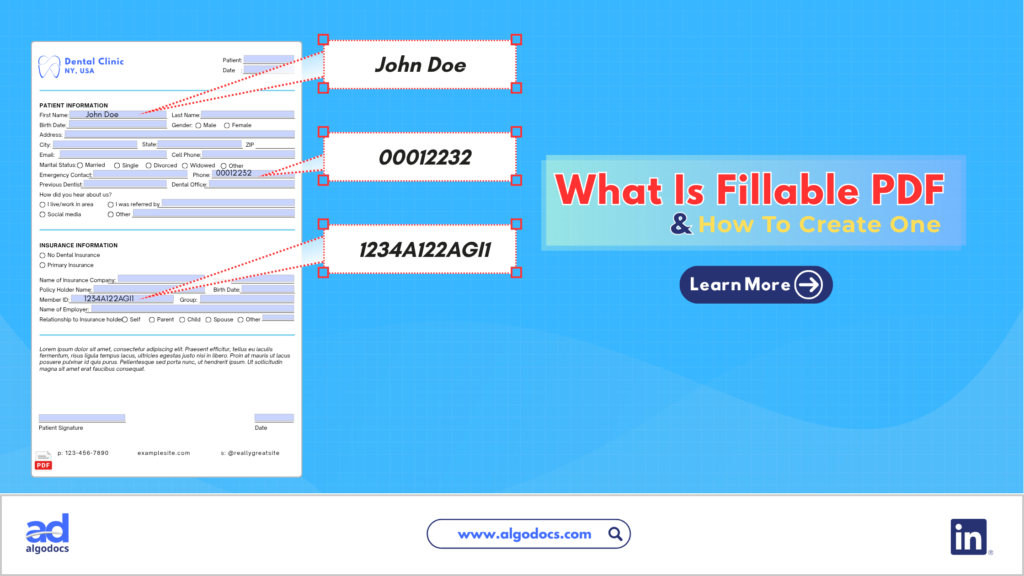
Back to Blog Table of contents On this page PDF Data Extraction: The Best Tool and Techniques Home › Blog › Data Extraction › PDF Data Extraction: The Best Tool and Techniques Categories Data Extraction PDF Tags ai powered tools algodocs convert handwritten to text data extraction digital transformation free online tools handwriting recognition handwritten pdf machine learning ocr technology pdf to text converter text recognition accuracy By Shubhankar Biswas Published October 13, 2025, 12:09 Updated July 21, 2026, 04:09 PDFs are ubiquitous in every organization, serving as the go-to format for sharing and exchanging business data. However, extracting, editing, or parsing data from these files can be a lot of work to do. In today’s data-driven world, efficiently extracting information from PDF documents is essential. This article talks about the problems with getting data from PDFs and shows how to extract data from PDFs to Excel online. Whether you need to get text, and tables, or make PDFs searchable, we’ll cover solutions that are fast, accurate, and easy to use. Challenges in PDF Data Extraction: Let’s explore some of the key challenges encountered in PDF data extraction, shedding light on why what may seem like a simple task can often become quite complex. Manual PDF text extraction requires meticulous attention to detail, making it a time-consuming endeavor. A slight error can lead to inefficiencies and potential errors. Human errors are common in manual extraction, potentially impacting the accuracy of the extracted data. Unlike other document formats like DOC, XLS, or CSV, editing PDF data is not straightforward, hindering customization according to specific requirements. Extracting data from tables in PDFs often results in the loss of original formatting, making it challenging to maintain data integrity. How to Extract Data from PDF Files in 2024: Extracting data from PDFs used to be a lot of work when the technology hadn’t advanced back in the days. However, now, with the advent of AI, OCR, and NLP, you don’t have to spend hours on manually extracting the data. All you need is an efficient tool like Algodocs that does the job for you accurately and easily. Let’s look at different PDF data extraction methods in 2024: Do it Manually While not the preferred method in 2024, manual data extraction remains a necessity for startups or beginners who are not ready to invest in good PDF data extraction software or are new to technology. Whether handling school documents, business reports, medical records, or any other file type, manual extraction is still widely utilized, although it is considered a less refined approach. Use Adobe Acrobat For more professional-grade PDF page extraction, Adobe Acrobat is a solid option. Although it’s not free, you can try it out with a 7-day free trial. Adobe Acrobat offers various plans, with Acrobat Pro starting at $19.99/month. This plan includes a range of features to streamline your document management process. Adobe Acrobat retains all interactive components of the PDF, including hyperlinks, comments, and forms. It allows you to extract any number of pages and save them as separate files or split the PDF into multiple PDFs, but all at a cost. You wouldn’t think it’s free, right? While Adobe Acrobat is a well-established tool for working with PDFs, it lacks the advanced data extraction capabilities of automated data extraction tools like Algodocs. Such a tool utilizes the latest technology to extract a wide range of information from PDFs and images, including handwriting, tables, and key-value pairs. This extracted data can then be exported into usable formats like CSV or Excel, making it ideal for integrating with accounting software or further analysis. In contrast, Adobe Acrobat offers limited data extraction functionalities. Automate Data Extraction with AI-powered OCR Technology What if you need to extract pages based on their content? Consider a scenario where you need to extract and analyze all invoices or pages containing specific key values such as names, dates, emails, total, address, etc. In such cases, an AI-powered OCR (Optical Character Recognition) tool can be invaluable. One important and powerful tool is Algodocs which we’re going to discuss in detail later in the article. It is the easiest way to get data from PDFs to Excel. Automated PDF Data Extraction: Algodocs Experience the power of Algodocs, an innovative AI data extraction platform designed to streamline your document processing workflow. With Algodocs, you can effortlessly extract valuable information from scanned files, including images, PDFs, Word, and Excel files. Whether these are HR forms, bank statements, purchase lists, or sales invoices, Algodocs handles them all with high accuracy. Gone are the days of manual data extraction. Algodocs empowers you to access and extract editable data effortlessly. Now get rid of the tedious tasks and say hello to editable formats like Excel, JSON, and XML, and seamless integrations with other software such as accounting or databases. Best of all, Algodocs offers a forever free subscription plan, allowing you to process up to 50 pages per month without any cost, so you can extract data from PDFs for free! Key Features of Algodocs PDF Extraction: Algodocs automates the extraction of tables from scanned files, including handwritten tables and those spanning multiple pages. The advanced AI-powered OCR engine can handle low-quality scanned PDFs and images at as low as 75 dpi. Using Intelligent Character Recognition (ICR) functions, Algodocs can extract handwritten text and convert it into machine-printed text. Algodocs can extract data, fields, and tables from native and scanned documents and save them as Excel, JSON, or XML files. Get Started in Minutes: The screencast video below shows how to quickly convert PDF files and photos into editable formats like Microsoft Word, Excel, PowerPoint, Text, or RTF. Moreover, a summary of the steps required for transforming a PDF into an editable Excel file is provided below. Convert PDF files and images into editable files in less than a minute. Step 1: Log in to your Algodocs account. Step 2: From the Dashboard, click on the File Manager tab  Step 3: Right-click on the root , and a drop-down menu will pop up showing available options

Data Extraction, PDF

What is a PDF Parser?

Back to Blog Table of contents On this page What is a PDF Parser? Home › Blog › Data Extraction › What is a PDF Parser? Categories Data Extraction PDF Tags ai platform for data extraction algodocs character recognition data extraction from images deep learning export extracted data to excel invoice process machine learning ocr api web-based ai platform for data extraction By Shubhankar Biswas Published October 13, 2025, 12:03 Updated July 29, 2026, 02:32 A PDF Parser is a program or a library that enables end-users and organizations to parse data from native PDF documents. Often, organizations need to parse PDF documents for specific fields such as Account Number, Date, Address, Bill to/from information, or parse tabular data. PDF Parsers are usually needed and used for processing and parsing data from large amounts of documents. On the other hand, when you have a handful of documents you simply go and copy the data you need from PDF documents manually and paste it to Excel or anywhere you need it to be. PDF Parsers enable end-users to get data from hundreds and thousands of PDF documents in real time by saving huge amounts of time and, thus, money. Parsing pdf documents isn’t an easy task. There are various ways native pdf documents are generated and parsing data from such pdf documents requires smart approaches. Parsed data from PDF documents greatly varies depending on the industry, which means the data parsed might also greatly change, which complicates the task. Parsing PDF medical forms, which contain specific fields such as First, Middle, and Last names, Sex, Date of Birth, etc. are very different from PDF purchase orders that contain mainly the items in the tabular form with such columns as Item No, Code, Quantity, Item Price, Amount, etc. Therefore, if PDF Parser produces just a bunch of text from a PDF document it does not make much sense for the end-user. What end-users or organizations require is the structured data parsed from PDF documents. In other words, PDF Parser should extract from PDF documents only the data the end-user needs and in the right structured format. For this, the PDF Parser must be smart and flexible enough to parse PDF documents with various layouts and data types. How to parse PDF documents with various layouts? Algodocs allows you to parse PDF documents of any complexity in their layouts and type of data. With the flexible extracting rules of Algodocs, you can parse data from PDFs with different layouts. It is very easy and quick to set up extractors in Algodocs for your PDF documents. We provide 100% free technical support and are ready to set up extractors for you. While we provide free support for creating extracting rules, you may check our help and support section if you wish to learn how to create extracting rules in Algodocs. Watch the following introductory video to get an idea of how it works in Algodocs. Feel free to start a free subscription right now and parse your pdf documents. You can use Algodocs free forever with 50 pages per month. If you need to process a higher number of pages, then please see our affordable pricing plans. If you have specific requirements and need a custom solution, please contact us. You Might Also Like PDF Data Extraction: The Best Tool and Techniques PDFs are ubiquitous in every organization, serving as the go-to format for sharing and exchanging business data. However, extracting, editing, or… Shubhankar Biswas October 13, 2025 PDF Image Extraction: A Comprehensive Guide To Extracting Image Data From Scanned Pdf Files In 2025 PDF image extraction is a challenging process. Without proper tools and technology, this process can be tedious and prone to errors, which can… Shubhankar Biswas September 1, 2025 Convert PDF to JSON – Convert PDF Documents to Structured JSON Objects Table of Contents Introduction Organizations in various industries widely use PDF documents, since no doubt PDF is a common document format for… Shubhankar Biswas October 13, 2025 Start extracting your data today No credit card required. Process up to 50 pages per month on the Forever Free plan. Book a Demo Get Started for Free

Scroll to Top