Algodocs

algodocs

PDF

Convert PDF to JSON – Convert PDF Documents to Structured JSON Objects

Back to Blog Table of contents On this page Convert PDF to JSON – Convert PDF Documents to Structured JSON Objects Home › Blog › PDF › Convert PDF to JSON – Convert PDF Documents to Structured JSON Objects Categories PDF Tags ai platform for data extraction algodocs character recognition data extraction from images deep learning export extracted data to excel invoice process machine learning ocr api web-based ai platform for data extraction By Shubhankar Biswas Published October 13, 2025, 11:59 Updated July 21, 2026, 05:15 Introduction Organizations in various industries widely use PDF documents, since no doubt PDF is a common document format for businesses to transfer data. Purchase orders, Invoices, Agreements, and many more document types are interchanged in PDF formats. On the other hand, JSON is another format that represents data in a structured format, which is widely used in transferring data between web applications. As a result, Working with JSON is much easier than with PDF. Therefore, in this article, we will talk about PDF and JSON formats and how you can convert your PDF documents to JSON format. What is a PDF? PDF (Portable Document Format) was initially developed by Adobe® Systems in 1992 and is standardized as ISO 32000. What makes PDF so popular is it is independent of the application software, hardware, and operating system. Other than text and images PDF files may contain a variety of content such as annotations, form fields, layers, etc. There are many advantages of PDF format such as multi-dimensionality, which we have already mentioned – being able to contain various types of content, text, images, videos, vector graphics, interactive fields, hyperlinks, and buttons. Moreover, PDF documents are easily created and viewed on different devices.  Security in PDF was one of the primary concerns of Adobe® Systems. Therefore, PDFs have different access levels to protect the content and the whole document, such as passwords, digital signatures, and watermarks. However, some of the downsides of a PDF are the complexity of editing and especially extracting data from it. Moreover, PDFs are not generated in the same way, so different PDF files can be created in various ways, which complicates the task of extracting data from PDF documents. What is a JSON? JSON (JavaScript Object Notation) is a very popular data format, which appeared in the early 2000s. JSON is a language-independent data format and is used to transfer data between software applications, particularly web applications, usually between server and client.  Most of the API integrations are realized using JSON format for data transfer since it is very easy to work with JSON. Consider a JSON object called person, which contains the following information:{   “name”: “John”,   “surname”: “Doe”,   “age”: 25} Accessing fields of a JSON object is as simple as using the name of the object and the field name you want to access by separating them with a dot as follows: To access a person’s name we use person.name, which will give us “John” as a result. Similarly, we do for surname and age fields: person.surname, person.age Note how easy it is to access any field of a JSON object, which is definitely not compared to accessing specific information in the PDF document. How does JSON differ from PDF? Although PDF and JSON are both widely spread and used, there is a huge difference between PDF and JSON. The difference between them is simply in the purpose of their usage. PDF is mainly used for exchanging information between humans, since it contains text, graphics, illustrations such as images and videos, etc. On the other hand, JSON is mainly used between computer programs and different applications for communicating and exchanging data between each other. It is not an easy task for a human to read information from a JSON file, especially if it is a compressed one, but it is a perfect way to access information from JSON for a software application. The opposite goes for the PDF. Therefore, PDF and JSON become important, useful, and helpful only when they are used in the right place and for the right purpose. How to Convert PDF to JSON? Often, organizations need to transfer data to other programs for further processing. This data is often stored in PDF documents since businesses often speak to each other in a “PDF language”. However, extracting information from PDF documents can be challenging.  The simplest solution is that you can always copy and paste text from a PDF and send it to where it belongs. However, this simple approach has many problems, since first of all this will work only with native PDF files (not scans) for which you can even use some free PDF Parsers. Another problem even if your PDF documents are all native, it is not easy to copy the entire table from a PDF by maintaining its format, especially if the table spans over multiple pages, for example, 100 or 1000 pages. Additionally, often organizations need to extract specific data from PDFs, for example not the entire table, but instead specific rows or columns based on some conditions. Last, but not least, it is not worth spending your valuable time on menial data entry! Convert PDF documents to JSON with Algodocs Algodocs offers a perfect solution to extract any type of data from PDF documents and transfer it to other programs in real-time. Algodocs can extract fields and tables of any complexity from native as well as scanned PDF documents. You can convert your PDF documents to JSON in three steps with Algodocs. First, start by creating an extractor in Algodocs. Algodocs has some preprocessing operations that take some time depending on the number of pages your PDF document contains; usually, it is around 15-20 seconds. Then, go to the ‘Extracting Rules’ editor to create your extracting rules for every field you need to extract from your PDF documents. Similarly, if you need to extract tables from your PDF documents you can create extracting rules for tables by selecting ‘Table’ as the data type. After you are done with creating and extracting rules,

Algodocs

Extract handwritten text from scanned PDFs and images

Back to Blog Table of contents On this page Extract handwritten text from scanned PDFs and images Home › Blog › Algodocs › Extract handwritten text from scanned PDFs and images Categories Algodocs Tags ai platform for data extraction algodocs character recognition data extraction from images deep learning export extracted data to excel invoice process machine learning ocr api web-based ai platform for data extraction By Shubhankar Biswas Published October 13, 2025, 11:56 Updated November 10, 2025, 13:34 Optical Character Recognition (OCR) engines are primarily focused on machine-printed text and may produce low accuracy for handwritten text. Intelligent Character Recognition (ICR) is an advanced recognition system that is used to recognize handwritten text. This allows the automatic conversion of text in an image into letter codes that are usable within computer and text-processing applications. Although many processes involve computer-based operations and are implemented in a digital environment, paper is still vastly used across most core business processes such as mortgage origination, order fulfillment, contracts, and other documents that usually require handwritten input and signatures. Nowadays, the digitalization of paper documents plays an important role, and deciding on the right data capture software is critical since handwriting recognition unlike printed text recognition is a more complex task that usually involves advanced deep learning algorithms. Algodocs: Deep Learning Handwriting Recognizer Algodocs is capable of converting handwritten text into machine-printed text with high accuracy. With the ICR of Algodocs, you can automate your document processing workflow and get rid of manual data entry. Scan your paper documents with handwritten text and let Algodocs automatically extract data and convert it to Excel or JSON. Let’s consider the following portion of a scanned document, which contains a table of two columns filled with handwritten numbers. If you upload this image to your account at Algodocs, you will see the following output, which has 100% accuracy. Algodocs uses advanced ICR engines trained with Artificial Intelligence algorithms and Deep Learning. The above example includes mostly digits. Another example with characters is given below. The following is the extracted text by Algodocs from the above image. As we can see Algodocs performs well in handwritten text extraction from scanned documents. Feel free to start a free subscription right now and test your handwritten scanned documents. You can use Algodocs free forever with 50 pages per month. If you need to process a higher number of pages, then please see our affordable pricing plans. If you have specific requirements and need a custom solution, please contact us. You Might Also Like How to Extract Handwritten Data from PDFs with Algodocs? Table of Contents Want to learn how to extract handwritten data from PDFs easily for your business documents? Algodocs is a powerful AI platform… Shubhankar Biswas October 13, 2025 Conquer Multilingual Data Extraction: A Step-by-Step Guide with Algodocs Introduction Sick of spending hours manually extracting data from multilingual PDFs and images? It could be more efficient, prone to mistakes, and,… Shubhankar Biswas October 12, 2025 Why convert PDF to Word on MacBook (Mac)? Picture this: You have a PDF file that needs to be revised or a scanned document that you wish to convert into an editable format like an MS Word… Shubhankar Biswas October 12, 2025 Start extracting your data today No credit card required. Process up to 50 pages per month on the Forever Free plan. Book a Demo Get Started for Free

Image Data Extraction

A Guide on Extracting Tables From Low-Quality Scanned Documents

Back to Blog Table of contents On this page A Guide on Extracting Tables From Low-Quality Scanned Documents Home › Blog › Image Data Extraction › A Guide on Extracting Tables From Low-Quality Scanned Documents Categories Image Data Extraction Tags ai platform for data extraction algodocs character recognition data extraction from images deep learning export extracted data to excel invoice process machine learning ocr api web-based ai platform for data extraction By Shubhankar Biswas Published October 13, 2025, 11:52 Updated July 22, 2026, 09:54 Many companies deal with thousands of documents every month. Document workflow automation becomes vital for such companies as the number of documents increases. One of the most frequent and at the same time tedious operations when processing documents is reading data from tables, especially when documents are scanned PDFs or images. Automating table extraction from scanned documents and exporting them into Excel or JSON within seconds is a dream for every company dealing with manual data entry. Automating table data extraction from scanned documents and images reduces operational costs and saves a lot of time. In this article, we will talk about table extraction from scanned documents or images with low quality. You, most probably, came across some online tools that can extract tabular data from documents. However, there are a few that really work with low-quality scanned documents or images taken by a mobile device. Optical Character Recognition (OCR) is the technology used for converting scanned images into text. However, standard OCR tools require you to apply certain image processing operations on the images before you can apply OCR on them. Without manual pre-processing, OCR will fail in most cases, and accuracy will be low. Unfortunately, even with pre-processing operations free OCR tools produce poor performance. How to extract tables from scanned PDFs and images with low quality? Algodocs has an advanced AI-powered OCR engine that automatically handles any type of scanned PDF or image with a low quality. Algodocs accepts either colorful scanned images, black and white, or any other settings and extracts data with high accuracy. Algodocs can process scanned images with as low a dpi as 75. If you have scanned PDFs or images with low quality, then Algodocs is the right solution for you. You may start a free subscription right now and test your own scanned documents since we offer a free subscription (forever) with 50 pages per month. If you need to process a higher number of pages, then please see our affordable pricing plans. Please read our article on the basic steps for table extraction from documents here: Extract tables from PDF and scanned documents Algodocs: the best software tool to extract tables from scanned PDFs and images Consider the portions of the scanned documents below and the tables that Algodocs extracted from them. Example #1 Sample scanned image with low-quality (black and white) Extracted table by Algodocs. Example #2 Extracted table by Algodocs As you can see, the accuracy of Algodocs is perfect even with low-quality scans. However, there are cases when scanned images may cause Algodocs to make mistakes concerning small characters such as punctuation or other symbols (points, commas, date separators, etc.). Let’s have a look at the example below with a scanned image and see what Algodocs could extract from it. The extracted table from the above-scanned image is shown below. As you can see, there are numbers that are extracted with wrong decimal separators (indicated in red circles), i.e. a decimal point is mistakenly recognized as a comma. This is due to the dark background that some rows have on the image. With the help of flexible extracting rules of Algodocs, the workaround is quick and simple. Whenever you have low-quality scanned PDFs of images, we always advise you to follow the steps explained below. Step1. Remove all points and commas from the numbers We apply the ‘Search & Replace’ filter in Algodocs by using regular expressions as the search type. We apply this rule to all the columns in the example below, but you can restrict this rule to a specific column when needed. In order to find all dots or commas we use .|, as the search term and we leave empty the second field (replace by this), since we simply want to remove them. Step 2. Convert all numbers to their previous format Since we removed all points and commas from numbers, they actually increased, i.e. multiplied by 100 we can say (2,378.63 became 237863). Therefore, since we know that our numbers had 2 decimal places, we can divide all numbers by 100 to get the original numbers. The ‘Arithmetic Operation’ filter helps us implement exactly this. We divide numbers by 100 in the last column as shown in the example below. You may apply this filter to other columns too. That’s it. We got numbers in their original form with 100% accuracy! The same approach can be applied to other symbols when you have documents with a low quality. Please, contact us if you need any assistance. You Might Also Like How to Extract Handwritten Data from PDFs with Algodocs? Table of Contents Want to learn how to extract handwritten data from PDFs easily for your business documents? Algodocs is a powerful AI platform… Shubhankar Biswas October 13, 2025 Data Extraction for Legal Industry : How Intelligent Document Processing (IDP) Can Transform Legal Industry Document Workflow The global law and legal services industry is expected to reach $1,591.56 billion by the end of 2032, according to a report. The legal industry… Shubhankar Biswas October 12, 2025 Extract Tables from Images with AlgoDocs Extract Tables from Images with AlgoDocs One might find themselves overwhelmed by a deluge of paperwork—orders, checks, articles—all containing… Ibrahim Nalbant June 20, 2024 Start extracting your data today No credit card required. Process up to 50 pages per month on the Forever Free plan. Book a Demo Get Started for Free

PDF To Word
PDF

AI-Powered PDF to Word Conversion: A Complete Guide

Back to Blog Table of contents On this page AI-Powered PDF to Word Conversion: A Complete Guide Home › Blog › PDF › AI-Powered PDF to Word Conversion: A Complete Guide Categories PDF Tags AI PDF to Word converter online algodocs best free PDF to Word converter Convert PDF file to word free free pdf to word converter PDF to word online By Shubhankar Biswas Published October 12, 2025, 19:22 Updated July 10, 2026, 09:46 Introduction to AI Data Extraction and PDF to Word Conversion Imagine turning static PDF documents into flexible, modifiable Word documents in a few seconds. The purpose of AI data extraction is beyond conversion; it’s about releasing the true strengths of your data. What takes place when that data is fixed in such an uneditable file? AI data extraction and the conversion of PDFs to Word documents represent an innovative technology that is changing our document interactions. Whether you’re an individual who likes to organize your spending, such as bills and receipts, a student compiling research, or a business professional analyzing reports, the ability to extract valuable information from printed documents, images, and scans is paramount. Traditionally, the conversion of a PDF to a Word document and the data extraction has been cumbersome and often results in inaccuracy. When people used manual copy-pasting or converted using traditional tools, formatting, missing tables, and disordered texts were experienced. However, the advancement of artificial intelligence technology has changed this situation entirely. Current AI technology uses improved OCR and natural language processing (NLP) to read and recognize text accurately, tabular, handwritten content, images, and other forms of data from low-quality and badly formatted PDFs. With AI data extraction, you can effortlessly transform static PDFs into dynamic, editable formats like Word, Excel, JSON, and XML while preserving the original formatting and layout. This unlocks a world of possibilities, from seamless collaboration and editing to in-depth data analysis and automation. In this article, we’ll explore the top AI-powered PDF to Word converters, the key features to look for, and showcase how Algodocs is leading the way in intelligent data extraction. Top AI-powered PDF to Word Converters with Data Extraction Capabilities Today, there is a huge demand in the AI PDF to Word conversion market, and every player is attempting to become ‘the best AI PDF to Word converter.’ Look closely at the key players that excel at conversion and smart data extraction. 1)   Adobe Acrobat Pro DC: The leading software in the market, Adobe Acrobat, has very robust AI that can convert PDFs to Word with considerable precision. Its top-performing OCR features to ensure that PDF conversions occur smoothly. It also makes it easier to extract forms, which is ideal for people who desire structured data results. Still, it comes with a considerable financial expense that may prove a thorny issue for starters. 2)   Wondershare PDFelement: Like Adobe, PDFelement stands out for its fairly clear interface and powerful AI options. Its OCR accuracy is strong, and it presents respectable data extraction tools. While it is cheaper than Adobe, using certain features requires additional purchases. 3)   Nitro Pro: Another winner is Nitro Pro, which demonstrates outstanding OCR capabilities and a perfectly organized interface. It can also convert PDFs to Word and retain the layout and formatting. The data extraction capabilities it provides with the help of AI algorithms are pretty impressive; however, in this aspect, it is slightly less endowed, as is Adobe or even PDFelement in terms of the variety of options available. 4)   Smallpdf: If you need a free online AI PDF to Word converter, Smallpdf is highly recommended. It is simple to use, supports a range of file formats, and supplies basic OCR functions. Still, the free version features restrictions on file size and ways to use it, and data extraction capabilities are limited. 5)   OnlineOCR.net: This tool is another free online option made exclusively for OCR and data extraction. Though its interface is not the latest design, it surprisingly performs well extracting text from scanned PDF formats. However, it lacks some advanced features and may not be the best choice for converting complex PDFs. Nonetheless, the tools discussed above perform poorly when dealing with tables, handwritten documents, key-value pairs, complex layouts, or multilingual documents. Key Features when Selecting AI-Powered PDF to Word Converter Here are some relatively crucial features to guarantee efficient and effective data extraction while evaluating an AI-powered PDF to Word converter. Here’s a breakdown of what to prioritize: OCR Technology: This is a significant feature of any good PDF converter and is called Optical Character Recognition. Search for tools that incorporate advanced OCR features that can precisely detect text, regardless of document type, such as scanned PDFs or complex designs. The converted Word document’s quality and the accuracy of extracted data will depend directly on the OCR engine. Table Recognition: In PDFs, tables are a usual approach used to present the data. A proper converter should be also able to identify and perfectly convert tables to maintain and follow their structure and format in the resultant Word output. It is especially going to be important for those who must analyze or manipulate data. Key value pairs (Form Field) Extraction: If you collaborate on PDFs that contain forms, extracting form field data is important. Find a converter that can pick out and collect form fields and their corresponding values for a seamless import of this data into either spreadsheets or databases. Data Output Formats: Think about the mediums in which you will share your extracted information. Tools such as Algodocs are capable of working with frequent formats like CSV, Excel, XML, Word, etc. Nonetheless, if you specifically need certain file formats or integrations with other applications, it’s important to confirm that the converter supports those options. Ease of Use: A user-friendly interface can lift your productivity considerably. Search for a converter that features a clear and user-friendly interface that makes it easy to upload, extract, update, and export data from PDFs. Additional Features: A few converters

extract data from passport
Data Extraction

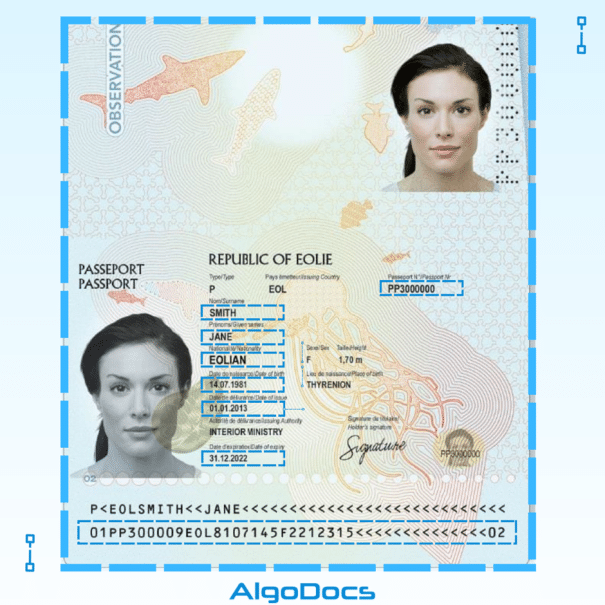
Extract Data from Passport: A Complete Guide on How to Extract Data with Algodocs Passport OCR

Back to Blog Table of contents On this page Extract Data from Passport: A Complete Guide on How to Extract Data with Algodocs Passport OCR Home › Blog › Data Extraction › Extract Data from Passport: A Complete Guide on How to Extract Data with Algodocs Passport OCR Categories Data Extraction Tags algodocs ocr api passport data extraction By Shubhankar Biswas Published October 12, 2025, 19:08 Updated July 20, 2026, 04:38 Extracting Data from Passports: How To Streamline Travel Document Processing With AI Introduction Passports are essential documents used worldwide for identification and travel purposes. They contain critical personal information such as the holder’s name, date of birth, nationality, and passport number. Extracting data from passport manually can be time-consuming and prone to human error, especially when handling large volumes of documents. Industries like travel, finance, and government services have to process huge numbers of travel and passport documents for various tasks. Fortunately, advancements in optical character recognition (OCR) technology and the invention of AI and ML models now allow for the seamless and accurate extraction of passport data. This blog delves into the various aspects of extracting data from passports, highlighting the benefits of passport OCR apps like Algodocs AI passport OCR and their applications across industries. What Is a Passport OCR App & How it Helps With Passport Data Extraction? A passport OCR app is a software application built to automate the extraction of data from passports. These apps rely on OCR and advanced AI or ML technologies to identify, read, and process printed text and MRZ codes. Key Features of Passport OCR Apps: Extract information from MRZ, VIZ, and embedded chips. Support for multiple languages and document formats. Integration capabilities with enterprise systems like CRMs, ERPs, or KYC software. Secure handling of sensitive data with encryption. For example, Algodocs, a leading passport OCR solution, allows businesses to quickly extract and organize passport data in formats such as Excel, JSON, or XML. How Passport OCR Works Passport OCR apps work in several steps to ensure accurate and efficient data extraction: Image Capture: The user uploads a scanned passport image or captures a photo using a smartphone or camera. Image Preprocessing: The software enhances the image by correcting skew, adjusting brightness and contrast, and removing unnecessary noise to improve text recognition. Text Recognition: The OCR engine identifies characters, numbers, and symbols in the MRZ and VIZ. Data Structuring: Extracted information is organized into fields (e.g., name, nationality, passport number) and exported in a user-friendly format. Validation: Advanced algorithms validate the extracted data for accuracy and completeness. Some advanced passport OCR apps also support language detection, integration with APIs, and real-time processing for large-scale operations. Methods of Data Extraction from Passport – Manual vs. OCR Manual Data Extraction In manual extraction, staff members physically review the passport and type the data into a system. While this method might seem straightforward, it is fraught with challenges: Time-Consuming: Processing even a few passports can take hours, especially in high-volume industries like immigration or banking. Error-Prone: Manual entry is susceptible to errors like typos, misinterpretation of characters, and oversight of critical details. Costly: Hiring and training employees for this task adds operational costs. Data Security Risks: Handling sensitive personal information manually increases the risk of data breaches. Automated Passport Data Extraction with OCR OCR technology automates data extraction by scanning the document, recognizing the text, and converting it into a digital format. OCR tools are designed to handle structured text, such as the MRZ, with high accuracy and speed. Key benefits include: Faster processing times. Reduced error rates. Ability to scale for large data volumes. Challenges with manually extracting data from passport documents Extracting data from scanned passport documents by hand can be very challenging. One big problem is that it takes a lot of time. Even if you are working on just one passport, manually copying the information is a slow process. But with OCR (Optical Character Recognition) and AI technology, this job can be done in just a few minutes. Another issue with manual data extraction is that it is not always accurate. People can easily make mistakes when typing out the details. In comparison, a passport OCR app can quickly and correctly extract data from many passports without any errors. Manual methods also need a lot of human effort, which makes it more expensive. Companies need to spend money on training staff and managing the work. On the other hand, OCR tools don’t need much human involvement. Once set up, the tool can handle multiple passports on its own, saving both time and money. Using OCR technology is faster, more accurate, and much more efficient than doing the job manually. It’s a simple solution to a complicated problem! Why Choose a Passport OCR App Like Algodocs Over Manual Data Extraction Manual data entry is becoming obsolete as businesses recognize the efficiency of automated solutions. Choosing a reliable passport OCR app like Algodocs offers numerous advantages: Benefits of Passport OCR Apps Efficiency:Passport OCR apps can process passport data within seconds, saving a lot of time. This helps businesses complete tasks faster and improve overall efficiency. Accuracy:OCR tools use advanced technology to ensure precise data extraction. Unlike manual methods, which often lead to errors and missing information, OCR apps extract all the data accurately and without losing any important details. Cost Savings:Automating data extraction with OCR reduces the need for hiring extra staff, lowering operational costs. An OCR app can handle multiple passports at once, while manual processes require more employees to manage the same amount of work. Scalability:OCR apps can process large numbers of documents quickly, making them perfect for industries like travel, banking, and any business that handles a lot of data. Manual methods struggle to scale, as they require more hiring, training, and management, which increases costs and adds complications. Data Security:Modern OCR apps come with encryption and secure storage features to protect sensitive information. This makes them safer than manual data extraction, which can be more prone to risks like data theft and misuse. Why Choose Algodocs? User-Friendly Interface: Algodocs is intuitive and easy to use, even for non-technical users. You

Algodocs

Top 5 Data Extraction Tools for 2025: Streamline Your Document Processing With AI

Back to Blog Table of contents On this page Top 5 Data Extraction Tools for 2025: Streamline Your Document Processing With AI Home › Blog › Algodocs › Top 5 Data Extraction Tools for 2025: Streamline Your Document Processing With AI Categories Algodocs Tags ai platform for data extraction algodocs data extraction from images invoice process ocr api By Shubhankar Biswas Published October 12, 2025, 18:57 Updated July 20, 2026, 04:07 Harnessing Advanced Technologies for Efficient Data Management Data processing is the backbone of modern businesses. As companies adopt cutting-edge technologies to boost efficiency, data extraction and storage become crucial in shaping their future. Whether you’re a large enterprise or a small business, handling substantial data is inevitable. Relying on manual methods is not only slow but also prone to errors, which can significantly impact your business’s efficiency and lead to potential losses. Thankfully, advancements in technology, particularly OCR (Optical Character Recognition) applications, have made data extraction much simpler and more accurate. The rise of artificial intelligence and machine learning has further enhanced OCR capabilities, making it incredibly easy to extract data from a wide range of documents, including blurry invoices and bills. In this blog post, we’ll explore the top 5 data extraction tools of 2025 that can help you efficiently manage your document data. Algodocs Best Data Extraction tool Algodocs is an advanced AI-powered data extraction platform designed to automate data extraction from PDFs, scanned images, and handwritten notes. When discussing the most reliable data extraction tools of 2025, Algodocs tops the chart With Algodocs, you can extract data from BOL documents, invoices, passports, ID cards, medical bills, or any type of document easily. Built with intelligent AI and ML algorithms, Algodocs can capture and extract data from blurry images, unstructured documents, and complex handwritten notes at 10X faster speed compared to any traditional or modern OCR apps.  The prebuilt extractors enable users to extract data from documents without any complex and lengthy setup. You don’t need any technical knowledge to use the Algodocs app. With a very intuitive and easy UI, Algodocs can be used by anyone from any background.  The seamless third-party app integration with Algodocs makes it one of the best choices for businesses to use as an AI tool. You can integrate Algodocs with Zapier, Google Docs, FTP, and other platforms for data integration.  Pros of Algodocs  High Accuracy: Algodocs utilizes advanced AI & ML algorithms to achieve over 99.99% accuracy in data extraction. This precision ensures minimal errors and reliable data processing, making it ideal for handling critical documents.  Ease of Use: The platform offers an intuitive and user-friendly interface, making it accessible even for non-technical users. The prebuilt extractor makes it super easy to use Algodocs for document processing. You don’t need extensive coding knowledge to create an extractor in Algodocs. With just a few clicks, you can extract data from a document easily.  Versatility: Algodocs supports a wide range of document types, including PDFs, Word documents, images, and handwritten notes. This versatility allows businesses to streamline various document processing tasks with a single tool.  API Integration: Algodocs offers a straightforward API for seamless integration with existing business systems and workflows. This integration capability enhances efficiency and eliminates the need for manual data entry. You can easily integrate Algodocs with third-party tools such as Zapier, SharePoint, Dropbox, REST API, and other services without paying extra costs.  Customer Support: Algodocs provides excellent customer support, assisting users in every possible way, even for small bundles. This support is invaluable for troubleshooting and learning best practices.  Affordable Pricing: Algodocs comes with very affordable and flexible pricing plans so that every business segment can utilize Algodocs features. Our basic plan starts at $23 USD per month and includes 300 monthly credits. You have access to all the integrations and other benefits in the plan, so you don’t need to pay extra for any integration or add-on services. You can also customize a plan as per your requirements. With lots of features and benefits, we can say that Algodocs is a great tool for the list of top data extraction tools of 2025. Cons of Algodocs Algodocs is a powerful tool for businesses looking to automate their document processing and improve efficiency. However, it’s essential to consider the potential drawbacks and evaluate whether it meets your specific needs and budget.  Docparser Docparser is an ideal document processing tool for converting PDFs and extracting data from various types of documents. It can be a great platform for medium and large businesses looking for data extraction and automation solutions. Pros Docparser excels in its ability to extract data accurately from documents. It is a great tool for all types of data extraction tasks, including processing different types of documents and invoices. The app’s accuracy is excellent, and the platform offers pre-built extractor options, allowing users to easily set up and extract data from documents. Additional add-ons such as parsing assistance, multi-factor account authentication, version control, and other features make it a highly capable data extraction product. Cons While Docparser offers excellent features, one of its biggest drawbacks is pricing. The basic plan starts at $30 USD, which can be expensive for some users. Additionally, extra charges apply for using any additional add-ons or features, which further increases the cost and could be a significant downside for the platform. Docsumo Docsumo is a powerful data extraction tool that allows you to easily extract information from documents and invoices. It includes features like automatic document classification, analytics, and batch processing, enabling efficient data capture and extraction from a wide range of document types. Pros One of the most highlighted features of Docsumo is its batch processing and accuracy in data extraction. With its robust capabilities, Docsumo is an excellent option for large businesses looking for reliable document processing solutions. Cons One of the biggest drawbacks of Docsumo is its pricing model. The pricing starts at $299 USD per month, which only includes 1,000 credits per month. This limitation can be a significant disadvantage for businesses with higher processing needs. Nanonets Nanonets is a feature-rich document

Algodocs

What Is Intelligent Document Processing (IDP) and How Can It Revolutionize Your Business in 2026?

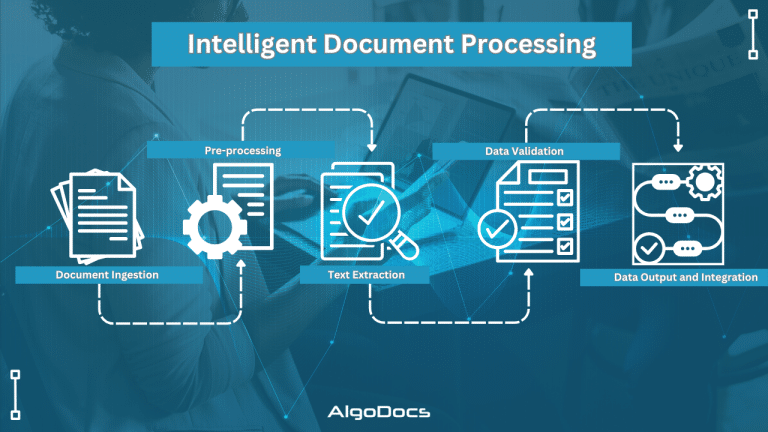
Back to Blog Table of contents On this page What Is Intelligent Document Processing (IDP) and How Can It Revolutionize Your Business in 2026? Home › Blog › Algodocs › What Is Intelligent Document Processing (IDP) and How Can It Revolutionize Your Business in 2026? Categories Algodocs Tags ai platform for data extraction algodocs deep learning guide IDP intelligent document processing machine learning ocr api By Shubhankar Biswas Published October 12, 2025, 18:51 Updated July 13, 2026, 06:16 In today’s digital age, data is crucial for every organization. However, a significant portion of this data resides within unstructured documents, such as contracts, invoices, forms, emails, and more. Manually processing data from these documents is time-consuming, error-prone, and costly for any business. Intelligent Document Processing (IDP) has emerged as a game-changing solution by leveraging the power of artificial intelligence (AI) and machine learning (ML). Document workflows and data extraction from these unstructured documents have become very easy. This comprehensive guide will explore the landscape of IDP platforms, their benefits, how they can be applied across various industries, key considerations for choosing an IDP solution, emerging trends, and how Algodocs can empower your business. What is Intelligent Document Processing (IDP)? A Deep Dive The IDP (Intelligent Document Processing) market is expected to reach $46.59 billion USD by the end of 2035, according to a report. As businesses heavily rely on, extraction, sorting, and managing data. These types of operations require a robust and reliable tool to that can provide useful insights about business metrics. That’s why the need for intelligent document processing tools is rising day by day. So, what is intelligent document processing? IDP is a sophisticated technology that automates the extraction, classification, and processing of data from various document types, regardless of format or structure. It achieves this by combining several core technologies: Optical Character Recognition (OCR): OCR converts images of text into machine-readable text. Modern OCR, often referred to as Intelligent Character Recognition (ICR), goes beyond basic character recognition by using deep learning models like Convolutional Neural Networks (CNNs) and Recurrent Neural Networks (RNNs). This allows it to handle complex layouts, handwritten text, low-quality images, multiple languages, and specialized fonts used in industries like healthcare (medical prescriptions) and law (legal documents). Accuracy is often measured using metrics like character error rate (CER) and word error rate (WER), with advanced systems achieving very low error rates. Natural Language Processing (NLP): NLP analyzes the extracted text to understand its meaning and context. It employs techniques like tokenization (breaking text into individual words or phrases), stemming and lemmatization (reducing words to their root form), Named Entity Recognition (NER) (identifying specific entities like names, dates, and locations), Part-of-Speech (POS) tagging (identifying the grammatical role of each word), sentiment analysis (determining the emotional tone of the text), topic modelling (discovering underlying topics within a collection of documents), text summarization (creating concise summaries of longer texts), relationship extraction (identifying relationships between entities), and semantic analysis (understanding the meaning of words and phrases in context). Machine Learning (ML): ML is the engine that drives IDP’s adaptability and continuous improvement. Supervised learning involves training the system on labelled data to recognize specific document types and extract relevant fields. Unsupervised learning helps discover patterns and structures in unlabelled data for improved classification and clustering. Reinforcement learning allows the system to learn through feedback and iterative improvement. Training data quality and quantity are crucial for model accuracy. Techniques like cross-validation and hyperparameter tuning are used to optimize model performance. Active learning allows the system to request human input for ambiguous cases, further improving its accuracy over time. Computer Vision: Computer vision enables IDP to “see” and interpret visual elements within documents. Techniques like image classification (categorizing images), object detection (identifying specific objects within images), image segmentation (dividing an image into multiple segments), table and form extraction (accurately extracting data from structured tables and forms), barcode and QR code recognition (automating data capture from barcodes and QR codes), signature verification (authenticating signatures), and logo detection (identifying company logos) are used. Robotic Process Automation (RPA): RPA acts as the orchestrator for IDP workflows, automating downstream processes based on the extracted data. It integrates IDP with other enterprise systems like CRM, ERP, and ECM, automating data validation, routing documents to appropriate departments, and triggering subsequent actions. IDP Workflow: A Detailed Breakdown: Document Ingestion: Documents are ingested through various channels: scanning, uploading files, APIs, email attachments, and more. Pre-processing: Images are optimized for OCR through techniques like noise reduction, skew correction, and image enhancement. OCR and Text Extraction: OCR extracts text from the document. NLP and Data Understanding: NLP analyzes the extracted text. Data Extraction and Validation: Relevant data is extracted and validated against predefined rules or databases. Human-in-the-Loop (HITL): Human reviewers handle exceptions and complex cases where the system has low confidence. Data Output and Integration: Extracted data is delivered in structured formats (CSV, JSON, XML) or directly integrated into business applications. The Benefits of IDP: Quantifiable Impacts Efficiency Gains: IDP can dramatically reduce document processing time, often by up to 90%. For example, processing hundreds of invoices that previously took several days can be completed in just a few minutes or hours. This increased throughput allows businesses to handle higher volumes of documents without increasing staffing. Cost Reduction: By eliminating manual data entry and reducing errors, IDP can lower operational costs by up to 70%. Reduced rework, fewer errors requiring correction, and optimized resource utilization contribute to significant cost savings. Accuracy Improvement: IDP achieves data extraction accuracy rates of 99% or higher, significantly minimizing data entry errors and improving data quality and consistency. This reduces costly downstream errors and improves compliance. Enhanced Security and Compliance: IDP systems offer robust security features like data encryption, access control, and audit trails, ensuring compliance with data privacy regulations like GDPR, HIPAA, and others. Improved Customer Experience: Faster processing times translate to quicker service delivery, leading to improved customer satisfaction. For example, faster loan approvals or insurance claims processing can significantly enhance the customer

Algodocs

OCR vs IDP: Which one is better? How to choose the right technology to elevate your business.

Back to Blog Table of contents On this page OCR vs IDP: Which one is better? How to choose the right technology to elevate your business. Home › Blog › Algodocs › OCR vs IDP: Which one is better? How to choose the right technology to elevate your business. Categories Algodocs Tags AI ai platform for data extraction algodocs IDP ML OCR By Shubhankar Biswas Published October 12, 2025, 18:41 Updated July 13, 2026, 08:04 The debate OCR VS IDP—often sparks conflicting opinions, as the choice depends on the specific needs and nature of the technology required. Both technologies serve the purpose of extracting data from various types of documents for business and personal use. In today’s data-driven world, businesses face the challenge of managing vast amounts of information stored in physical and digital documents. Efficient and accurate data extraction has become essential for streamlining operations, enhancing decision-making, and maintaining a competitive edge. Two technologies are leading this data extraction revolution: Optical Character Recognition (OCR) and Intelligent Document Processing (IDP). Although often used interchangeably, these technologies offer distinct capabilities and serve different purposes. This comprehensive guide will explore the key differences between OCR and IDP, their ideal use cases, and how to determine the right solution for your business needs. What is OCR? Optical Character Recognition (OCR) is a technology that converts images into machine-readable text data. These documents can be handwritten notes, typed, or printed in the form of PDFs, word documents, or image files. It works by analyzing the visual patterns of characters and comparing them to stored character sets. Once recognized, the text can be edited, searched, and stored electronically. Think of it as a digital eye that scans a document and translates visual characters into a digital language that computers can understand. OCR technology helps save time, reduce human errors during data extraction, and lower operational costs. Although OCR technology has been around for a long time, it has gained significant traction in recent years. Businesses increasingly rely on OCR-based tools for various data extraction and document processing tasks, driven by the growing need to manage and extract large volumes of data efficiently. What is IDP? Intelligent Document Processing (IDP) is a revolutionary advancement that leverages Artificial Intelligence (AI) and Machine Learning (ML) to enhance document processing workflows. Unlike OCR, which is limited to reading and extracting text from documents, IDP takes things a step further by analyzing, filtering, sorting, and automating data extraction from a variety of sources, including emails and other digital platforms. IDP builds on OCR by integrating AI and ML to automate the entire document processing lifecycle. It doesn’t just recognize characters; it understands the context and meaning of the extracted information. IDP systems can classify documents, extract specific data fields (such as names, dates, or invoice numbers), validate the data, and seamlessly integrate with other business systems. Think of it as a digital assistant that not only reads documents but also comprehends their purpose and extracts the most relevant information, making your workflows smarter and more efficient. Key Differences Between OCR Vs IDP The fundamental difference lies in their level of intelligence and automation. OCR focuses solely on character recognition, while IDP handles the entire document processing lifecycle. Here’s a breakdown: Feature OCR IDP Core Function Converts images of text to machine-readable text Automates the entire document processing workflow, including classification, data extraction, validation, and integration. Intelligence Basic character recognition Advanced AI and ML algorithms for context understanding, data validation, and learning from new document types. Automation Limited to text extraction High level of automation, capable of handling complex document layouts and variations. Data Extraction Extracts all text present in the image Extracts specific data points based on predefined rules or machine learning models. Document Types Simple, structured documents with consistent layouts Complex, semi-structured, and unstructured documents with varying layouts and formats. Error Handling Prone to errors with low-quality images or complex layouts More robust error handling through data validation and human-in-the-loop verification. Scalability Limited scalability for complex document processing Highly scalable for large volumes of diverse documents. When is OCR a Good Choice? OCR is a suitable solution when dealing with: Simple, structured documents: Forms, scanned letters, or printed reports with consistent layouts. High-quality images: Clear, well-scanned documents with minimal noise or distortion. Basic text extraction: When the primary goal is to convert images to searchable text without the need for specific data extraction. Low document volume: When processing a small number of documents. When is IDP a Good Choice? IDP is the preferred choice for: Complex, semi-structured, and unstructured documents: Invoices, contracts, medical records, passports, and other documents with varying layouts and formats. Specific data extraction: When extracting key information like dates, names, addresses, or financial figures is crucial. High document volume: When processing large quantities of diverse documents. Automated workflows: When integrating document processing into existing business systems. Improved accuracy: When high accuracy is essential due to the use of AI and ML. Types of Documents Can Be Processed by OCR OCR excels at processing: Scanned documents Printed reports Typed letters Simple forms Images containing text Types of Documents Can Be Processed By IDP IDP can handle a wider range of documents, including: Invoices Purchase orders Contracts Medical records Financial statements Legal documents Emails Handwritten notes (with varying accuracy) Industries Benefiting from OCR Industries that can benefit from OCR include: Libraries and archives: Digitizing historical documents. Publishing: Converting printed books and articles into digital formats. Data entry: Automating basic data entry tasks. Industries Benefiting from IDP IDP offers significant advantages to industries dealing with large volumes of complex documents: Finance: Automating invoice processing, loan applications, and KYC (Know Your Customer) procedures. Healthcare: Managing patient records, processing insurance claims, and extracting data from medical reports. Legal: Reviewing contracts, managing legal documents, and conducting e-discovery. Insurance: Processing claims, managing policy documents, and automating underwriting. Logistics: Processing shipping documents, tracking shipments, and automating customs clearance. How To Choosing Between OCR Vs IDP Confusion The choice between OCR and IDP depends on your specific business needs and document processing requirements. OCR is a suitable option for small businesses that handle a

Algodocs

Top 5 Challenges in Document Data Extraction and How to Overcome Them With Algodocs

Back to Blog Table of contents On this page Top 5 Challenges in Document Data Extraction and How to Overcome Them With Algodocs Home › Blog › Algodocs › Top 5 Challenges in Document Data Extraction and How to Overcome Them With Algodocs Categories Algodocs Tags AI Data Extraction ai platform for data extraction algodocs data extraction Document Automation IDP OCR By Shubhankar Biswas Published October 12, 2025, 18:32 Updated July 13, 2026, 06:37 In today’s fast-paced digital world, document data extraction has become an essential process for businesses across various industries. Whether it’s extracting data from invoices, medical records, contracts, or financial reports, the need for efficient and accurate document processing has never been greater. As the need for data in business grows, so does the requirement for intelligent document processing platforms and other AI technologies for document data extraction. However, the path to seamless document data extraction is not without its challenges. In this blog, we will explore the top five challenges in document data extraction and how Algodocs can help overcome them. By the end, you’ll gain a comprehensive understanding of how to streamline your workflows and achieve better efficiency. What is Document Data Extraction? Document data extraction refers to the process of extracting structured or unstructured data from various document formats, such as PDFs, scanned images, or handwritten forms. This data is often critical for making business decisions, automating workflows, or maintaining accurate records. With advancements in technology, many organizations rely on automated tools for data extraction. However, the complexity of handling diverse document formats and ensuring data accuracy remains a significant hurdle. Before we dive into the top challenges faced by businesses in this domain, we need to understand the two major types of data extraction from documents. Types of Document Data Extraction: Manual Vs Automated Extracting data from documents is a complex task with both advantages and disadvantages. In recent years, the advent of artificial intelligence and machine learning has made data extraction smoother and more accurate. When it comes to data extraction, you have two options: manual data extraction and automated data extraction. Manual Document Data Extraction: In manual document data extraction, we copy and paste data from one document to another file. This basic method is considered very time-consuming and prone to errors. Manual data extraction is limited to a few document types and cannot process data from a variety of document formats. Automated Document Data Extraction: Automated document data extraction uses technologies such as OCR and Intelligent Document Processing (IDP) to automate the extraction of data from various types of documents and data sources. This method employs advanced technologies such as AI, ML, and NLP to capture and process data from both structured and unstructured document types. One key feature of automated data extraction is the speed and accuracy of the technology, and it can be scaled according to operational needs. Algodocs is an excellent example of an automated data extraction tool that allows you to extract data from both structured and unstructured documents. The Top 5 Challenges in Document Data Extraction Diverse Document Formats: Businesses deal with a wide range of document types, including PDFs, images, scanned forms, and handwritten notes. Each document format comes with its own set of challenges. For example: PDFs may contain hidden text layers or embedded images that are difficult to extract. The complexity of PDFs can vary greatly depending on how they were created, making it challenging to extract data accurately. Scanned documents often suffer from poor quality or inconsistent alignment. Issues such as low resolution, skewed scans, and variations in lighting can all affect the accuracy of data extraction from scanned documents. Handwritten documents pose significant challenges due to varying handwriting styles and legibility. The diversity in handwriting can lead to errors in recognizing characters and extracting correct information. These issues make it difficult to standardize data extraction processes and require tools that can adapt to diverse formats. Advanced technologies like AI and Machine Learning are essential to handle these variations effectively, ensuring that the extracted data is accurate and reliable. Solution: Algodocs’ AI-powered algorithms are designed to handle diverse document formats seamlessly. It uses Artificial Intelligence (AI) and Machine Learning to extract text from images and scanned documents while maintaining high accuracy. The platform’s adaptability ensures that even complex documents are processed efficiently. 2. Data Accuracy and Consistency Accuracy is paramount in document data extraction, especially when dealing with critical information like medical records, financial statements, or legal documents. Errors in data extraction can lead to serious consequences, including financial loss or compliance issues. While manual data extraction is one of the most common methods prone to data inaccuracies, basic OCR extraction tools sometimes fail to extract data accurately, leading to various operational issues. Common causes of inaccuracy include: Poor Document Quality: Poor document quality, such as smudged or faded text, often creates issues when scanned documents are in PDF or image formats. Scanning documents with scanners frequently results in blurry images, making data extraction from these documents a significant challenge.   Misinterpretation of Symbols, Fonts, or Layouts: Misinterpretation of symbols, fonts, or layouts in documents is one of the reasons why inaccuracies in data extraction occur. OCR technology or manual data extraction methods sometimes can’t read and understand these complex symbols or fonts, leading to errors. Variations in Document Templates and Structure: Variations in document templates and structure can also create issues with data extraction accuracy and consistency. Different formats such as PDF, Image, and Word documents offer different layouts, and extracting data from these varying layouts can sometimes cause accuracy issues. Maintaining consistency across multiple documents or batches is another challenge. Without a reliable system, errors can propagate and undermine data integrity. Solution: Algodocs employs advanced machine learning models that continuously improve accuracy by learning from data patterns. Its robust validation features allow users to cross-check extracted data against predefined templates, ensuring consistency and reliability. 3. Dealing with Unstructured Data One of the major challenges businesses face when extracting data from documents is dealing with unstructured

insurance data extraction
Data Extraction, Insurance Data Extraction

Insurance Data Extraction: Automating Policy and Claim Processing with AI

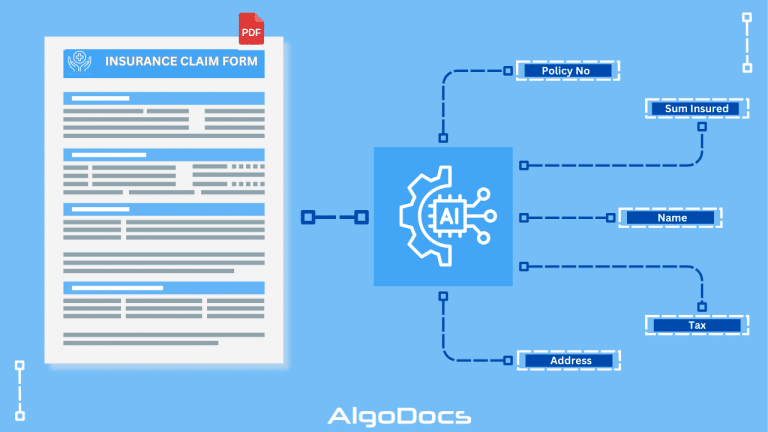
Back to Blog Table of contents On this page Insurance Data Extraction: Automating Policy and Claim Processing with AI Home › Blog › Data Extraction › Insurance Data Extraction: Automating Policy and Claim Processing with AI Categories Data Extraction Insurance Data Extraction Tags ai platform for data extraction algodocs character recognition deep learning IDP Insurances Data Extraction intelligent document processing By Shubhankar Biswas Published October 12, 2025, 18:20 Updated July 23, 2026, 05:31 The modern insurance sector operates on massive volumes of information and insurance data extraction is a crucial part of insurance industry business process. Every single day, insurance carriers, third-party administrators, brokers, and agencies process thousands of files. These files range from policy applications and loss notices to medical bills, repair estimates, legal notices, and property appraisal reports. Within this ocean of paperwork lies the essential information required to underwrite risks, calculate premiums, settle claims, detect fraud, and maintain regulatory compliance. However, a significant challenge facing the insurance industry today is that up to eighty percent of this critical information arrives in unstructured or semi-structured formats. Scanned PDF files, digital images, physical paper forms, email attachments, and handwritten adjuster notes cannot be directly read or processed by traditional enterprise databases. Historically, companies relied heavily on manual data entry to transfer details from incoming documents into core operational platforms like claims management systems or policy administration suites. Manual processing creates severe bottlenecks. It inflates operational expenses, slows down service delivery, introduces human error, and frustrates policyholders who expect immediate digital service. To overcome these challenges, progressive insurance providers are transitioning toward automated insurance data extraction. Driven by advances in AI OCR, Machine Learning, and Intelligent Document Processing, modern extraction tools allow organizations to transform messy, unformatted files into structured, machine-readable digital data in seconds. This comprehensive guide explores the fundamentals of automated insurance data extraction, examining the types of documents processed, the hidden costs of manual workflows, the business benefits of artificial intelligence, and the leading software solutions shaping the market. What is Insurance Data Extraction? Insurance data extraction is the automated technology process of reading, identifying, capturing, and converting information from paper or digital insurance records into structured digital data formats. Instead of requiring human workers to manually read documents and type values into software screens, an automated insurance data extraction workflow ingests files, interprets their contents, extracts specific data fields, and exports clean data directly into core databases or enterprise applications. The insurance data extraction workflow relies on an integrated stack of advanced technologies: Document Ingestion: The system collects inbound files from multiple channels, including email inboxes, mobile application uploads, scanned physical mail, cloud storage, or secure web portals. Optical Character Recognition (OCR) and AI OCR: Legacy OCR converts scanned document images into text strings. Next generation AI OCR goes further by recognizing complex handwriting, low-resolution scans, and non-standard typography. Intelligent Document Processing (IDP): Combining artificial intelligence with natural language processing, Intelligent Document Processing understands the context and semantic meaning of words. It recognizes that a dollar figure located next to the word deductible represents a specific financial field rather than a premium payment. Machine Learning and Field Validation: Machine learning algorithms continuously improve extraction accuracy over time. Automated validation rules cross check extracted policy numbers, dates, and mathematical totals against internal enterprise databases to verify accuracy. Data Export: Clean, structured data is formatted into structured payloads such as JSON, XML, or CSV, and delivered directly to core policy or claims platforms via APIs. Through AI insurance data extraction, carriers can automate repetitive administrative steps, reduce turnaround times, and establish seamless insurance workflow automation across every department. Types of Documents Used in Insurance Industry for Insurance Data Extraction Insurance carriers handle a vast assortment of forms, reports, and contracts. Each document type possesses unique layouts, terminology, and data extraction requirements. Automated insurance document processing systems are designed to process diverse document types efficiently. 1. Policy Documents and Applications Policy applications and insurance binders represent the foundational agreements between policyholders and carriers. Extracting accurate data during policy origination is crucial for setting terms and issuing coverage. Key documents include: ACORD 125 Applications: The standard commercial insurance application form containing applicant business details, policy effective dates, location details, and requested coverage limits. Policy Schedules and Declarations Pages: Summary pages detailing coverage types, policy numbers, named insureds, endorsement listings, and premium amounts. Endorsement Forms: Amendments to existing policy contracts that modify coverage terms, add new insured assets, or change liability limits. Accurate policy data extraction ensures that customer profiles, coverage clauses, and premium figures match internal records without requiring manual entry. 2. Insurance Claims and Loss Notices When policyholders suffer a loss, rapid claims intake is essential for customer satisfaction. Automated insurance claims data extraction parses critical details from early claims documentation: First Notice of Loss (FNOL) Reports: Initial notifications submitted by policyholders or agents detailing how, when, and where an incident occurred. ACORD Loss Notices: Standardized notices such as the ACORD 2 Automobile Loss Notice or ACORD 3 Property Loss Notice, capturing policy details, driver information, and loss descriptions. Incident and Police Reports: Official law enforcement collision records containing narrative descriptions, driver statements, weather conditions, and citations. Automating insurance claims data extraction accelerates claim registration, enabling immediate assignment to claims adjusters or automated decisioning engines. 3. Medical Records and Healthcare Billing Forms Health, workers compensation, and personal injury protection claims involve complex clinical and billing records. These documents combine typed text, medical terminology, complex codes, and handwritten notes: CMS-1500 and UB-04 Forms: Standard medical billing claim forms used by physicians, medical practices, and institutional healthcare providers. Explanation of Benefits (EOB): Statements sent by health plans explaining covered services, approved amounts, deductible applications, and patient responsibility. Clinical Discharge Summaries and Doctor Notes: Narrative medical charts containing diagnoses, treatment histories, and surgical notes. Automated extraction engines capture critical diagnostic codes such as ICD-10, procedure codes such as CPT, billing line items, and provider identification numbers to streamline health claims auditing. 4. Underwriting Documents and Financial Statements Underwriters must review complex

Scroll to Top