Algodocs

ai platform for data extraction

Best Software for Automating Document Processing
Data Extraction

Best Software for Automating Document Processing: A Practical Guide for 2026

Back to Blog Table of contents On this page Best Software for Automating Document Processing: A Practical Guide for 2026 Home › Blog › Data Extraction › Best Software for Automating Document Processing Categories Data Extraction Tags algodocs automation data extraction By Shubhankar Biswas Published August 24, 2026, 09:35 Modern business runs on data. The more data a business can capture, process, and analyze, the better the outcome. But to process data in large quantities, you need a reliable tool. That technology is known as document processing. However, choosing the best software for automating document processing is often difficult. Documents come in various forms, including invoices, bills, financial reports, contracts, and even handwritten notes. To process all of these efficiently, you need robust IDP tools that can capture, extract, and automate the entire journey in just one click. Finding a reliable solution among the thousands of document processing applications available on the market can be overwhelming and frustrating. Every vendor claims to have the most accurate AI, the fastest engine, or the easiest interface. But the reality is that the right choice depends entirely on your specific workflow, document types, and business goals. That is why this guide exists. It will help you cut through the noise and find the best tool for document processing for your specific needs. But before we compare platforms, let us first understand what document processing actually is and why it matters so much in today’s data-driven world. . TL;DR Summary Choosing the best software for automating document processing does not have to be complicated. Automated tools save time, reduce errors, and scale with your business. Cloud document capture has become the standard for modern teams. Algodocs stands out as a top choice because it offers template-free AI extraction, strong security, and affordable pricing. Start with one document type, test with real documents, and keep a human in the loop for exceptions. What is Document Processing? Document processing is the method of capturing and extracting data from various types of documents, such as invoices, bills, passports, and contracts, using automated technology. These tools can be computer software like OCR (Optical Character Recognition), IDP (Intelligent Document Processing), ICR (Intelligent Character Recognition), or AI (Artificial Intelligence). The oldest method is manual document processing, where humans identify and extract data by hand. This approach is slow, expensive, and full of errors. Anyone who has ever spent hours typing data from PDFs into an Excel spreadsheet knows exactly how painful this process can be. On the other hand, automated tools use technology to complete the process with greater accuracy and faster speed. We often call this cloud document capture, as the data is extracted using web-based tools and saved on a secure cloud platform. This is the foundation of the best AI document processing available today, as it removes the physical limitations of local hardware and allows teams to work from anywhere. Instead of being tied to a desk with a scanner, employees can simply upload a photo from their phone or forward an email to a processing inbox. The system handles the rest. The shift from manual to automated processing is not just a convenience; it is a competitive advantage. Businesses that automate their document workflows can process more volume with fewer resources, reduce costly errors, and free up their human talent for higher-value work. This is why so many organizations are actively searching for the best software for automating document processing to stay ahead of the curve. How Does Document Processing Work? In the manual method, a human expert uses analytical skills to read data from a document and then types that data into another file format. This is not only time-consuming but also mentally draining. After hours of repetitive data entry, even the most careful employee will start making mistakes. Those mistakes can lead to incorrect invoices, missed deadlines, and unhappy customers. In the automated method, computer software handles everything from start to finish. The system first captures the document, whether it arrives as a PDF, a scanned image, or a photo taken on a smartphone. Next, it extracts the relevant data points using AI algorithms that can identify names, dates, amounts, addresses, and other key fields. After extraction, the system validates the data to ensure it meets certain quality thresholds. If the confidence score is low, the document is routed to a human reviewer for a quick check. Finally, the validated data is exported to a database, CRM, or ERP system for further use. Once extracted, the data can be saved locally or on a cloud drive. From there, it can be shared with team members or integrated with third-party business apps to support smarter business decisions and organizational growth. This automated flow is the core advantage that separates modern IDP tools from outdated manual processes. The best part is that this entire journey can happen in seconds, not hours. A document that would take a human five minutes to process manually can be handled by software in under ten seconds. When you multiply that across thousands of documents per month, the time savings become enormous. Manual vs. Automated Document Processing There is a major difference between manual and automated data extraction methods. Understanding this difference is essential before you invest in any software. The table below highlights the key distinctions:y. These are the major differences. Features & Difference Automated Data Extraction Manual Data Extraction Speed Fast Slow Accuracy Accurate Not Accurate Cost Affordable Expensive Automation Fully Automated Not Available 3rd Party Integration Possible Not Possible Scalability Highly Scalable Not Scalable Best Suited For All types of business Limited to small business Human Supervision Only during exceptions Very High The biggest reason automated data extraction beats manual is reliability. Manual processing loses its value when dealing with large volumes. You cannot process 10,000 documents in a day with humans alone. Even if you hired a team of twenty data entry clerks, they would still struggle to keep up with that kind of volume, and
Agentic AI Document Processing
Algodocs, Data Extraction

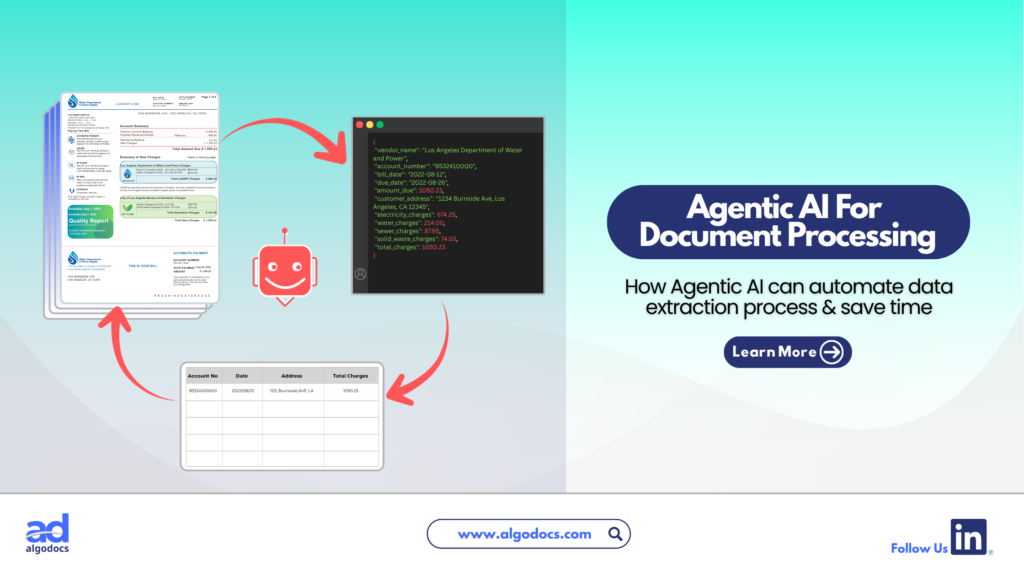
Agentic AI Document Processing: How To Automate Data Extraction Smartly With Agentic AI In 2026

Back to Blog Table of contents On this page Agentic AI Document Processing: How To Automate Data Extraction Smartly With Agentic AI In 2026 Home › Blog › Algodocs › Agentic AI Document Processing: How To Automate Data Extraction Smartly With Agentic AI In 2026 Categories Algodocs Data Extraction Tags agentic ai ai platform for data extraction data extraction By Shubhankar Biswas Published June 26, 2026, 04:09 Updated July 10, 2026, 06:04 When it comes to extracting and processing data from documents, there is no match for sophisticated, computer-powered tools like an Intelligent Document Processing (IDP) tool. Even traditional methods like OCR are effective for basic data extraction. However, in the age of AI, information moves faster than ever and older technologies like OCR are quickly becoming outdated in the face of emerging AI data extraction tools. These modern tools handle all the data extraction work with little or no human intervention. We are talking about Agentic AI, the new standard for automating data extraction from documents compared to older methods. Let us explore exactly what Agentic AI document processing is, how it works, and why it matters for your business. What is Agentic AI? Agentic AI is an autonomous tool able to plan and execute specific tasks with little or no human intervention. Unlike standard AI tools that are only good at providing specific answers to questions, Agentic AI goes further. It can find answers, plan entire workflows according to set goals, follow instructions, manage, organize, and filter data efficiently. In simple terms, Agentic AI tools can plan and execute tasks to achieve goals with minimal human help. So how does Agentic AI work in the document processing and data extraction space? Let us explore. How Agentic AI Works in Document Processing Agentic AI in document processing works when you provide specific instructions to AI agents. These agents can perform tasks like image preprocessing, layout adjustments, data capturing, and data filtration. Large Language Models are only able to perform one task at a time, and you always need human intervention. Agentic AI can perform all these tasks by itself. It only requires a few instructions or goals in the beginning, and the Document Agentic AI tool takes care of the rest. One of the biggest differences between an LLM based data extraction approach and an Agentic AI based approach is autonomy. Agentic AI can perform tasks from start to finish, while LLM extraction is limited to single, specific tasks. Document Ingestion and Preprocessing: The AI agent automatically ingests files from emails, folders, or APIs. It enhances image quality, fixes skewed angles, and readies the file for reading. Layout and Context Analysis: Instead of just reading flat text, specialized vision agents look at the document structure. They map out tables, headers, signatures, and charts to understand the visual context. Semantic Data Extraction: Agents pull out the exact data you need, like an invoice total or patient ID. They do this by understanding the meaning of the words instead of just their location. Validation and Action: The agent cross checks the extracted data against your company databases to ensure accuracy. If everything is correct, it automatically pushes the data into your ERP or CRM system without a human pressing a button. Difference Between Agentic AI Data Extraction and LLM Based Extraction (IDP) To truly understand Agentic AI document processing, we need to see how it compares to older LLM based Intelligent Document Processing (IDP) systems. Key Features Agentic AI Based Data Extraction LLM Based Data Extraction (IDP) Autonomy Fully autonomous. Plans and executes end to end workflows. Requires human prompts and step by step guidance. Handling Complex Layouts Understands charts, nested tables, and complex formats easily. Struggles with anything outside of a standard text template. System Integration Can log into your ERP, check data, and trigger actions on its own. Usually extracts data into a file like a CSV and waits for a human. Exception Handling Reasons through errors and searches for context in past documents. Flags errors and stops the process until a human fixes it. Scale and Speed Multiple specialized AI agents work together as a team at the same time. A single model processes one task at a time sequentially. Benefits of Agentic AI Based Document Processing Traditional data extraction methods are slow and prone to errors. A business that processes over 10000 documents a day cannot rely on manual data extraction. Manual methods lack speed, contain human errors, lack automation, and require continuous monitoring. An Agentic AI document processing system changes the game entirely. Research indicates that Agentic AI could create nearly $450 billion in value for organizations by 2028. Here is why this technology is so beneficial: Zero Template Flexibility: Older OCR tools break if a vendor changes their invoice layout. Agentic AI document processing does not rely on rigid templates. Because it understands the meaning of the document, it can read a completely new layout perfectly on the first try. True Automation: Traditional systems extract data and drop it into a spreadsheet. Agentic AI takes action. If it reads an invoice, it can automatically log into your accounting software, match the invoice to a purchase order, and schedule the payment. Multi Modal Understanding: Today documents are messy. They contain text, handwritten notes, barcodes, and charts. Agentic systems use multiple specialized agents working together. One reads the text, another analyzes the charts, and another verifies the handwriting. Massive Cost Savings: By shifting from a human driven process to a fully autonomous AI workforce, businesses can scale up their document processing overnight without needing to hire more staff. Humans only step in to handle highly strategic decisions. How AlgoDocs Agentic AI Processes Documents and Data Extraction When looking at real world platforms, AlgoDocs is a powerful example of how modern data extraction works. AlgoDocs uses a blend of optical character recognition (OCR), machine learning, and advanced AI models to turn messy documents into structured, usable data. With Agentic AI document processing, AlgoDocs acts like a versatile

intelligent document processing

IDP Use Case: Transforming Restoration Practices

Earthquakes, hurricanes, mudslides, electrical fires, and burst pipes are some of the natural incidences that are usually unforeseen. Buildings that are often at the receiving end during catastrophic calamities require immense repair work. Any comprehensive structure will, in this respect, indeed call for disaster recovery management, especially if it is a house or a company. It has scaled tremendously to be vital software in the construction industry, but it is notably critical in the catastrophe repair industry, where most companies are small. Table of Contents: But as structures progress, many organizations like yours struggle to cope with change. Often, the driving force of success is in the technology that forms the basis of these organizations. Let us think of the building and restoration industry and see what we come up with. These companies have to estimate all possible costs for a building construction project, including additional costs such as salary for office employees, wear and tear of equipment, office rent and other overhead expenses, and cost of all the materials used and wages to workers. Enhancing Data Management in Restoration Processes Intelligent Document Processing (IDP) tools can capture information from any format that has not been pre-formatted, including images and handwritten writings. This can be of great importance, especially in restoration processes where data could be in large quantities, in the form of field notes and sketches, among other things. The Importance of Accurate Costs and Expenses Some of the factors one needs to understand well to accurately estimate the cost of the project include the building material costs, the requirements, the procedures, and the codes that are to be followed, as well as the need to understand the market trends in terms of pricing. Such information may be found by analyzing a bid package and working through the contingencies and profit inherent in a bid or a given project. Two Significant Challenges: Documentation obstacles: One of the challenges associated with restoration events is collecting all the relevant and non-concocted paperwork. Some of the effects of this cumbersome procedure include the failure to complete some forms or the delay in completing them. Accounts Receivable Delays are attributed primarily to fourteen struggles stemming from a high turnover rate in accounting: payment cycles take longer. This not only impacts cash flow but also definitely causes a lot of headaches for the business’s dealings with its customers. The Impact of Intelligent Document Processing (IDP) Software on Restoration Businesses: Implementing Intelligent Document Processing (IDP) Several Challenges. Here are some of the key ones: Case Study Use case for restoration: The repair company wishes to provide the customer with an overview of line-item estimates for the job. Cost estimates should not be utilized as a list of negotiable items. Supplemental costs may apply if more damage or repair that has not been found or is hidden below present finishes is required. This also enables the client to correct himself or herself if they chose compositions that are not within the estimate or if they need extra work. This is because, in the course of the project implementation, changes will be made to adjust for the revised estimate and present it to the client. Any changes made to these documents will be recorded in a change order and presented to the customer for revision. System: It is a form of advanced digital document processing with natural language processing, multimedia processes, and feature extraction. Primary actor: Accountant/bookkeeper/Customer Scenario: To meet the customer’s request to extract the estimated line-item information from the final amount, the following processes should be considered: They ask for the extracted data to be formatted differently than the original document’s formatting. They clearly explain what should be ignored and what needs to be extracted. There are a total of 11 headers in the PDF; each row value contains three different pieces of information: one is the labor, the second is the material, and the third is the equipment information. They need to extract the labor and material information. For example, the following are the instructions for the needed to be extracted data and how it should look like output: Tabular output with headers and the order they should be in JSON form: ·”ITEM#”, mapped from the label in Yellow (as in the picture above) ·”ROOM”, mapped from the label in dark green (as in the picture above) ·”UNIT”, mapped from the label in Red (as in the picture above) ·”QTY”, mapped from the label in light blue (as in the picture above) ·”UNIT PRICE”, mapped from the label in light green (as in the picture above) ·”TOTAL” mapped from the label in pink/magenta (as in the picture above) However, we still need to extract and differentiate data for Labor and Material information. While mapping the extracted data to the new headers, as requested by the customer. As complicated as it looks and sounds, Algodocs can do exactly this request easily.  How to Use Algodocs to Extract We only need a sample file uploaded to Algodocs to create the extractor. There are many ways to upload a sample document. The user can automate importing files to Algodocs uploading from their device, business email, Gmail, or other cloud storage. Once the documents are uploaded, the system will extract data from your documents using Algodocs’ advanced AI engine without relying on templates or even labeling and training your files.  The results are the actual contents extracted from the sample document according to the rules you specify. We have Rule-based extraction and artificial intelligence mining, which can be integrated to synthesize both extraction methods. This can help you further improve your extracted data by putting it into the correct form and structure.  The system makes it easy to control extracted data from your documents and handle business exceptions. It allows you to export the extracted data directly to an Excel Spreadsheet or, with the integration of Zapier, automate exporting extracted data directly to your email, Google Sheets, or other cloud storage. Example of Output in Excel Key Takeaways This should explain how Algodocs has boosted the restoration business and its experience with the solution to prove that technology can transform any business. Let your team be an example of how adopting effective and progressive concepts can

bill of lading

How Algodocs enhances bill of lading processing

Back to Blog Table of contents On this page How Algodocs enhances bill of lading processing Home › Blog › bill of lading › How Algodocs enhances bill of lading processing Categories bill of lading Tags ai platform for data extraction algodocs Bill of Lading data extraction from images ocr api web-based ai platform for data extraction By Shubhankar Biswas Published October 13, 2025, 12:24 Updated July 23, 2026, 07:35 A bill of lading, shortened as BL or BoL, is a legal document given by a carrier (a company that provides transportation) to the shipper. It outlines the particulars of the goods being transported, including the kind, quantity, and destination of the goods. In addition, a bill of lading functions as a shipping receipt when the carrier finalizes the delivery of the goods after a given destination. This document must accompany the shipped products, no matter the form of transportation, and must be signed by an authorized representative from the carrier, shipper, and receiver. What Is the Purpose of a Bill of Lading? A bill of lading has three primary purposes. First, it is a document of title to the goods described in the bill of lading. Second, it is a receipt for the shipped products. Finally, it represents the agreed terms and conditions for the transportation and eventual release of the shipped goods. What Is in A Bill of Lading? Typically, a bill of lading will include the names and addresses of the shipper (consignor) and the receiver (consignee), shipment date, quantity, exact weight, value, and freight classification. Also included is a complete description of the items, including whether they are classified as hazardous, the type of packaging used, any specific instructions for the carrier, and any special-order tracking numbers. Why Is a Bill of Lading Important? A bill of lading is a legally binding document. The carrier and the shipper are given all the essential details to help them process a shipment correctly. Hence, it can be used in litigation if the situation requires it. The parties to it will be highly knowledgeable about the document as required by the law to ensure that there is no compromise in the safety and security of your goods. A bill of lading is undisputed proof of shipment. Furthermore, it allows for segregating duties, a vital part of a firm’s internal control structure, to prevent theft. Different Types of Bills of Lading Some of the most common include: Inland bill of lading Ocean bill of lading Through bill of lading Negotiable bill of lading Uniform bill of lading Challenges With Manual Processing Some of the known challenges are: Logistics companies are confronted with vast volumes of data through files in document form, such as invoices, airline bills, price lists, HR forms and payrolls, customs forms, and so on. Manual data management is time-consuming and error-prone. Human data entry errors can lead to costly consequences. Implementing Intelligent Document Processing (IDP) Much of the information needed to execute logistics and supply chain operations is manually extracted from data sources such as the Bill of Lading. Automating the processing of instructions for the Bill of Lading proves to be crucial in increasing back-office productivity and, consequently, improving customer service performance. If traditionally conducting these activities by manually copying and pasting data carries the risk of errors and is an obstacle to maximizing operational efficiency, the value of automation must be highlighted. Benefits Of Intelligent Document Processing (IDP) Accuracy: AI-driven IDP has the advantage of minimizing human factors and error occurrence, which in return produces more quality. Continuous Learning: AI models can learn from humans, thus enabling them to get better results even without human assistance. Cost Savings: Laboratory test costs decrease when data is not appropriately edited, prevented by IDP. Data Extraction: IDP excels in extracting names, dates, addresses, and amounts from BoLs. Quality Assurance: Human interaction ensures precision modeling. Guaranteed Quality: The IDP introduced AI computing and on-demand data collection to achieve valid results. CASE STUDY Imagine XYZ company, which is a logistics firm. It receives the shipment. The manager determines the type and amount of goods that need to be ordered. They then fill out a purchase order (PO), and XYZ’s owner reviews and initials each PO before it is emailed to the vendor. The vendor gathers the orders and signs a bill of lading along with a representative from the overnight carrier. The forwarder then supplies products to the ship and provides the invoice to the manager, who compares the bill of lading details with what was mentioned on the PO. If the information matches, the PO and the bill of lading are sent to the owner, who reviews the documents and writes a check payable to the vendor. Fields That Can Be Extracted: OT PRO Number Consignee City Consignee State Consignee Zip Total Weight Handling Unit Description The list goes on and on. Example of extract data output: Enhancing Accuracy with Automated Data Extraction Algodocs can extract data automatically from the Bills of Lading. This step dramatically improves efficiency and offers new prospects for success in logistics. Applying Algodocs to the Bill of Lading allows the necessary data to be automatically extracted from the PDFs and images of the handwritten document received from the carrier and a new document structure from the Bill of Lading to be created quickly, eliminating the need for repetitive and error-prone manual work. Improving Efficiency with Algodocs AI Algorithms Bill of Lading instructions are often accompanied by various documents in different formats, as each company chooses the format best suited to its needs when sending instructions to the carrier. Algodocs represents a breakthrough in managing Bill of Lading data extraction because Algodocs AI algorithms process text recognition; this process not only speeds up processing but also minimizes the possibility of errors. KEY TAKEAWAYS Algodocs is a potent system that combines OCR, NLP, and ML technologies to provide a tool capable of extracting data from heterogeneous documents. It is particularly useful in creating a Bill of Lading. With Algodocs, you can automatically extract any field

Algodocs, Data Extraction, Image Data Extraction

How to Extract Handwritten Data from PDFs with Algodocs?

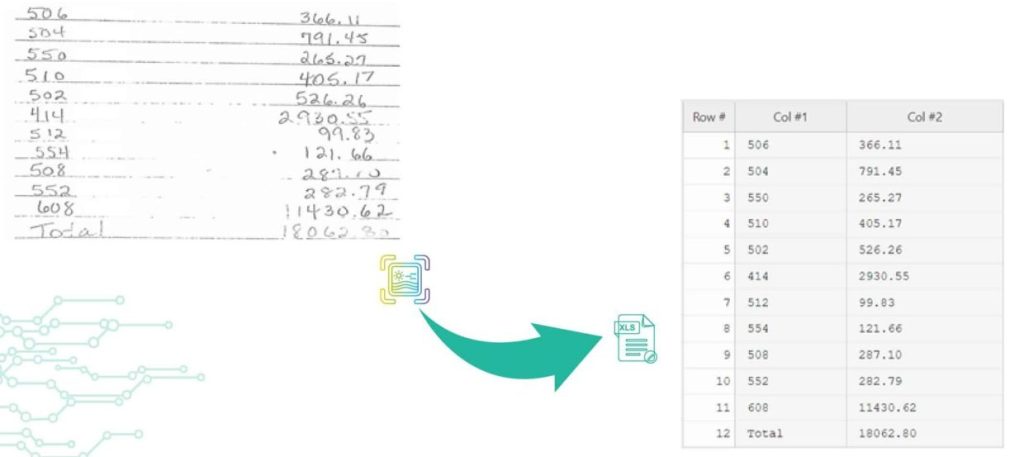
Back to Blog Table of contents On this page How to Extract Handwritten Data from PDFs with Algodocs? Home › Blog › Algodocs › How to Extract Handwritten Data from PDFs with Algodocs? Categories Algodocs Data Extraction Image Data Extraction Tags ai platform for data extraction algodocs character recognition data extraction from images handwritten pdf How to Extract Handwritten Data from PDFs web-based ai platform for data extraction By Shubhankar Biswas Published October 13, 2025, 12:19 Updated July 23, 2026, 07:36 Want to learn how to extract handwritten data from PDFs easily for your business documents? Algodocs is a powerful AI platform developed based on the latest technologies to streamline your processes and free your team from annoying and error-prone manual data entry by offering fast, secure, and accurate document data extraction. It helps you get rid of your workforce from repetitive, time-consuming, and error-prone manual data entry tasks such as extracting handwritten data. With its AI capabilities, Algodocs gives one of, if not the best, user experiences and interfaces. Areas and applications of Algodocs include extracting handwriting, tables, key-value pairs, marks, and signatures from PDFs and image files. Algodocs offers a forever free subscription, with 50 pages processed every month. What is OCR? Optical Character Recognition (OCR) engines are primarily focused on machine-printed text and may produce low accuracy for handwritten text. Intelligent Character Recognition (ICR) is an advanced recognition system that is used to recognize handwritten text. This allows the automatic conversion of text in an image into letter codes that are usable within computer and text-processing applications. Although many processes involve computer-based operations and are implemented in a digital environment, paper is still widely used across most core business processes such as mortgage origination, order fulfillment, contracts, and other documents that usually require handwritten input and signatures. Nowadays, the digitalization of paper documents plays an important role, and deciding on the right data capture software is critical since handwriting recognition, unlike printed text recognition is a more complex task that usually involves advanced deep learning algorithms. How Does Algodocs Do It? Handwritten data extraction from PDFs is implemented by converting handwritten text into machine-printed text with high accuracy. With the Intelligent Character Recognition (ICR) of Algodocs, you can automate your document processing workflow and get rid of manual data entry. Scan your paper documents with handwritten text and let Algodocs automatically extract data and convert it to Excel or JSON. Let’s consider the following portion of a scanned document, which contains a table of five columns filled with handwritten numbers. If you upload this image to your account at Algodocs, you will see the following output, which has 100% accuracy. Algodocs uses advanced ICR engines trained with Artificial Intelligence algorithms and Deep Learning. Extracting data from various document formats could be a challenging task, especially when it comes to the necessity to extract specific data sets from files containing different types of documents that span across multiple pages. In these quick materials, we will list key features that are available in Algodocs, and which will help you to extract data from your documents using the Algodocs advanced AI engine without relying on templates or even labeling and training your files. What Are the Supported File Formats for Data Extraction? You may upload to Algodocs different types of files of different Image formats for data recognition and data extraction: Portable Document Format (PDF) Joint Photographic Experts Group (JPEG) Portable Graphics Format (PNG) Tagged Image File Format (TIFF) What Are the Supported Languages for Data Recognition? Algodocs supports data extraction from documents with Arabic, Armenian, Belorussian, Bulgarian, Catalan, Chinese, Croatian, Czech, Danish, Dutch, English, Estonian, Filipino, Finnish, French, German, Greek, Hebrew, Hindi, Icelandic, Indonesian, Italian, Japanese, Korean, Lao, Latvian, Lithuanian, Macedonian, Nepali, Norwegian, Persian, Polish, Portuguese, Russian, Serbian, Slovak, Slovenian, Spanish, Swedish, Telugu, Thai, Turkish, Ukrainian, Vietnamese, and many other up to 200 languages. How to Extract Handwritten Data from PDFs Using Algodocs Step 1: Log in to your Algodocs account and go to the home page which is the Dashboard. Step 2: Click on the Extractors tab, where you can see the Create button on the top right side, click on it. Step 3: Choose the Custom Extractor, for getting structured data from your documents as you need it. Step 4: A pop-up window will appear, upload your sample file to extract data from. Click on the Choose file, to locate the document from your device storage folder, then assign a name to the extractor. Once done, click on the Create Extractor button. It will populate under Extractors as below; in this article, our example is called “Sample1.” Step 5: Click on the blue button labeled “Manage”, to create the data to be extracted. Step 6: Click on Add to choose what type of extraction method you want, here, you may use rule-based and AI extraction. In this example, we will choose the AI extraction method, “Form Data Extraction.” After clicking on “Form data extraction”, the page that you want to extract data from will appear on a new page. On the Top Right corner click on” Continue”. Step 7:  The raw data from your document is displayed. Now use available filters to select certain data, and update, or format the extracted data as you like. Once done, write the Field/Table name on the Left side inside the blank text box, and click the SAVE button on the right side. Step 8:  Now go to the extracted date and choose the extractor name, from the first drop-down menu. The extractor will populate the extracted date information. To view the extracted data, click on the Rows, and the data will populate as below.  Then choose to download the data as Excel, JSON, or XML Final Thoughts As we can see Algodocs performs well in handwritten text extraction from scanned documents. Feel free to start a free subscription right now and test your handwritten scanned documents. You can use Algodocs for free forever, and you will have 50 pages per month. If you need to process a higher number of pages, then please see our affordable pricing plans. Please contact

Data Extraction, PDF

What is a PDF Parser?

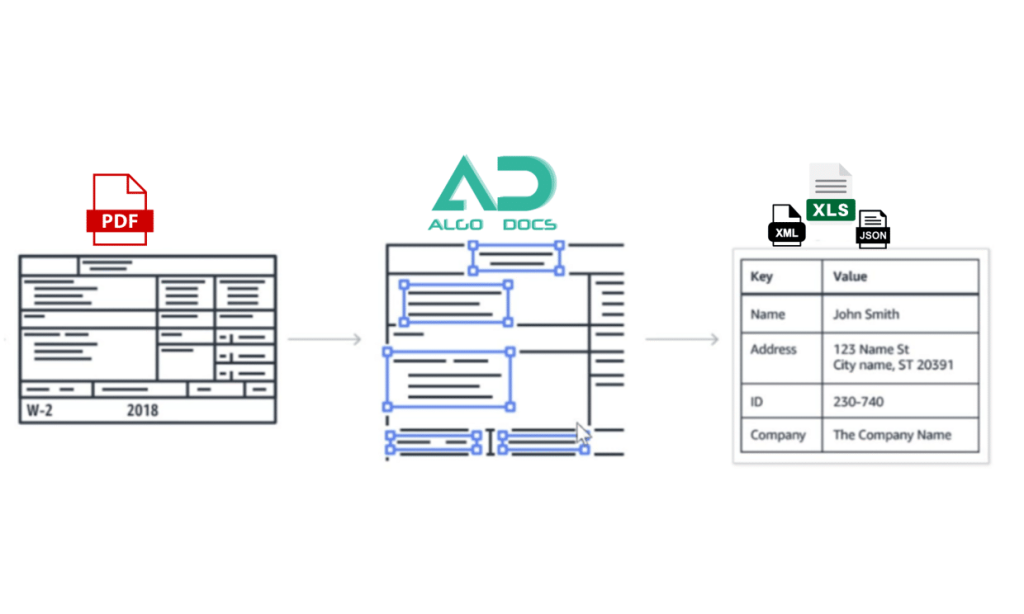
Back to Blog Table of contents On this page What is a PDF Parser? Home › Blog › Data Extraction › What is a PDF Parser? Categories Data Extraction PDF Tags ai platform for data extraction algodocs character recognition data extraction from images deep learning export extracted data to excel invoice process machine learning ocr api web-based ai platform for data extraction By Shubhankar Biswas Published October 13, 2025, 12:03 Updated July 29, 2026, 02:32 A PDF Parser is a program or a library that enables end-users and organizations to parse data from native PDF documents. Often, organizations need to parse PDF documents for specific fields such as Account Number, Date, Address, Bill to/from information, or parse tabular data. PDF Parsers are usually needed and used for processing and parsing data from large amounts of documents. On the other hand, when you have a handful of documents you simply go and copy the data you need from PDF documents manually and paste it to Excel or anywhere you need it to be. PDF Parsers enable end-users to get data from hundreds and thousands of PDF documents in real time by saving huge amounts of time and, thus, money. Parsing pdf documents isn’t an easy task. There are various ways native pdf documents are generated and parsing data from such pdf documents requires smart approaches. Parsed data from PDF documents greatly varies depending on the industry, which means the data parsed might also greatly change, which complicates the task. Parsing PDF medical forms, which contain specific fields such as First, Middle, and Last names, Sex, Date of Birth, etc. are very different from PDF purchase orders that contain mainly the items in the tabular form with such columns as Item No, Code, Quantity, Item Price, Amount, etc. Therefore, if PDF Parser produces just a bunch of text from a PDF document it does not make much sense for the end-user. What end-users or organizations require is the structured data parsed from PDF documents. In other words, PDF Parser should extract from PDF documents only the data the end-user needs and in the right structured format. For this, the PDF Parser must be smart and flexible enough to parse PDF documents with various layouts and data types. How to parse PDF documents with various layouts? Algodocs allows you to parse PDF documents of any complexity in their layouts and type of data. With the flexible extracting rules of Algodocs, you can parse data from PDFs with different layouts. It is very easy and quick to set up extractors in Algodocs for your PDF documents. We provide 100% free technical support and are ready to set up extractors for you. While we provide free support for creating extracting rules, you may check our help and support section if you wish to learn how to create extracting rules in Algodocs. Watch the following introductory video to get an idea of how it works in Algodocs. Feel free to start a free subscription right now and parse your pdf documents. You can use Algodocs free forever with 50 pages per month. If you need to process a higher number of pages, then please see our affordable pricing plans. If you have specific requirements and need a custom solution, please contact us. You Might Also Like PDF Data Extraction: The Best Tool and Techniques PDFs are ubiquitous in every organization, serving as the go-to format for sharing and exchanging business data. However, extracting, editing, or… Shubhankar Biswas October 13, 2025 PDF Image Extraction: A Comprehensive Guide To Extracting Image Data From Scanned Pdf Files In 2025 PDF image extraction is a challenging process. Without proper tools and technology, this process can be tedious and prone to errors, which can… Shubhankar Biswas September 1, 2025 Convert PDF to JSON – Convert PDF Documents to Structured JSON Objects Table of Contents Introduction Organizations in various industries widely use PDF documents, since no doubt PDF is a common document format for… Shubhankar Biswas October 13, 2025 Start extracting your data today No credit card required. Process up to 50 pages per month on the Forever Free plan. Book a Demo Get Started for Free

PDF

Convert PDF to JSON – Convert PDF Documents to Structured JSON Objects

Back to Blog Table of contents On this page Convert PDF to JSON – Convert PDF Documents to Structured JSON Objects Home › Blog › PDF › Convert PDF to JSON – Convert PDF Documents to Structured JSON Objects Categories PDF Tags ai platform for data extraction algodocs character recognition data extraction from images deep learning export extracted data to excel invoice process machine learning ocr api web-based ai platform for data extraction By Shubhankar Biswas Published October 13, 2025, 11:59 Updated July 21, 2026, 05:15 Introduction Organizations in various industries widely use PDF documents, since no doubt PDF is a common document format for businesses to transfer data. Purchase orders, Invoices, Agreements, and many more document types are interchanged in PDF formats. On the other hand, JSON is another format that represents data in a structured format, which is widely used in transferring data between web applications. As a result, Working with JSON is much easier than with PDF. Therefore, in this article, we will talk about PDF and JSON formats and how you can convert your PDF documents to JSON format. What is a PDF? PDF (Portable Document Format) was initially developed by Adobe® Systems in 1992 and is standardized as ISO 32000. What makes PDF so popular is it is independent of the application software, hardware, and operating system. Other than text and images PDF files may contain a variety of content such as annotations, form fields, layers, etc. There are many advantages of PDF format such as multi-dimensionality, which we have already mentioned – being able to contain various types of content, text, images, videos, vector graphics, interactive fields, hyperlinks, and buttons. Moreover, PDF documents are easily created and viewed on different devices.  Security in PDF was one of the primary concerns of Adobe® Systems. Therefore, PDFs have different access levels to protect the content and the whole document, such as passwords, digital signatures, and watermarks. However, some of the downsides of a PDF are the complexity of editing and especially extracting data from it. Moreover, PDFs are not generated in the same way, so different PDF files can be created in various ways, which complicates the task of extracting data from PDF documents. What is a JSON? JSON (JavaScript Object Notation) is a very popular data format, which appeared in the early 2000s. JSON is a language-independent data format and is used to transfer data between software applications, particularly web applications, usually between server and client.  Most of the API integrations are realized using JSON format for data transfer since it is very easy to work with JSON. Consider a JSON object called person, which contains the following information:{   “name”: “John”,   “surname”: “Doe”,   “age”: 25} Accessing fields of a JSON object is as simple as using the name of the object and the field name you want to access by separating them with a dot as follows: To access a person’s name we use person.name, which will give us “John” as a result. Similarly, we do for surname and age fields: person.surname, person.age Note how easy it is to access any field of a JSON object, which is definitely not compared to accessing specific information in the PDF document. How does JSON differ from PDF? Although PDF and JSON are both widely spread and used, there is a huge difference between PDF and JSON. The difference between them is simply in the purpose of their usage. PDF is mainly used for exchanging information between humans, since it contains text, graphics, illustrations such as images and videos, etc. On the other hand, JSON is mainly used between computer programs and different applications for communicating and exchanging data between each other. It is not an easy task for a human to read information from a JSON file, especially if it is a compressed one, but it is a perfect way to access information from JSON for a software application. The opposite goes for the PDF. Therefore, PDF and JSON become important, useful, and helpful only when they are used in the right place and for the right purpose. How to Convert PDF to JSON? Often, organizations need to transfer data to other programs for further processing. This data is often stored in PDF documents since businesses often speak to each other in a “PDF language”. However, extracting information from PDF documents can be challenging.  The simplest solution is that you can always copy and paste text from a PDF and send it to where it belongs. However, this simple approach has many problems, since first of all this will work only with native PDF files (not scans) for which you can even use some free PDF Parsers. Another problem even if your PDF documents are all native, it is not easy to copy the entire table from a PDF by maintaining its format, especially if the table spans over multiple pages, for example, 100 or 1000 pages. Additionally, often organizations need to extract specific data from PDFs, for example not the entire table, but instead specific rows or columns based on some conditions. Last, but not least, it is not worth spending your valuable time on menial data entry! Convert PDF documents to JSON with Algodocs Algodocs offers a perfect solution to extract any type of data from PDF documents and transfer it to other programs in real-time. Algodocs can extract fields and tables of any complexity from native as well as scanned PDF documents. You can convert your PDF documents to JSON in three steps with Algodocs. First, start by creating an extractor in Algodocs. Algodocs has some preprocessing operations that take some time depending on the number of pages your PDF document contains; usually, it is around 15-20 seconds. Then, go to the ‘Extracting Rules’ editor to create your extracting rules for every field you need to extract from your PDF documents. Similarly, if you need to extract tables from your PDF documents you can create extracting rules for tables by selecting ‘Table’ as the data type. After you are done with creating and extracting rules,

Algodocs

Extract handwritten text from scanned PDFs and images

Back to Blog Table of contents On this page Extract handwritten text from scanned PDFs and images Home › Blog › Algodocs › Extract handwritten text from scanned PDFs and images Categories Algodocs Tags ai platform for data extraction algodocs character recognition data extraction from images deep learning export extracted data to excel invoice process machine learning ocr api web-based ai platform for data extraction By Shubhankar Biswas Published October 13, 2025, 11:56 Updated November 10, 2025, 13:34 Optical Character Recognition (OCR) engines are primarily focused on machine-printed text and may produce low accuracy for handwritten text. Intelligent Character Recognition (ICR) is an advanced recognition system that is used to recognize handwritten text. This allows the automatic conversion of text in an image into letter codes that are usable within computer and text-processing applications. Although many processes involve computer-based operations and are implemented in a digital environment, paper is still vastly used across most core business processes such as mortgage origination, order fulfillment, contracts, and other documents that usually require handwritten input and signatures. Nowadays, the digitalization of paper documents plays an important role, and deciding on the right data capture software is critical since handwriting recognition unlike printed text recognition is a more complex task that usually involves advanced deep learning algorithms. Algodocs: Deep Learning Handwriting Recognizer Algodocs is capable of converting handwritten text into machine-printed text with high accuracy. With the ICR of Algodocs, you can automate your document processing workflow and get rid of manual data entry. Scan your paper documents with handwritten text and let Algodocs automatically extract data and convert it to Excel or JSON. Let’s consider the following portion of a scanned document, which contains a table of two columns filled with handwritten numbers. If you upload this image to your account at Algodocs, you will see the following output, which has 100% accuracy. Algodocs uses advanced ICR engines trained with Artificial Intelligence algorithms and Deep Learning. The above example includes mostly digits. Another example with characters is given below. The following is the extracted text by Algodocs from the above image. As we can see Algodocs performs well in handwritten text extraction from scanned documents. Feel free to start a free subscription right now and test your handwritten scanned documents. You can use Algodocs free forever with 50 pages per month. If you need to process a higher number of pages, then please see our affordable pricing plans. If you have specific requirements and need a custom solution, please contact us. You Might Also Like How to Extract Handwritten Data from PDFs with Algodocs? Table of Contents Want to learn how to extract handwritten data from PDFs easily for your business documents? Algodocs is a powerful AI platform… Shubhankar Biswas October 13, 2025 Conquer Multilingual Data Extraction: A Step-by-Step Guide with Algodocs Introduction Sick of spending hours manually extracting data from multilingual PDFs and images? It could be more efficient, prone to mistakes, and,… Shubhankar Biswas October 12, 2025 Why convert PDF to Word on MacBook (Mac)? Picture this: You have a PDF file that needs to be revised or a scanned document that you wish to convert into an editable format like an MS Word… Shubhankar Biswas October 12, 2025 Start extracting your data today No credit card required. Process up to 50 pages per month on the Forever Free plan. Book a Demo Get Started for Free

Image Data Extraction

A Guide on Extracting Tables From Low-Quality Scanned Documents

Back to Blog Table of contents On this page A Guide on Extracting Tables From Low-Quality Scanned Documents Home › Blog › Image Data Extraction › A Guide on Extracting Tables From Low-Quality Scanned Documents Categories Image Data Extraction Tags ai platform for data extraction algodocs character recognition data extraction from images deep learning export extracted data to excel invoice process machine learning ocr api web-based ai platform for data extraction By Shubhankar Biswas Published October 13, 2025, 11:52 Updated July 22, 2026, 09:54 Many companies deal with thousands of documents every month. Document workflow automation becomes vital for such companies as the number of documents increases. One of the most frequent and at the same time tedious operations when processing documents is reading data from tables, especially when documents are scanned PDFs or images. Automating table extraction from scanned documents and exporting them into Excel or JSON within seconds is a dream for every company dealing with manual data entry. Automating table data extraction from scanned documents and images reduces operational costs and saves a lot of time. In this article, we will talk about table extraction from scanned documents or images with low quality. You, most probably, came across some online tools that can extract tabular data from documents. However, there are a few that really work with low-quality scanned documents or images taken by a mobile device. Optical Character Recognition (OCR) is the technology used for converting scanned images into text. However, standard OCR tools require you to apply certain image processing operations on the images before you can apply OCR on them. Without manual pre-processing, OCR will fail in most cases, and accuracy will be low. Unfortunately, even with pre-processing operations free OCR tools produce poor performance. How to extract tables from scanned PDFs and images with low quality? Algodocs has an advanced AI-powered OCR engine that automatically handles any type of scanned PDF or image with a low quality. Algodocs accepts either colorful scanned images, black and white, or any other settings and extracts data with high accuracy. Algodocs can process scanned images with as low a dpi as 75. If you have scanned PDFs or images with low quality, then Algodocs is the right solution for you. You may start a free subscription right now and test your own scanned documents since we offer a free subscription (forever) with 50 pages per month. If you need to process a higher number of pages, then please see our affordable pricing plans. Please read our article on the basic steps for table extraction from documents here: Extract tables from PDF and scanned documents Algodocs: the best software tool to extract tables from scanned PDFs and images Consider the portions of the scanned documents below and the tables that Algodocs extracted from them. Example #1 Sample scanned image with low-quality (black and white) Extracted table by Algodocs. Example #2 Extracted table by Algodocs As you can see, the accuracy of Algodocs is perfect even with low-quality scans. However, there are cases when scanned images may cause Algodocs to make mistakes concerning small characters such as punctuation or other symbols (points, commas, date separators, etc.). Let’s have a look at the example below with a scanned image and see what Algodocs could extract from it. The extracted table from the above-scanned image is shown below. As you can see, there are numbers that are extracted with wrong decimal separators (indicated in red circles), i.e. a decimal point is mistakenly recognized as a comma. This is due to the dark background that some rows have on the image. With the help of flexible extracting rules of Algodocs, the workaround is quick and simple. Whenever you have low-quality scanned PDFs of images, we always advise you to follow the steps explained below. Step1. Remove all points and commas from the numbers We apply the ‘Search & Replace’ filter in Algodocs by using regular expressions as the search type. We apply this rule to all the columns in the example below, but you can restrict this rule to a specific column when needed. In order to find all dots or commas we use .|, as the search term and we leave empty the second field (replace by this), since we simply want to remove them. Step 2. Convert all numbers to their previous format Since we removed all points and commas from numbers, they actually increased, i.e. multiplied by 100 we can say (2,378.63 became 237863). Therefore, since we know that our numbers had 2 decimal places, we can divide all numbers by 100 to get the original numbers. The ‘Arithmetic Operation’ filter helps us implement exactly this. We divide numbers by 100 in the last column as shown in the example below. You may apply this filter to other columns too. That’s it. We got numbers in their original form with 100% accuracy! The same approach can be applied to other symbols when you have documents with a low quality. Please, contact us if you need any assistance. You Might Also Like How to Extract Handwritten Data from PDFs with Algodocs? Table of Contents Want to learn how to extract handwritten data from PDFs easily for your business documents? Algodocs is a powerful AI platform… Shubhankar Biswas October 13, 2025 Data Extraction for Legal Industry : How Intelligent Document Processing (IDP) Can Transform Legal Industry Document Workflow The global law and legal services industry is expected to reach $1,591.56 billion by the end of 2032, according to a report. The legal industry… Shubhankar Biswas October 12, 2025 Extract Tables from Images with AlgoDocs Extract Tables from Images with AlgoDocs One might find themselves overwhelmed by a deluge of paperwork—orders, checks, articles—all containing… Ibrahim Nalbant June 20, 2024 Start extracting your data today No credit card required. Process up to 50 pages per month on the Forever Free plan. Book a Demo Get Started for Free

Algodocs, PDF

Why convert PDF to Word on MacBook (Mac)?

Back to Blog Table of contents On this page Why convert PDF to Word on MacBook (Mac)? Home › Blog › Algodocs › Why convert PDF to Word on MacBook (Mac)? Categories Algodocs By Shubhankar Biswas Published October 12, 2025, 19:49 Updated July 20, 2026, 07:02 Picture this: You have a PDF file that needs to be revised or a scanned document that you wish to convert into an editable format like an MS Word document. Perhaps you have to work on a task and receive source files that cannot be changed and are saved in PDF or image format. Frustrating, right? That is when the miracles of converting PDF to Word come into existence. Yes, it is like taking your boring PDFs and probably turning them into lively and easily manageable Word docs. Converting PDFs to Word opens a new world of possibilities. Features include text editing, table editing or adding, and even the modification of images within the official document. Further, it creates the basis for exporting extracted data directly into other used tools like accounting ones so that everyone is in sync (metaphorically speaking!). Accessibility is another factor. Converting files from PDF to Word lets more people, including decision-makers, access the content. AI data extraction adds another layer of awesomeness to your PDF to Word conversion. You can pull out tables, key-value pairs, marks, figures, and even handwritten notes. Therefore, no matter whether you are a financer, a student, a worker in any data-driven field, or an ordinary user who is trying to simplify your digital life. We provide you with some tools that provide accurate results regardless of the device and OS used. As a case study, this article will discuss in detail how to convert PDF to Word on MacBook (Mac). This is where AI comes in and helps you take it up a notch. Built-in Mac Tools for PDF to Word Conversion Mac users, rejoice! You have a couple of tools integrated into your operating system. These tools effectively convert PDF to Word. First on the list is the Preview which is your go-to basic PDF viewer. This is not only a viewer for PDFs, you can also convert them to Word using it! Just launch the PDF in Preview, go up to the ‘File’ header, click on ‘Export,’ and select, ‘Word’ under the format. Boom, you’re done! Pages is next – it is a word processor developed by Apple Inc. PDF to Word conversion isn’t very popular. However, it’s a secret weapon in this area. The Open button brings you back to the menus. From there, go to ‘File,’ then ‘Open,’ and select the PDF you want. Pages will attempt to translate the PDF into editable Word format. But these built-in tools, may find it difficult to work with complicated PDFs and images. They certainly are not the best solution when trying to extract tables, handwritten, and processing multilanguage documents. To clarify, don’t think that you’re doomed to use these options for eternity; in the next sections, more sophisticated tools are presented. Free Online PDF to Word Converters Alright, okay, let’s assume you are interested in a quick-fix solution and you don’t want to download anything onto your computer. That is where free online PDF to Word converters come in helpful. Fortunately, there are many tools available today, all of which have their advantages and nuances. Some tools you can use are Smallpdf, PDF Candy, and Online2PDF. These tools let you upload your PDFs and a Word file for download format will be ready. It’s convenient and perfect for those one-off conversions. Still, free online converters are not without their perks. They might struggle with preserving complex formatting or handling large files. Plus, their data extraction capabilities can be limited. If you need to pull specific information from your PDF, like tables, key value pairs, or images, you might have to manually copying the wanted data. If you’re looking for more advanced data extraction capabilities, consider exploring AI-powered alternatives like Algodocs. This platform not only converts PDFs to Word but also intelligently extracts data like tables, handwriting, and key-value pairs. We’ll dive deeper into AI-powered solutions later in this guide. Paid PDF to Word Converter Software for Mac If you are looking to work with PDFs locally without accessing the Internet, purchasing PDF to Word conversion software will be useful. Such tools provide additional features like powerful editing and OCR data extraction. Adobe Acrobat Pro is the undisputed champion in the PDF world. It’s the best tool for PDF reading and editing. It offers a free trial to convert PDFs into Word format. Additionally, it comes with sophisticated OCR functions for importing and updating scanned PDFs. Well, Adobe Acrobat Pro is not the only way to make life easier; PDFelement and PDFpenPro offer similar features for an affordable price. The tools mentioned above work well for basic editing and conversion. However, they can’t handle multipage tables, handwritten, low-quality, or multi-language documents. If you’re looking for a solution beyond basic conversion, you might want to try AI-powered PDF to Word tools like Algodocs. They use artificial intelligence to improve precision, address complications with structure, and even specific data from your scanned files like PDFs and images. It feels like having a professional secretary for your document conversion needs. Unleashing the Power of AI Data Extraction for PDF Conversion Let’s face it—not all PDFs are the same. Some might contain only plain text, while others may contain lots of tables, figures, diagrams, handwriting, etc. Converting such files leads to formatting issues and lost data. That’s where the magic of AI data extraction comes in. But AI doesn’t stop there. It can even recognize handwritten text and extract data from the most complicated tables. Introducing Algodocs If you’re looking for a powerful AI-powered PDF conversion and data extraction solution, look no further than Algodocs. This web-based platform harnesses the latest technologies to deliver exceptional results. Algodocs can extract a wide range of data from your

Scroll to Top